- **Description**:
This dataset is primarily based off the AI2D Dataset (see
[here](https://prior.allenai.org/projects/diagram-understanding)).
See [Section 4.1](https://arxiv.org/pdf/2310.12128) of our paper for the
AI2D-Caption dataset annotation process.
- **Homepage** :
- **Source code** :
[`tfds.datasets.ai2dcaption.Builder`](https://github.com/tensorflow/datasets/tree/master/tensorflow_datasets/datasets/ai2dcaption/ai2dcaption_dataset_builder.py)
- **Versions**:
- **`1.0.0`** (default): Initial release.
- **Download size** : `Unknown size`
- **Dataset size** : `2.01 GiB`
- **Auto-cached**
([documentation](https://www.tensorflow.org/datasets/performances#auto-caching)):
No
- **Splits**:
| Split | Examples |
|---|---|
| `'auditor_llm_training_examples'` | 30 |
| `'gpt4v'` | 4,903 |
| `'llava_15'` | 4,902 |
| `'planner_llm_training_examples'` | 30 |
| `'test'` | 75 |
- **Feature structure**:
FeaturesDict({
'caption': Text(shape=(), dtype=string),
'entities': Sequence({
'bounds': BBoxFeature(shape=(4,), dtype=float32),
'cat': ClassLabel(shape=(), dtype=int64, num_classes=10),
'from': Text(shape=(), dtype=string),
'id': Text(shape=(), dtype=string),
'label': Text(shape=(), dtype=string),
'to': Text(shape=(), dtype=string),
'type': ClassLabel(shape=(), dtype=int64, num_classes=5),
}),
'image': Image(shape=(None, None, 3), dtype=uint8, description=The image of the diagram.),
'image_filename': Text(shape=(), dtype=string),
'layout': ClassLabel(shape=(), dtype=int64, num_classes=7),
'relationships': Sequence(Text(shape=(), dtype=string)),
'topic': ClassLabel(shape=(), dtype=int64, num_classes=4),
})
- **Feature documentation**:
| Feature | Class | Shape | Dtype | Description |
|---|---|---|---|---|
| | FeaturesDict | | | |
| caption | Text | | string | |
| entities | Sequence | | | |
| entities/bounds | BBoxFeature | (4,) | float32 | |
| entities/cat | ClassLabel | | int64 | |
| entities/from | Text | | string | |
| entities/id | Text | | string | |
| entities/label | Text | | string | |
| entities/to | Text | | string | |
| entities/type | ClassLabel | | int64 | |
| image | Image | (None, None, 3) | uint8 | The image of the diagram. |
| image_filename | Text | | string | Image filename. e.g. "1337.png" |
| layout | ClassLabel | | int64 | |
| relationships | Sequence(Text) | (None,) | string | |
| topic | ClassLabel | | int64 | |
- **Supervised keys** (See
[`as_supervised` doc](https://www.tensorflow.org/datasets/api_docs/python/tfds/load#args)):
`None`
- **Figure**
([tfds.show_examples](https://www.tensorflow.org/datasets/api_docs/python/tfds/visualization/show_examples)):
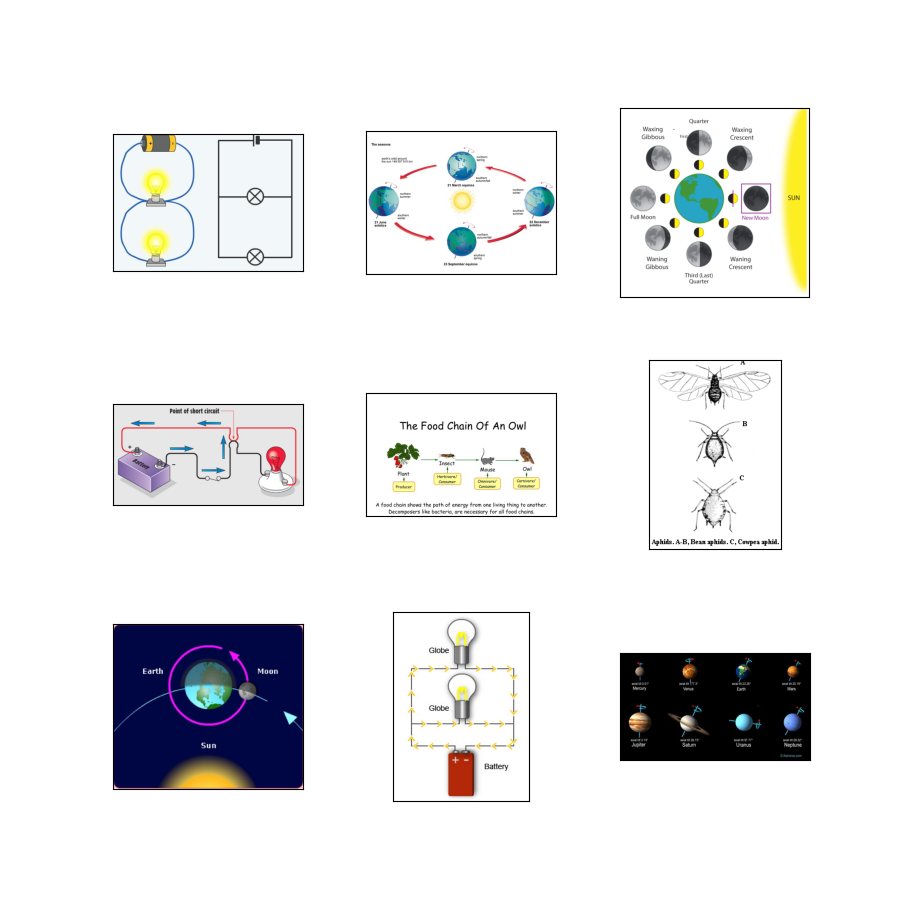
- **Examples** ([tfds.as_dataframe](https://www.tensorflow.org/datasets/api_docs/python/tfds/as_dataframe)):
- **Citation**:
@inproceedings{Zala2024DiagrammerGPT,
author = {Abhay Zala and Han Lin and Jaemin Cho and Mohit Bansal},
title = {DiagrammerGPT: Generating Open-Domain, Open-Platform Diagrams via LLM Planning},
year = {2024},
booktitle = {COLM},
}