# clevr
- **Description**:
CLEVR is a diagnostic dataset that tests a range of visual reasoning abilities.
It contains minimal biases and has detailed annotations describing the kind of
reasoning each question requires.
- **Additional Documentation** :
[Explore on Papers With Code](https://paperswithcode.com/dataset/clevr)
- **Homepage** :
- **Source code** :
[`tfds.datasets.clevr.Builder`](https://github.com/tensorflow/datasets/tree/master/tensorflow_datasets/datasets/clevr/clevr_dataset_builder.py)
- **Versions**:
- `3.0.0`: No release notes.
- **`3.1.0`** (default): Add question/answer text.
- **Download size** : `17.72 GiB`
- **Dataset size** : `17.75 GiB`
- **Auto-cached**
([documentation](https://www.tensorflow.org/datasets/performances#auto-caching)):
No
- **Splits**:
| Split | Examples |
|---|---|
| `'test'` | 15,000 |
| `'train'` | 70,000 |
| `'validation'` | 15,000 |
- **Feature structure**:
FeaturesDict({
'file_name': Text(shape=(), dtype=string),
'image': Image(shape=(None, None, 3), dtype=uint8),
'objects': Sequence({
'3d_coords': Tensor(shape=(3,), dtype=float32),
'color': ClassLabel(shape=(), dtype=int64, num_classes=8),
'material': ClassLabel(shape=(), dtype=int64, num_classes=2),
'pixel_coords': Tensor(shape=(3,), dtype=float32),
'rotation': float32,
'shape': ClassLabel(shape=(), dtype=int64, num_classes=3),
'size': ClassLabel(shape=(), dtype=int64, num_classes=2),
}),
'question_answer': Sequence({
'answer': Text(shape=(), dtype=string),
'question': Text(shape=(), dtype=string),
}),
})
- **Feature documentation**:
| Feature | Class | Shape | Dtype | Description |
|---|---|---|---|---|
| | FeaturesDict | | | |
| file_name | Text | | string | |
| image | Image | (None, None, 3) | uint8 | |
| objects | Sequence | | | |
| objects/3d_coords | Tensor | (3,) | float32 | |
| objects/color | ClassLabel | | int64 | |
| objects/material | ClassLabel | | int64 | |
| objects/pixel_coords | Tensor | (3,) | float32 | |
| objects/rotation | Tensor | | float32 | |
| objects/shape | ClassLabel | | int64 | |
| objects/size | ClassLabel | | int64 | |
| question_answer | Sequence | | | |
| question_answer/answer | Text | | string | |
| question_answer/question | Text | | string | |
- **Supervised keys** (See
[`as_supervised` doc](https://www.tensorflow.org/datasets/api_docs/python/tfds/load#args)):
`None`
- **Figure**
([tfds.show_examples](https://www.tensorflow.org/datasets/api_docs/python/tfds/visualization/show_examples)):
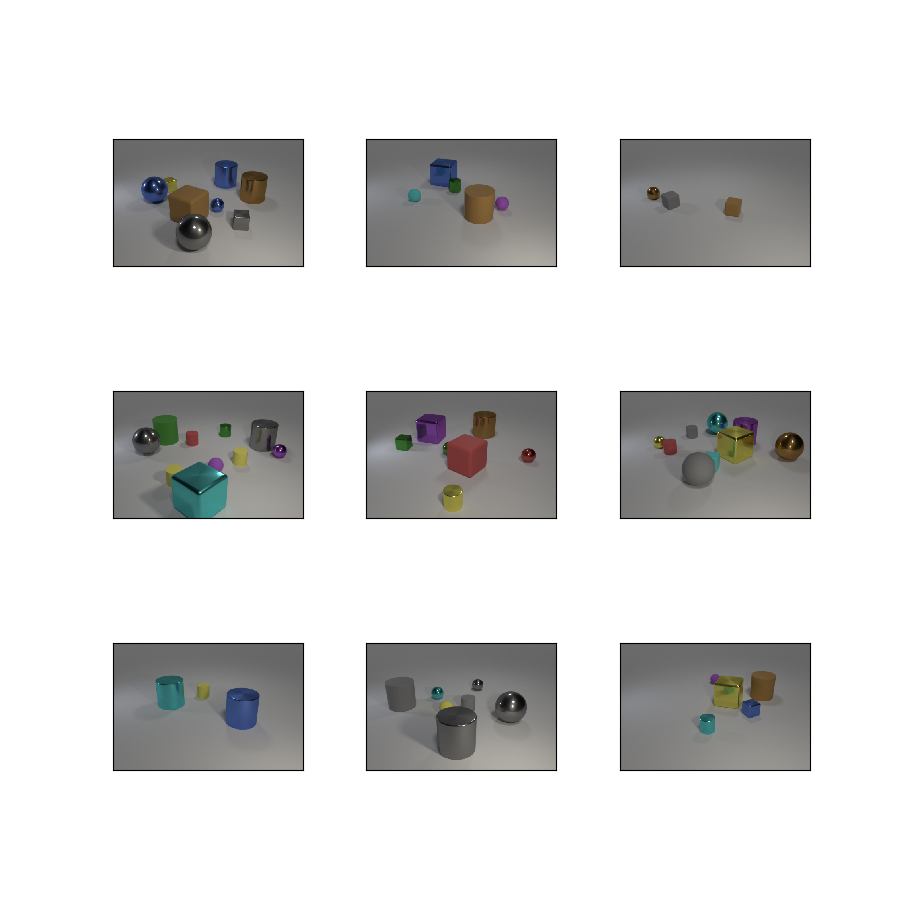
- **Examples** ([tfds.as_dataframe](https://www.tensorflow.org/datasets/api_docs/python/tfds/as_dataframe)):
- **Citation**:
@inproceedings{johnson2017clevr,
title={ {CLEVR}: A diagnostic dataset for compositional language and elementary visual reasoning},
author={Johnson, Justin and Hariharan, Bharath and van der Maaten, Laurens and Fei-Fei, Li and Lawrence Zitnick, C and Girshick, Ross},
booktitle={Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition},
year={2017}
}