# coco_captions
- **Description**:
COCO is a large-scale object detection, segmentation, and captioning dataset.
This version contains images, bounding boxes, labels, and captions from COCO
2014, split into the subsets defined by Karpathy and Li (2015). This effectively
divides the original COCO 2014 validation data into new 5000-image validation
and test sets, plus a "restval" set containing the remaining \~30k images. All
splits have caption annotations.
- **Additional Documentation** :
[Explore on Papers With Code](https://paperswithcode.com/dataset/coco-captions)
- **Config description**: This version contains images, bounding boxes and
labels for the 2014 version.
- **Homepage** :
- **Source code** :
[`tfds.object_detection.CocoCaptions`](https://github.com/tensorflow/datasets/tree/master/tensorflow_datasets/object_detection/coco_captions.py)
- **Versions**:
- **`1.1.0`** (default): No release notes.
- **Download size** : `37.61 GiB`
- **Dataset size** : `18.83 GiB`
- **Auto-cached**
([documentation](https://www.tensorflow.org/datasets/performances#auto-caching)):
No
- **Splits**:
| Split | Examples |
|---|---|
| `'restval'` | 30,504 |
| `'test'` | 5,000 |
| `'train'` | 82,783 |
| `'val'` | 5,000 |
- **Feature structure**:
FeaturesDict({
'captions': Sequence({
'id': int64,
'text': string,
}),
'image': Image(shape=(None, None, 3), dtype=uint8),
'image/filename': Text(shape=(), dtype=string),
'image/id': int64,
'objects': Sequence({
'area': int64,
'bbox': BBoxFeature(shape=(4,), dtype=float32),
'id': int64,
'is_crowd': bool,
'label': ClassLabel(shape=(), dtype=int64, num_classes=80),
}),
})
- **Feature documentation**:
| Feature | Class | Shape | Dtype | Description |
|---|---|---|---|---|
| | FeaturesDict | | | |
| captions | Sequence | | | |
| captions/id | Tensor | | int64 | |
| captions/text | Tensor | | string | |
| image | Image | (None, None, 3) | uint8 | |
| image/filename | Text | | string | |
| image/id | Tensor | | int64 | |
| objects | Sequence | | | |
| objects/area | Tensor | | int64 | |
| objects/bbox | BBoxFeature | (4,) | float32 | |
| objects/id | Tensor | | int64 | |
| objects/is_crowd | Tensor | | bool | |
| objects/label | ClassLabel | | int64 | |
- **Supervised keys** (See
[`as_supervised` doc](https://www.tensorflow.org/datasets/api_docs/python/tfds/load#args)):
`None`
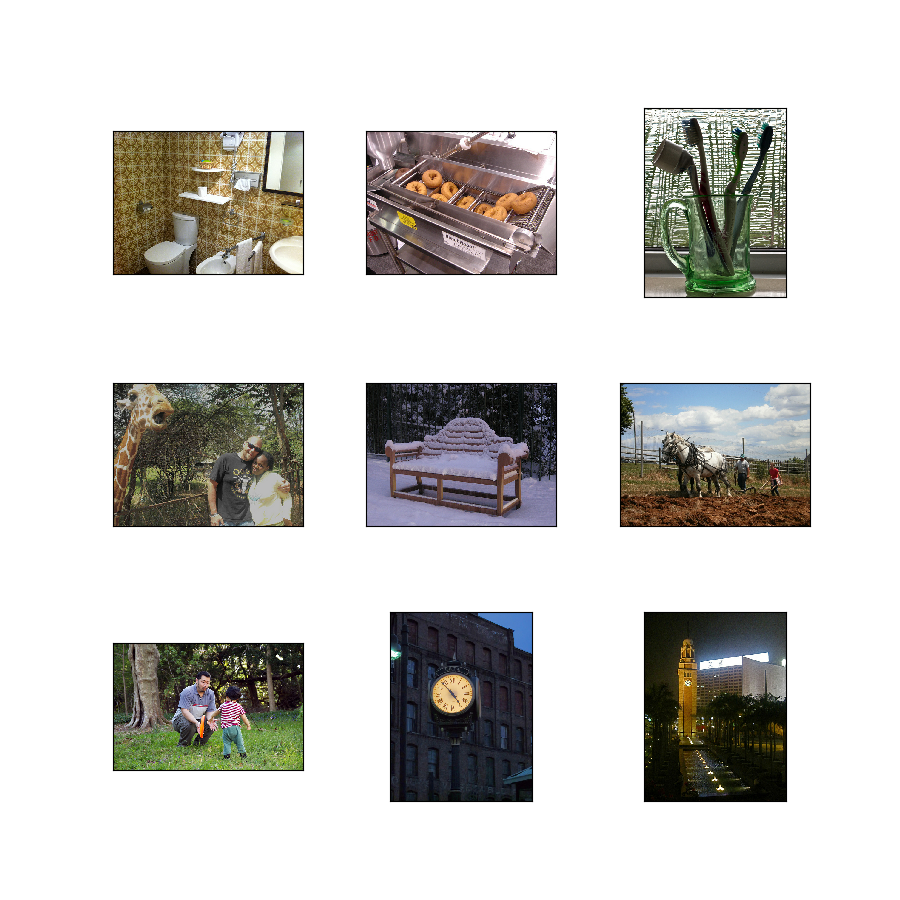
- **Figure**
([tfds.show_examples](https://www.tensorflow.org/datasets/api_docs/python/tfds/visualization/show_examples)):
- **Examples** ([tfds.as_dataframe](https://www.tensorflow.org/datasets/api_docs/python/tfds/as_dataframe)):
- **Citation**:
@article{DBLP:journals/corr/LinMBHPRDZ14,
author = {Tsung{-}Yi Lin and
Michael Maire and
Serge J. Belongie and
Lubomir D. Bourdev and
Ross B. Girshick and
James Hays and
Pietro Perona and
Deva Ramanan and
Piotr Doll{'{a} }r and
C. Lawrence Zitnick},
title = {Microsoft {COCO:} Common Objects in Context},
journal = {CoRR},
volume = {abs/1405.0312},
year = {2014},
url = {http://arxiv.org/abs/1405.0312},
archivePrefix = {arXiv},
eprint = {1405.0312},
timestamp = {Mon, 13 Aug 2018 16:48:13 +0200},
biburl = {https://dblp.org/rec/bib/journals/corr/LinMBHPRDZ14},
bibsource = {dblp computer science bibliography, https://dblp.org}
}@inproceedings{DBLP:conf/cvpr/KarpathyL15,
author = {Andrej Karpathy and
Fei{-}Fei Li},
title = {Deep visual-semantic alignments for generating image
descriptions},
booktitle = { {IEEE} Conference on Computer Vision and Pattern Recognition,
{CVPR} 2015, Boston, MA, USA, June 7-12, 2015},
pages = {3128--3137},
publisher = { {IEEE} Computer Society},
year = {2015},
url = {https://doi.org/10.1109/CVPR.2015.7298932},
doi = {10.1109/CVPR.2015.7298932},
timestamp = {Wed, 16 Oct 2019 14:14:50 +0200},
biburl = {https://dblp.org/rec/conf/cvpr/KarpathyL15.bib},
bibsource = {dblp computer science bibliography, https://dblp.org}
}
## coco_captions/2014 (default config)