> [!WARNING]
> **Warning:** Manual download required. See instructions below.
- **Description**:
Controlled Noisy Web Labels is a collection of \~212,000 URLs to images in which
every image is carefully annotated by 3-5 labeling professionals by Google Cloud
Data Labeling Service. Using these annotations, it establishes the first
benchmark of controlled real-world label noise from the web.
We provide the Red Mini-ImageNet (real-world web noise) and Blue Mini-ImageNet
configs:
- controlled_noisy_web_labels/mini_imagenet_red
- controlled_noisy_web_labels/mini_imagenet_blue
Each config contains ten variants with ten noise-levels p from 0% to 80%. The
validation set has clean labels and is shared across all noisy training sets.
Therefore, each config has the following splits:
- train_00
- train_05
- train_10
- train_15
- train_20
- train_30
- train_40
- train_50
- train_60
- train_80
- validation
The details for dataset construction and analysis can be found in the paper. All
images are resized to 84x84 resolution.
- **Homepage** :
- **Source code** :
[`tfds.image_classification.controlled_noisy_web_labels.ControlledNoisyWebLabels`](https://github.com/tensorflow/datasets/tree/master/tensorflow_datasets/image_classification/controlled_noisy_web_labels/controlled_noisy_web_labels.py)
- **Versions**:
- **`1.0.0`** (default): Initial release.
- **Download size** : `1.83 MiB`
- **Manual download instructions** : This dataset requires you to
download the source data manually into `download_config.manual_dir`
(defaults to `~/tensorflow_datasets/downloads/manual/`):
In order to manually download this data, a user must perform the
following operations:
1. Download the splits and the annotations [here](https://storage.googleapis.com/cnlw/dataset_no_images.zip)
2. Extract dataset_no_images.zip to dataset_no_images/.
3. Download all images in dataset_no_images/mini-imagenet-annotations.json into a new folder named dataset_no_images/noisy_images/. The output filename must agree with the image id provided in mini-imagenet-annotations.json. For example, if "image/id": "5922767e5677aef4", then the downloaded image should be dataset_no_images/noisy_images/5922767e5677aef4.jpg. 4.Register on and download ILSVRC2012_img_train.tar and ILSVRC2012_img_val.tar.
The resulting directory structure may then be processed by TFDS:
- dataset_no_images/
- mini-imagenet/
- class_name.txt
- split/
- blue_noise_nl_0.0
- blue_noise_nl_0.1
- ...
- red_noise_nl_0.0
- red_noise_nl_0.1
- ...
- clean_validation
- mini-imagenet-annotations.json
- ILSVRC2012_img_train.tar
- ILSVRC2012_img_val.tar
- noisy_images/
- 5922767e5677aef4.jpg
- **Auto-cached**
([documentation](https://www.tensorflow.org/datasets/performances#auto-caching)):
No
- **Feature structure**:
FeaturesDict({
'id': Text(shape=(), dtype=string),
'image': Image(shape=(None, None, 3), dtype=uint8),
'is_clean': bool,
'label': ClassLabel(shape=(), dtype=int64, num_classes=100),
})
- **Feature documentation**:
| Feature | Class | Shape | Dtype | Description |
|---|---|---|---|---|
| | FeaturesDict | | | |
| id | Text | | string | |
| image | Image | (None, None, 3) | uint8 | |
| is_clean | Tensor | | bool | |
| label | ClassLabel | | int64 | |
- **Supervised keys** (See
[`as_supervised` doc](https://www.tensorflow.org/datasets/api_docs/python/tfds/load#args)):
`('image', 'label')`
- **Citation**:
@inproceedings{jiang2020beyond,
title={Beyond synthetic noise: Deep learning on controlled noisy labels},
author={Jiang, Lu and Huang, Di and Liu, Mason and Yang, Weilong},
booktitle={International Conference on Machine Learning},
pages={4804--4815},
year={2020},
organization={PMLR}
}
## controlled_noisy_web_labels/mini_imagenet_red (default config)
- **Dataset size** : `1.19 GiB`
- **Splits**:
| Split | Examples |
|---|---|
| `'train_00'` | 50,000 |
| `'train_05'` | 50,000 |
| `'train_10'` | 50,000 |
| `'train_15'` | 50,000 |
| `'train_20'` | 50,000 |
| `'train_30'` | 49,985 |
| `'train_40'` | 50,010 |
| `'train_50'` | 49,962 |
| `'train_60'` | 50,000 |
| `'train_80'` | 50,008 |
| `'validation'` | 5,000 |
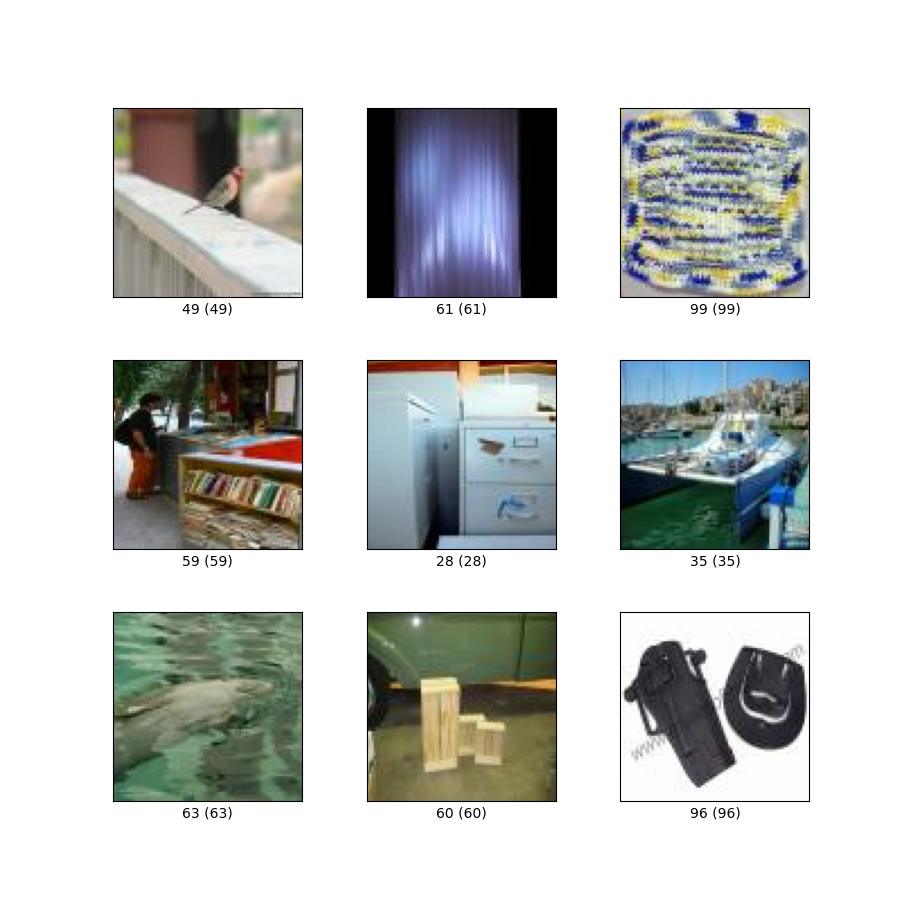
- **Figure** ([tfds.show_examples](https://www.tensorflow.org/datasets/api_docs/python/tfds/visualization/show_examples)):
- **Examples** ([tfds.as_dataframe](https://www.tensorflow.org/datasets/api_docs/python/tfds/as_dataframe)):
## controlled_noisy_web_labels/mini_imagenet_blue
- **Dataset size** : `1.39 GiB`
- **Splits**:
| Split | Examples |
|---|---|
| `'train_00'` | 60,000 |
| `'train_05'` | 60,000 |
| `'train_10'` | 60,000 |
| `'train_15'` | 60,000 |
| `'train_20'` | 60,000 |
| `'train_30'` | 60,000 |
| `'train_40'` | 60,000 |
| `'train_50'` | 60,000 |
| `'train_60'` | 60,000 |
| `'train_80'` | 60,000 |
| `'validation'` | 5,000 |
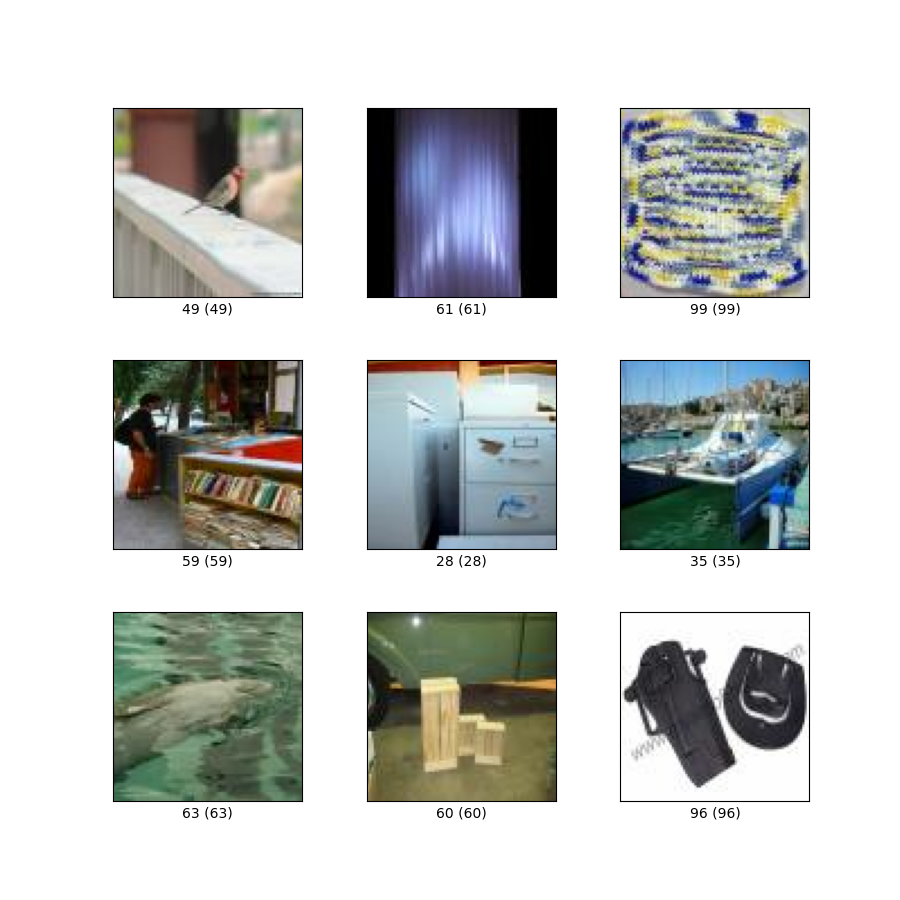
- **Figure** ([tfds.show_examples](https://www.tensorflow.org/datasets/api_docs/python/tfds/visualization/show_examples)):
- **Examples** ([tfds.as_dataframe](https://www.tensorflow.org/datasets/api_docs/python/tfds/as_dataframe)):