# dmlab
- **Description**:
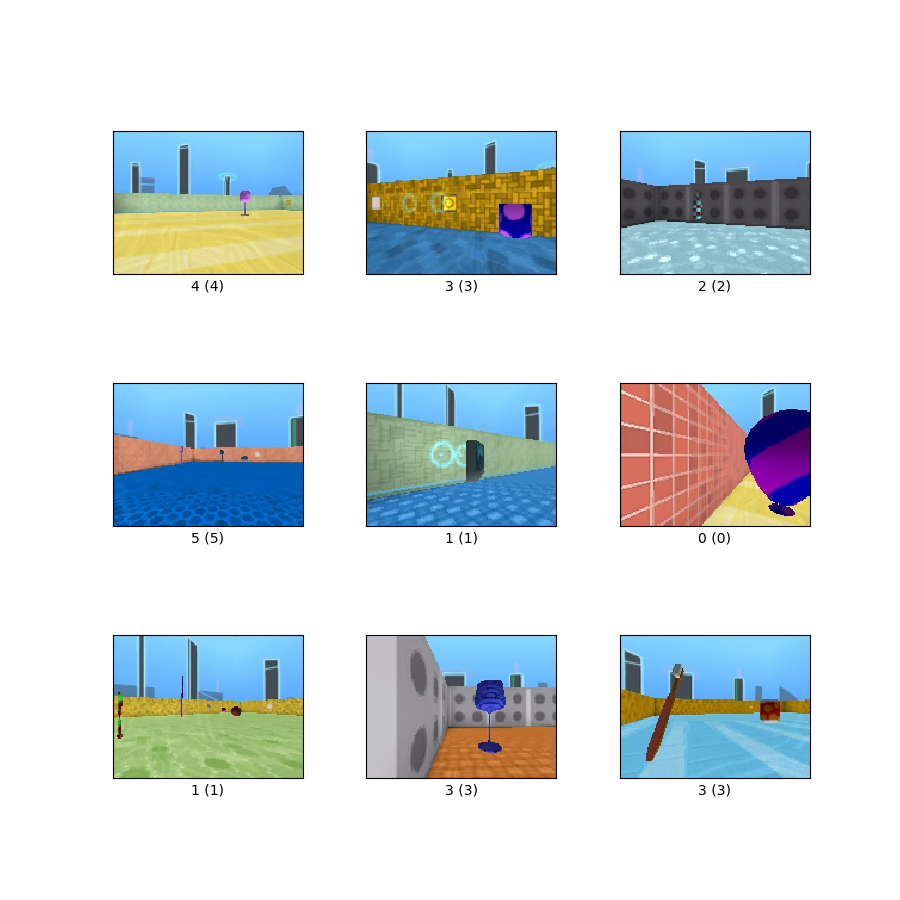
The Dmlab dataset contains frames observed by the agent acting in the DeepMind
Lab environment, which are annotated by the distance between the agent and
various objects present in the environment. The goal is to is to evaluate the
ability of a visual model to reason about distances from the visual input in 3D
environments. The Dmlab dataset consists of 360x480 color images in 6 classes.
The classes are {close, far, very far} x {positive reward, negative reward}
respectively.
- **Homepage** :
- **Source code** :
[`tfds.image_classification.Dmlab`](https://github.com/tensorflow/datasets/tree/master/tensorflow_datasets/image_classification/dmlab.py)
- **Versions**:
- **`2.0.1`** (default): No release notes.
- **Download size** : `2.81 GiB`
- **Dataset size** : `3.13 GiB`
- **Auto-cached**
([documentation](https://www.tensorflow.org/datasets/performances#auto-caching)):
No
- **Splits**:
| Split | Examples |
|---|---|
| `'test'` | 22,735 |
| `'train'` | 65,550 |
| `'validation'` | 22,628 |
- **Feature structure**:
FeaturesDict({
'filename': Text(shape=(), dtype=string),
'image': Image(shape=(360, 480, 3), dtype=uint8),
'label': ClassLabel(shape=(), dtype=int64, num_classes=6),
})
- **Feature documentation**:
| Feature | Class | Shape | Dtype | Description |
|---|---|---|---|---|
| | FeaturesDict | | | |
| filename | Text | | string | |
| image | Image | (360, 480, 3) | uint8 | |
| label | ClassLabel | | int64 | |
- **Supervised keys** (See
[`as_supervised` doc](https://www.tensorflow.org/datasets/api_docs/python/tfds/load#args)):
`('image', 'label')`
- **Figure**
([tfds.show_examples](https://www.tensorflow.org/datasets/api_docs/python/tfds/visualization/show_examples)):
- **Examples** ([tfds.as_dataframe](https://www.tensorflow.org/datasets/api_docs/python/tfds/as_dataframe)):
- **Citation**:
@article{zhai2019visual,
title={The Visual Task Adaptation Benchmark},
author={Xiaohua Zhai and Joan Puigcerver and Alexander Kolesnikov and
Pierre Ruyssen and Carlos Riquelme and Mario Lucic and
Josip Djolonga and Andre Susano Pinto and Maxim Neumann and
Alexey Dosovitskiy and Lucas Beyer and Olivier Bachem and
Michael Tschannen and Marcin Michalski and Olivier Bousquet and
Sylvain Gelly and Neil Houlsby},
year={2019},
eprint={1910.04867},
archivePrefix={arXiv},
primaryClass={cs.CV},
url = {https://arxiv.org/abs/1910.04867}
}