- **Description**:
Open Images is a dataset of \~9M images that have been annotated with image-level
labels and object bounding boxes.
The training set of V4 contains 14.6M bounding boxes for 600 object classes on
1.74M images, making it the largest existing dataset with object location
annotations. The boxes have been largely manually drawn by professional
annotators to ensure accuracy and consistency. The images are very diverse and
often contain complex scenes with several objects (8.4 per image on average).
Moreover, the dataset is annotated with image-level labels spanning thousands of
classes.
- **Additional Documentation** :
[Explore on Papers With Code](https://paperswithcode.com/dataset/open-images-v4)
- **Homepage** :
- **Source code** :
[`tfds.datasets.open_images_v4.Builder`](https://github.com/tensorflow/datasets/tree/master/tensorflow_datasets/datasets/open_images_v4/open_images_v4_dataset_builder.py)
- **Versions**:
- **`2.0.0`** (default): New split API ()
- **Download size** : `565.11 GiB`
- **Auto-cached**
([documentation](https://www.tensorflow.org/datasets/performances#auto-caching)):
No
- **Splits**:
| Split | Examples |
|---|---|
| `'test'` | 125,436 |
| `'train'` | 1,743,042 |
| `'validation'` | 41,620 |
- **Feature structure**:
FeaturesDict({
'bobjects': Sequence({
'bbox': BBoxFeature(shape=(4,), dtype=float32),
'is_depiction': int8,
'is_group_of': int8,
'is_inside': int8,
'is_occluded': int8,
'is_truncated': int8,
'label': ClassLabel(shape=(), dtype=int64, num_classes=601),
'source': ClassLabel(shape=(), dtype=int64, num_classes=6),
}),
'image': Image(shape=(None, None, 3), dtype=uint8),
'image/filename': Text(shape=(), dtype=string),
'objects': Sequence({
'confidence': int32,
'label': ClassLabel(shape=(), dtype=int64, num_classes=19995),
'source': ClassLabel(shape=(), dtype=int64, num_classes=6),
}),
'objects_trainable': Sequence({
'confidence': int32,
'label': ClassLabel(shape=(), dtype=int64, num_classes=7186),
'source': ClassLabel(shape=(), dtype=int64, num_classes=6),
}),
})
- **Feature documentation**:
| Feature | Class | Shape | Dtype | Description |
|---|---|---|---|---|
| | FeaturesDict | | | |
| bobjects | Sequence | | | |
| bobjects/bbox | BBoxFeature | (4,) | float32 | |
| bobjects/is_depiction | Tensor | | int8 | |
| bobjects/is_group_of | Tensor | | int8 | |
| bobjects/is_inside | Tensor | | int8 | |
| bobjects/is_occluded | Tensor | | int8 | |
| bobjects/is_truncated | Tensor | | int8 | |
| bobjects/label | ClassLabel | | int64 | |
| bobjects/source | ClassLabel | | int64 | |
| image | Image | (None, None, 3) | uint8 | |
| image/filename | Text | | string | |
| objects | Sequence | | | |
| objects/confidence | Tensor | | int32 | |
| objects/label | ClassLabel | | int64 | |
| objects/source | ClassLabel | | int64 | |
| objects_trainable | Sequence | | | |
| objects_trainable/confidence | Tensor | | int32 | |
| objects_trainable/label | ClassLabel | | int64 | |
| objects_trainable/source | ClassLabel | | int64 | |
- **Supervised keys** (See
[`as_supervised` doc](https://www.tensorflow.org/datasets/api_docs/python/tfds/load#args)):
`None`
- **Citation**:
@article{OpenImages,
author = {Alina Kuznetsova and
Hassan Rom and
Neil Alldrin and
Jasper Uijlings and
Ivan Krasin and
Jordi Pont-Tuset and
Shahab Kamali and
Stefan Popov and
Matteo Malloci and
Tom Duerig and
Vittorio Ferrari},
title = {The Open Images Dataset V4: Unified image classification,
object detection, and visual relationship detection at scale},
year = {2018},
journal = {arXiv:1811.00982}
}
@article{OpenImages2,
author = {Krasin, Ivan and
Duerig, Tom and
Alldrin, Neil and
Ferrari, Vittorio
and Abu-El-Haija, Sami and
Kuznetsova, Alina and
Rom, Hassan and
Uijlings, Jasper and
Popov, Stefan and
Kamali, Shahab and
Malloci, Matteo and
Pont-Tuset, Jordi and
Veit, Andreas and
Belongie, Serge and
Gomes, Victor and
Gupta, Abhinav and
Sun, Chen and
Chechik, Gal and
Cai, David and
Feng, Zheyun and
Narayanan, Dhyanesh and
Murphy, Kevin},
title = {OpenImages: A public dataset for large-scale multi-label and
multi-class image classification.},
journal = {Dataset available from
https://storage.googleapis.com/openimages/web/index.html},
year={2017}
}
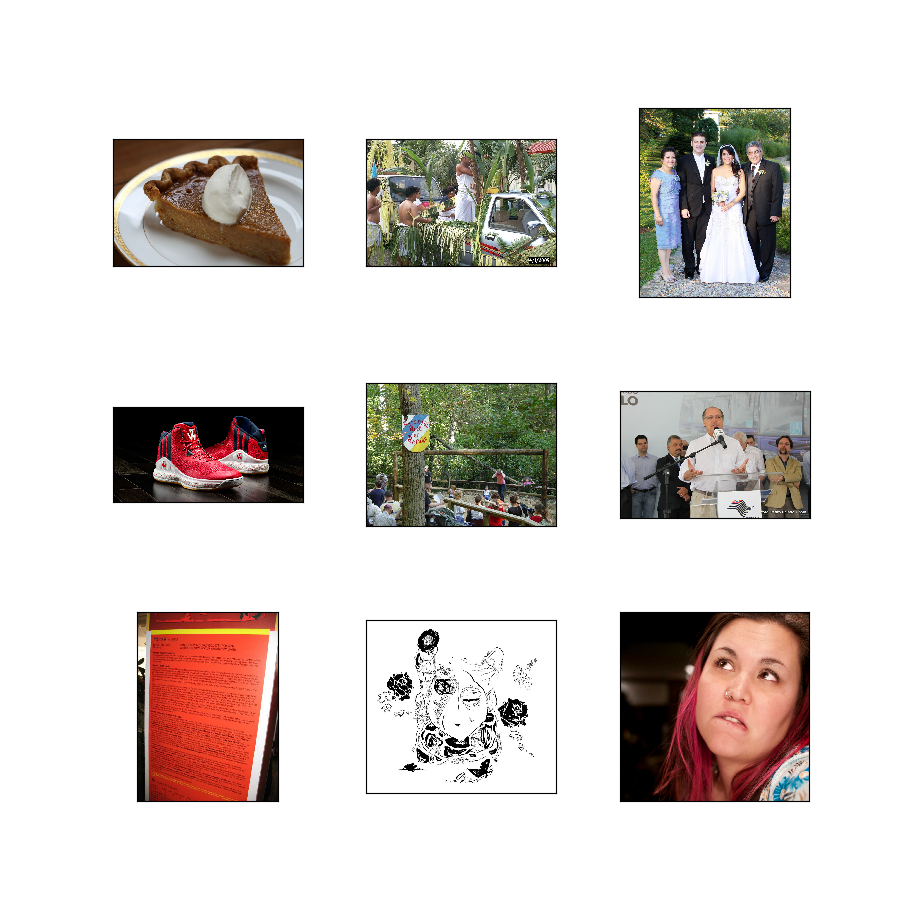
## open_images_v4/original (default config)
- **Config description**: Images at their original resolution and quality.
- **Dataset size** : `562.42 GiB`
- **Figure**
([tfds.show_examples](https://www.tensorflow.org/datasets/api_docs/python/tfds/visualization/show_examples)):
- **Examples** ([tfds.as_dataframe](https://www.tensorflow.org/datasets/api_docs/python/tfds/as_dataframe)):
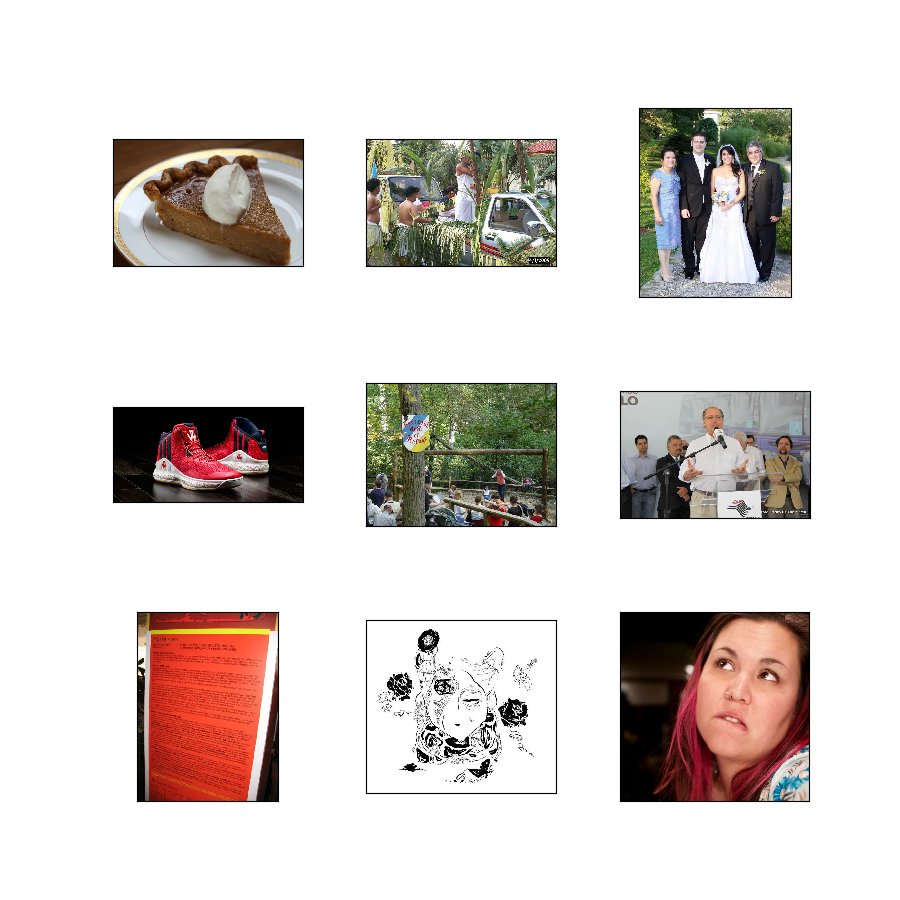
## open_images_v4/300k
- **Config description**: Images have roughly 300,000 pixels, at 72 JPEG
quality.
- **Dataset size** : `81.92 GiB`
- **Figure**
([tfds.show_examples](https://www.tensorflow.org/datasets/api_docs/python/tfds/visualization/show_examples)):
- **Examples** ([tfds.as_dataframe](https://www.tensorflow.org/datasets/api_docs/python/tfds/as_dataframe)):
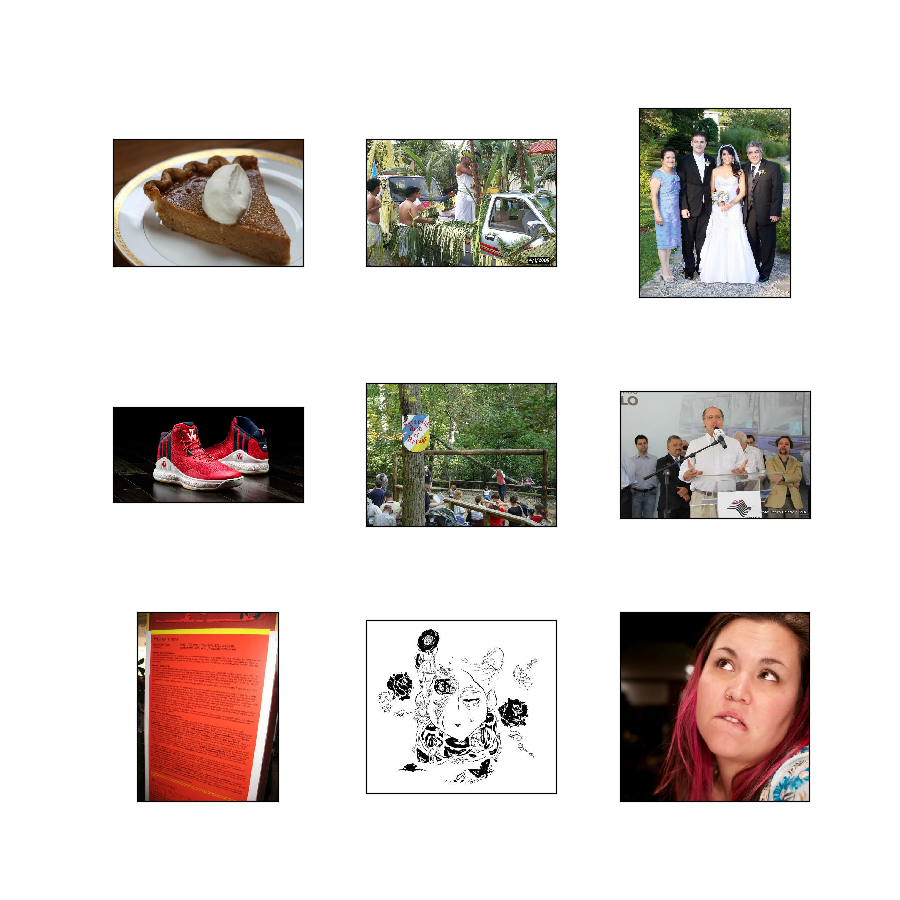
## open_images_v4/200k
- **Config description**: Images have roughly 200,000 pixels, at 72 JPEG
quality.
- **Dataset size** : `60.70 GiB`
- **Figure**
([tfds.show_examples](https://www.tensorflow.org/datasets/api_docs/python/tfds/visualization/show_examples)):
- **Examples** ([tfds.as_dataframe](https://www.tensorflow.org/datasets/api_docs/python/tfds/as_dataframe)):