> [!WARNING]
> **Warning:** Manual download required. See instructions below.
- **Description**:
Wikipedia - Image/Caption Matching Kaggle Competition.
This competition is organized by the
[Research team](https://research.wikimedia.org/) at the
[Wikimedia Foundation](https://wikimediafoundation.org/) in collaboration with
Google Research and a few external collaborators. This competition is based on
the [WIT dataset](https://github.com/google-research-datasets/wit) published by
Google Research as detailed in
this[SIGIR paper](https://dl.acm.org/doi/abs/10.1145/3404835.3463257).
In this competition, you'll build a model that automatically retrieves the text
closest to an image. Specifically, you'll train your model to associate given
images with article titles or complex captions, in multiple languages. The best
models will account for the semantic granularity of Wikipedia images. If
successful, you'll be contributing to the accessibility of the largest online
encyclopedia. The millions of Wikipedia readers and edietors will be able to
more easily understand, search, and describe media at scale. As a result, you'll
contribute to an open model to improve learning for all.
- **Homepage** :
- **Source code** :
[`tfds.vision_language.wit_kaggle.WitKaggle`](https://github.com/tensorflow/datasets/tree/master/tensorflow_datasets/vision_language/wit_kaggle/wit_kaggle.py)
- **Versions**:
- `1.0.0`: Initial release. It provides the train and test datasets from
the Wikipedia - Image/Caption Matching Kaggle competition
().
The goal of the competition is to build a model that automatically
retrieves the text closest to an image. Specifically, the model shuld be
trained to associate given images with article titles or complex
captions, in multiple languages. The best models will account for the
semantic granularity of Wikipedia images.
Note that this release doesn't provide the ground truth for the test
set, as it hasn't been provided by the Kaggle competition yet.
Note that not all of the training observations have corresponding image
data. The released images exclude all images containing humans. For
samples which are not associated with image data, the following image
features are used: `image` is a byte-64 encoded blank image, `embedding`
is a vector of 2048 zeros.
The samples released for the competition can be loaded as:
tfds.load("wit_kaggle/train_with_extended_features")
tfds.load("wit_kaggle/test_without_gold")
- `1.0.1`: Optimize Beam pipeline to avoid strugglers, ignoring rows
without an image URL. Also added more Beam counters.
- **`1.0.2`** (default): Fixes parsing of boolean fields.
- **Download size** : `Unknown size`
- **Manual download instructions** : This dataset requires you to
download the source data manually into `download_config.manual_dir`
(defaults to `~/tensorflow_datasets/downloads/manual/`):
Depending on the config called, manual_dir should contain some of the
following subdirectories:
- train
- train-{0000x}-of-00005.tsv.zip
- image_data_train/
- image_pixels/
- train_image_pixels_part-00{000-199}.csv.gz
- resnet_embeddings/
- train_resnet_embeddings_part-00{000-214}.csv.gz
- test
- test.tsv.zip
- image_data_test/
- image_pixels/
- test_image_pixels_part-0000{0-4}.csv
- resnet_embeddings/
- test_resnet_embeddings_part-0000{0-9}.csv
Registration at is needed
to get the links to download the dataset.
- **Auto-cached**
([documentation](https://www.tensorflow.org/datasets/performances#auto-caching)):
No
- **Supervised keys** (See
[`as_supervised` doc](https://www.tensorflow.org/datasets/api_docs/python/tfds/load#args)):
`('image_url', 'caption_title_and_reference_description')`
- **Citation**:
@article{srinivasan2021wit,
title={WIT: Wikipedia-based Image Text Dataset for Multimodal Multilingual Machine Learning},
author={Srinivasan, Krishna and Raman, Karthik and Chen, Jiecao and Bendersky, Michael and Najork, Marc},
journal={arXiv preprint arXiv:2103.01913},
year={2021}
}
## wit_kaggle/train_with_extended_features (default config)
- **Config description**: Training samples for the Wikipedia-Image/Caption
Matching competition.
- **Dataset size** : `1.16 TiB`
- **Splits**:
| Split | Examples |
|---|---|
| `'train_with_extended_features'` | 37,046,386 |
- **Feature structure**:
FeaturesDict({
'attribution_passes_lang_id': bool,
'caption_alt_text_description': Text(shape=(), dtype=string),
'caption_attribution_description': Text(shape=(), dtype=string),
'caption_reference_description': Text(shape=(), dtype=string),
'caption_title_and_reference_description': Text(shape=(), dtype=string),
'context_page_description': Text(shape=(), dtype=string),
'context_section_description': Text(shape=(), dtype=string),
'embedding': Tensor(shape=(2048,), dtype=float32),
'hierarchical_section_title': Text(shape=(), dtype=string),
'image': Image(shape=(None, None, 3), dtype=uint8),
'image_url': Text(shape=(), dtype=string),
'is_main_image': bool,
'language': Text(shape=(), dtype=string),
'metadata_url': Text(shape=(), dtype=string),
'mime_type': Text(shape=(), dtype=string),
'original_height': int32,
'original_width': int32,
'page_changed_recently': bool,
'page_title': Text(shape=(), dtype=string),
'page_url': Text(shape=(), dtype=string),
'section_title': Text(shape=(), dtype=string),
})
- **Feature documentation**:
| Feature | Class | Shape | Dtype | Description |
|---|---|---|---|---|
| | FeaturesDict | | | |
| attribution_passes_lang_id | Tensor | | bool | |
| caption_alt_text_description | Text | | string | |
| caption_attribution_description | Text | | string | |
| caption_reference_description | Text | | string | |
| caption_title_and_reference_description | Text | | string | |
| context_page_description | Text | | string | |
| context_section_description | Text | | string | |
| embedding | Tensor | (2048,) | float32 | |
| hierarchical_section_title | Text | | string | |
| image | Image | (None, None, 3) | uint8 | |
| image_url | Text | | string | |
| is_main_image | Tensor | | bool | |
| language | Text | | string | |
| metadata_url | Text | | string | |
| mime_type | Text | | string | |
| original_height | Tensor | | int32 | |
| original_width | Tensor | | int32 | |
| page_changed_recently | Tensor | | bool | |
| page_title | Text | | string | |
| page_url | Text | | string | |
| section_title | Text | | string | |
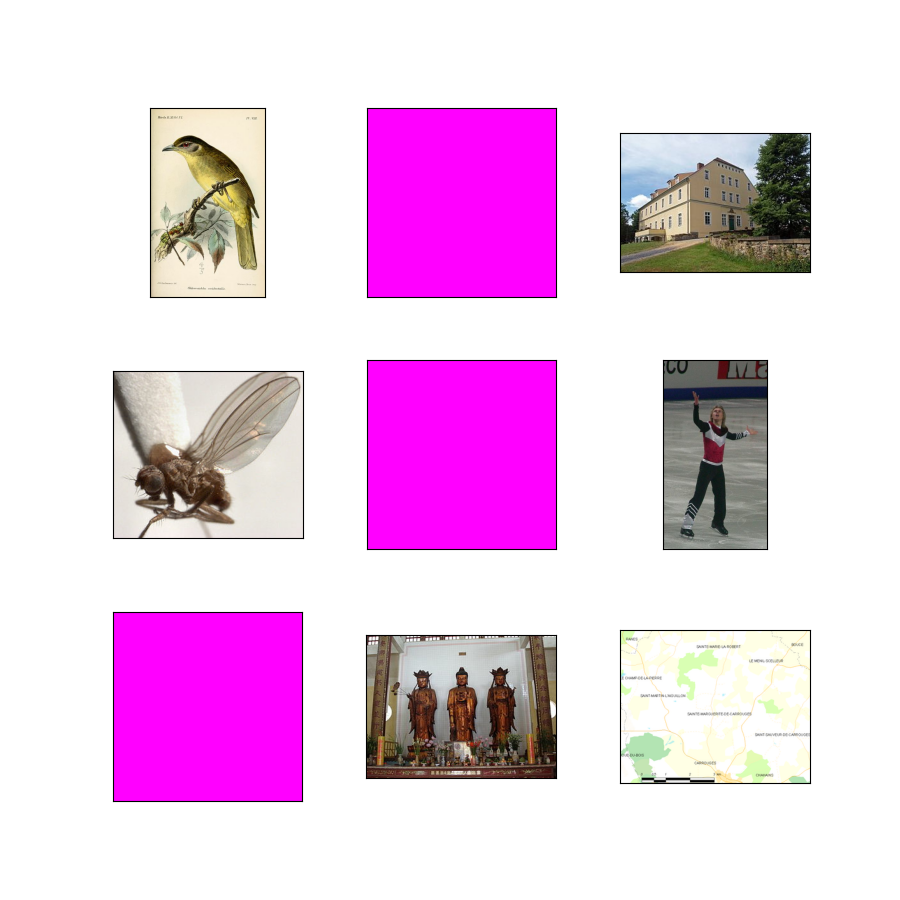
- **Figure** ([tfds.show_examples](https://www.tensorflow.org/datasets/api_docs/python/tfds/visualization/show_examples)):
- **Examples** ([tfds.as_dataframe](https://www.tensorflow.org/datasets/api_docs/python/tfds/as_dataframe)):
## wit_kaggle/test_without_gold
- **Config description**: Test samples (without gold answers) for the
Wikipedia-Image/Caption Matching competition.
- **Dataset size** : `3.37 GiB`
- **Splits**:
| Split | Examples |
|---|---|
| `'test_without_gold'` | 92,366 |
- **Feature structure**:
FeaturesDict({
'caption_title_and_reference_description': Text(shape=(), dtype=string),
'embedding': Tensor(shape=(2048,), dtype=float32),
'id': Text(shape=(), dtype=string),
'image': Image(shape=(None, None, 3), dtype=uint8),
'image_url': Text(shape=(), dtype=string),
'metadata_url': Text(shape=(), dtype=string),
})
- **Feature documentation**:
| Feature | Class | Shape | Dtype | Description |
|---|---|---|---|---|
| | FeaturesDict | | | |
| caption_title_and_reference_description | Text | | string | |
| embedding | Tensor | (2048,) | float32 | |
| id | Text | | string | |
| image | Image | (None, None, 3) | uint8 | |
| image_url | Text | | string | |
| metadata_url | Text | | string | |
- **Figure** ([tfds.show_examples](https://www.tensorflow.org/datasets/api_docs/python/tfds/visualization/show_examples)):
- **Examples** ([tfds.as_dataframe](https://www.tensorflow.org/datasets/api_docs/python/tfds/as_dataframe)):