TFDS provides a collection of ready-to-use datasets for use with TensorFlow, Jax, and other Machine Learning frameworks.
It handles downloading and preparing the data deterministically and constructing a [`tf.data.Dataset`](https://www.tensorflow.org/api_docs/python/tf/data/Dataset) (or `np.array`).
> [!NOTE]
> **Note:** Do not confuse [TFDS](https://www.tensorflow.org/datasets) (this library) with [`tf.data`](https://www.tensorflow.org/api_docs/python/tf/data) (TensorFlow API to build efficient data pipelines). TFDS is a high level wrapper around [`tf.data`](https://www.tensorflow.org/api_docs/python/tf/data). If you're not familiar with this API, we encourage you to read [the official tf.data guide](https://www.tensorflow.org/guide/data) first.
|---|---|---|---|
| [View on TensorFlow.org](https://www.tensorflow.org/datasets/overview) | [Run in Google Colab](https://colab.research.google.com/github/tensorflow/datasets/blob/master/docs/overview.ipynb) | [View source on GitHub](https://github.com/tensorflow/datasets/blob/master/docs/overview.ipynb) | [Download notebook](https://storage.googleapis.com/tensorflow_docs/datasets/docs/overview.ipynb) |
## Installation
TFDS exists in two packages:
- `pip install tensorflow-datasets`: The stable version, released every few months.
- `pip install tfds-nightly`: Released every day, contains the last versions of the datasets.
This colab uses `tfds-nightly`:
pip install -q tfds-nightly tensorflow matplotlib
import matplotlib.pyplot as plt
import numpy as np
import tensorflow as tf
import tensorflow_datasets as tfds
## Find available datasets
All dataset builders are subclass of [`tfds.core.DatasetBuilder`](https://www.tensorflow.org/datasets/api_docs/python/tfds/core/DatasetBuilder). To get the list of available builders, use [`tfds.list_builders()`](https://www.tensorflow.org/datasets/api_docs/python/tfds/list_builders) or look at our [catalog](https://www.tensorflow.org/datasets/catalog/overview).
tfds.list_builders()
```
['abstract_reasoning',
'accentdb',
'aeslc',
'aflw2k3d',
'ag_news_subset',
'ai2_arc',
'ai2_arc_with_ir',
'ai2dcaption',
'aloha_mobile',
'amazon_us_reviews',
'anli',
'answer_equivalence',
'arc',
'asimov_dilemmas_auto_val',
'asimov_dilemmas_scifi_train',
'asimov_dilemmas_scifi_val',
'asimov_injury_val',
'asimov_multimodal_auto_val',
'asimov_multimodal_manual_val',
'asimov_v2_constraints_with_rationale',
'asimov_v2_constraints_without_rationale',
'asimov_v2_injuries',
'asimov_v2_videos',
'asqa',
'asset',
'assin2',
'asu_table_top_converted_externally_to_rlds',
'austin_buds_dataset_converted_externally_to_rlds',
'austin_sailor_dataset_converted_externally_to_rlds',
'austin_sirius_dataset_converted_externally_to_rlds',
'bair_robot_pushing_small',
'bc_z',
'bccd',
'beans',
'bee_dataset',
'beir',
'berkeley_autolab_ur5',
'berkeley_cable_routing',
'berkeley_fanuc_manipulation',
'berkeley_gnm_cory_hall',
'berkeley_gnm_recon',
'berkeley_gnm_sac_son',
'berkeley_mvp_converted_externally_to_rlds',
'berkeley_rpt_converted_externally_to_rlds',
'big_patent',
'bigearthnet',
'billsum',
'binarized_mnist',
'binary_alpha_digits',
'ble_wind_field',
'blimp',
'booksum',
'bool_q',
'bot_adversarial_dialogue',
'bridge',
'bridge_data_msr',
'bucc',
'c4',
'c4_wsrs',
'caltech101',
'caltech_birds2010',
'caltech_birds2011',
'cardiotox',
'cars196',
'cassava',
'cats_vs_dogs',
'celeb_a',
'celeb_a_hq',
'cfq',
'cherry_blossoms',
'chexpert',
'cifar10',
'cifar100',
'cifar100_n',
'cifar10_1',
'cifar10_corrupted',
'cifar10_h',
'cifar10_n',
'citrus_leaves',
'cityscapes',
'civil_comments',
'clevr',
'clic',
'clinc_oos',
'cmaterdb',
'cmu_franka_exploration_dataset_converted_externally_to_rlds',
'cmu_play_fusion',
'cmu_stretch',
'cnn_dailymail',
'coco',
'coco_captions',
'coil100',
'colorectal_histology',
'colorectal_histology_large',
'columbia_cairlab_pusht_real',
'common_voice',
'conll2002',
'conll2003',
'conq_hose_manipulation',
'controlled_noisy_web_labels',
'coqa',
'corr2cause',
'cos_e',
'cosmos_qa',
'covid19',
'covid19sum',
'covr',
'crema_d',
'criteo',
'cs_restaurants',
'curated_breast_imaging_ddsm',
'cycle_gan',
'd4rl_adroit_door',
'd4rl_adroit_hammer',
'd4rl_adroit_pen',
'd4rl_adroit_relocate',
'd4rl_antmaze',
'd4rl_mujoco_ant',
'd4rl_mujoco_halfcheetah',
'd4rl_mujoco_hopper',
'd4rl_mujoco_walker2d',
'dart',
'databricks_dolly',
'davis',
'deep1b',
'deep_weeds',
'definite_pronoun_resolution',
'dementiabank',
'diabetic_retinopathy_detection',
'diamonds',
'dices',
'div2k',
'dlr_edan_shared_control_converted_externally_to_rlds',
'dlr_sara_grid_clamp_converted_externally_to_rlds',
'dlr_sara_pour_converted_externally_to_rlds',
'dmlab',
'dobbe',
'doc_nli',
'dolma',
'dolphin_number_word',
'domainnet',
'downsampled_imagenet',
'drop',
'dsprites',
'dtd',
'duke_ultrasound',
'e2e_cleaned',
'efron_morris75',
'emnist',
'eraser_multi_rc',
'esnli',
'eth_agent_affordances',
'eurosat',
'fashion_mnist',
'flic',
'flores',
'fmb',
'food101',
'forest_fires',
'fractal20220817_data',
'fuss',
'gap',
'geirhos_conflict_stimuli',
'gem',
'genomics_ood',
'german_credit_numeric',
'gigaword',
'glove100_angular',
'glue',
'goemotions',
'gov_report',
'gpt3',
'gref',
'groove',
'grounded_scan',
'gsm8k',
'gtzan',
'gtzan_music_speech',
'hellaswag',
'higgs',
'hillstrom',
'horses_or_humans',
'howell',
'i_naturalist2017',
'i_naturalist2018',
'i_naturalist2021',
'iamlab_cmu_pickup_insert_converted_externally_to_rlds',
'imagenet2012',
'imagenet2012_corrupted',
'imagenet2012_fewshot',
'imagenet2012_multilabel',
'imagenet2012_real',
'imagenet2012_subset',
'imagenet_a',
'imagenet_lt',
'imagenet_pi',
'imagenet_r',
'imagenet_resized',
'imagenet_sketch',
'imagenet_v2',
'imagenette',
'imagewang',
'imdb_reviews',
'imperialcollege_sawyer_wrist_cam',
'io_ai_tech',
'irc_disentanglement',
'iris',
'istella',
'jaco_play',
'kaist_nonprehensile_converted_externally_to_rlds',
'kddcup99',
'kitti',
'kmnist',
'kuka',
'laion400m',
'lambada',
'lbpp',
'lfw',
'librispeech',
'librispeech_lm',
'libritts',
'ljspeech',
'lm1b',
'locomotion',
'lost_and_found',
'lsun',
'lvis',
'malaria',
'maniskill_dataset_converted_externally_to_rlds',
'math_dataset',
'math_qa',
'mctaco',
'media_sum',
'mimic_play',
'mlqa',
'mnist',
'mnist_corrupted',
'movie_lens',
'movie_rationales',
'movielens',
'moving_mnist',
'mrqa',
'mslr_web',
'mt_opt',
'mtnt',
'multi_news',
'multi_nli',
'multi_nli_mismatch',
'natural_instructions',
'natural_questions',
'natural_questions_open',
'newsroom',
'nsynth',
'nyu_depth_v2',
'nyu_door_opening_surprising_effectiveness',
'nyu_franka_play_dataset_converted_externally_to_rlds',
'nyu_rot_dataset_converted_externally_to_rlds',
'ogbg_molpcba',
'omniglot',
'open_images_challenge2019_detection',
'open_images_v4',
'openbookqa',
'opinion_abstracts',
'opinosis',
'opus',
'oxford_flowers102',
'oxford_iiit_pet',
'para_crawl',
'pass',
'patch_camelyon',
'paws_wiki',
'paws_x_wiki',
'penguins',
'pet_finder',
'pg19',
'piqa',
'places365_small',
'placesfull',
'plant_leaves',
'plant_village',
'plantae_k',
'plex_robosuite',
'pneumonia_mnist',
'protein_net',
'q_re_cc',
'qa4mre',
'qasc',
'qm9',
'quac',
'quality',
'quickdraw_bitmap',
'race',
'radon',
'real_toxicity_prompts',
'reddit',
'reddit_disentanglement',
'reddit_tifu',
'ref_coco',
'resisc45',
'rlu_atari',
'rlu_atari_checkpoints',
'rlu_atari_checkpoints_ordered',
'rlu_control_suite',
'rlu_dmlab_explore_object_rewards_few',
'rlu_dmlab_explore_object_rewards_many',
'rlu_dmlab_rooms_select_nonmatching_object',
'rlu_dmlab_rooms_watermaze',
'rlu_dmlab_seekavoid_arena01',
'rlu_locomotion',
'rlu_rwrl',
'robo_set',
'robomimic_mg',
'robomimic_mh',
'robomimic_ph',
'robonet',
'robosuite_panda_pick_place_can',
'roboturk',
'rock_paper_scissors',
'rock_you',
's3o4d',
'salient_span_wikipedia',
'samsum',
'savee',
'scan',
'scene_parse150',
'schema_guided_dialogue',
'sci_tail',
'scicite',
'scientific_papers',
'scrolls',
'segment_anything',
'sentiment140',
'shapes3d',
'sift1m',
'simpte',
'siscore',
'smallnorb',
'smart_buildings',
'smartwatch_gestures',
'snli',
'so2sat',
'speech_commands',
'spoc_robot',
'spoken_digit',
'squad',
'squad_question_generation',
'stanford_dogs',
'stanford_hydra_dataset_converted_externally_to_rlds',
'stanford_kuka_multimodal_dataset_converted_externally_to_rlds',
'stanford_mask_vit_converted_externally_to_rlds',
'stanford_online_products',
'stanford_robocook_converted_externally_to_rlds',
'star_cfq',
'starcraft_video',
'stl10',
'story_cloze',
'summscreen',
'sun397',
'super_glue',
'svhn_cropped',
'symmetric_solids',
'taco_play',
'tao',
'tatoeba',
'ted_hrlr_translate',
'ted_multi_translate',
'tedlium',
'tf_flowers',
'the300w_lp',
'tidybot',
'tiny_shakespeare',
'titanic',
'tokyo_u_lsmo_converted_externally_to_rlds',
'toto',
'trec',
'trivia_qa',
'tydi_qa',
'uc_merced',
'ucf101',
'ucsd_kitchen_dataset_converted_externally_to_rlds',
'ucsd_pick_and_place_dataset_converted_externally_to_rlds',
'uiuc_d3field',
'unified_qa',
'universal_dependencies',
'unnatural_instructions',
'usc_cloth_sim_converted_externally_to_rlds',
'user_libri_audio',
'user_libri_text',
'utaustin_mutex',
'utokyo_pr2_opening_fridge_converted_externally_to_rlds',
'utokyo_pr2_tabletop_manipulation_converted_externally_to_rlds',
'utokyo_saytap_converted_externally_to_rlds',
'utokyo_xarm_bimanual_converted_externally_to_rlds',
'utokyo_xarm_pick_and_place_converted_externally_to_rlds',
'vctk',
'vima_converted_externally_to_rlds',
'viola',
'visual_domain_decathlon',
'voc',
'voxceleb',
'voxforge',
'wake_vision',
'waymo_open_dataset',
'web_graph',
'web_nlg',
'web_questions',
'webvid',
'wider_face',
'wiki40b',
'wiki_auto',
'wiki_bio',
'wiki_dialog',
'wiki_table_questions',
'wiki_table_text',
'wikiann',
'wikihow',
'wikipedia',
'wikipedia_toxicity_subtypes',
'wine_quality',
'winogrande',
'wit',
'wit_kaggle',
'wmt13_translate',
'wmt14_translate',
'wmt15_translate',
'wmt16_translate',
'wmt17_translate',
'wmt18_translate',
'wmt19_translate',
'wmt_t2t_translate',
'wmt_translate',
'wordnet',
'wsc273',
'xnli',
'xquad',
'xsum',
'xtreme_pawsx',
'xtreme_pos',
'xtreme_s',
'xtreme_xnli',
'yahoo_ltrc',
'yelp_polarity_reviews',
'yes_no',
'youtube_vis',
'huggingface:acronym_identification',
'huggingface:ade_corpus_v2',
'huggingface:adv_glue',
'huggingface:adversarial_qa',
'huggingface:aeslc',
'huggingface:afrikaans_ner_corpus',
'huggingface:ag_news',
'huggingface:ai2_arc',
'huggingface:air_dialogue',
'huggingface:ajgt_twitter_ar',
'huggingface:allegro_reviews',
'huggingface:allocine',
'huggingface:alt',
'huggingface:amazon_polarity',
'huggingface:amazon_reviews_multi',
'huggingface:amazon_us_reviews',
'huggingface:ambig_qa',
'huggingface:americas_nli',
'huggingface:ami',
'huggingface:amttl',
'huggingface:anli',
'huggingface:app_reviews',
'huggingface:aqua_rat',
'huggingface:aquamuse',
'huggingface:ar_cov19',
'huggingface:ar_res_reviews',
'huggingface:ar_sarcasm',
'huggingface:arabic_billion_words',
'huggingface:arabic_pos_dialect',
'huggingface:arabic_speech_corpus',
'huggingface:arcd',
'huggingface:arsentd_lev',
'huggingface:art',
'huggingface:arxiv_dataset',
'huggingface:ascent_kb',
'huggingface:aslg_pc12',
'huggingface:asnq',
'huggingface:asset',
'huggingface:assin',
'huggingface:assin2',
'huggingface:atomic',
'huggingface:autshumato',
'huggingface:babi_qa',
'huggingface:banking77',
'huggingface:bbaw_egyptian',
'huggingface:bbc_hindi_nli',
'huggingface:bc2gm_corpus',
'huggingface:beans',
'huggingface:best2009',
'huggingface:bianet',
'huggingface:bible_para',
'huggingface:big_patent',
'huggingface:bigbench',
'huggingface:billsum',
'huggingface:bing_coronavirus_query_set',
'huggingface:biomrc',
'huggingface:biosses',
'huggingface:biwi_kinect_head_pose',
'huggingface:blbooks',
'huggingface:blbooksgenre',
'huggingface:blended_skill_talk',
'huggingface:blimp',
'huggingface:blog_authorship_corpus',
'huggingface:bn_hate_speech',
'huggingface:bnl_newspapers',
'huggingface:bookcorpus',
'huggingface:bookcorpusopen',
'huggingface:boolq',
'huggingface:bprec',
'huggingface:break_data',
'huggingface:brwac',
'huggingface:bsd_ja_en',
'huggingface:bswac',
'huggingface:c3',
'huggingface:c4',
'huggingface:cail2018',
'huggingface:caner',
'huggingface:capes',
'huggingface:casino',
'huggingface:catalonia_independence',
'huggingface:cats_vs_dogs',
'huggingface:cawac',
'huggingface:cbt',
'huggingface:cc100',
'huggingface:cc_news',
'huggingface:ccaligned_multilingual',
'huggingface:cdsc',
'huggingface:cdt',
'huggingface:cedr',
'huggingface:cfq',
'huggingface:chr_en',
'huggingface:cifar10',
'huggingface:cifar100',
'huggingface:circa',
'huggingface:civil_comments',
'huggingface:clickbait_news_bg',
'huggingface:climate_fever',
'huggingface:clinc_oos',
'huggingface:clue',
'huggingface:cmrc2018',
'huggingface:cmu_hinglish_dog',
'huggingface:cnn_dailymail',
'huggingface:coached_conv_pref',
'huggingface:coarse_discourse',
'huggingface:codah',
'huggingface:code_search_net',
'huggingface:code_x_glue_cc_clone_detection_big_clone_bench',
'huggingface:code_x_glue_cc_clone_detection_poj104',
'huggingface:code_x_glue_cc_cloze_testing_all',
'huggingface:code_x_glue_cc_cloze_testing_maxmin',
'huggingface:code_x_glue_cc_code_completion_line',
'huggingface:code_x_glue_cc_code_completion_token',
'huggingface:code_x_glue_cc_code_refinement',
'huggingface:code_x_glue_cc_code_to_code_trans',
'huggingface:code_x_glue_cc_defect_detection',
'huggingface:code_x_glue_ct_code_to_text',
'huggingface:code_x_glue_tc_nl_code_search_adv',
'huggingface:code_x_glue_tc_text_to_code',
'huggingface:code_x_glue_tt_text_to_text',
'huggingface:com_qa',
'huggingface:common_gen',
'huggingface:common_language',
'huggingface:common_voice',
'huggingface:commonsense_qa',
'huggingface:competition_math',
'huggingface:compguesswhat',
'huggingface:conceptnet5',
'huggingface:conceptual_12m',
'huggingface:conceptual_captions',
'huggingface:conll2000',
'huggingface:conll2002',
'huggingface:conll2003',
'huggingface:conll2012_ontonotesv5',
'huggingface:conllpp',
'huggingface:consumer-finance-complaints',
'huggingface:conv_ai',
'huggingface:conv_ai_2',
'huggingface:conv_ai_3',
'huggingface:conv_questions',
'huggingface:coqa',
'huggingface:cord19',
'huggingface:cornell_movie_dialog',
'huggingface:cos_e',
'huggingface:cosmos_qa',
'huggingface:counter',
'huggingface:covid_qa_castorini',
'huggingface:covid_qa_deepset',
'huggingface:covid_qa_ucsd',
'huggingface:covid_tweets_japanese',
'huggingface:covost2',
'huggingface:cppe-5',
'huggingface:craigslist_bargains',
'huggingface:crawl_domain',
'huggingface:crd3',
'huggingface:crime_and_punish',
'huggingface:crows_pairs',
'huggingface:cryptonite',
'huggingface:cs_restaurants',
'huggingface:cuad',
'huggingface:curiosity_dialogs',
'huggingface:daily_dialog',
'huggingface:dane',
'huggingface:danish_political_comments',
'huggingface:dart',
'huggingface:datacommons_factcheck',
'huggingface:dbpedia_14',
'huggingface:dbrd',
'huggingface:deal_or_no_dialog',
'huggingface:definite_pronoun_resolution',
'huggingface:dengue_filipino',
'huggingface:dialog_re',
'huggingface:diplomacy_detection',
'huggingface:disaster_response_messages',
'huggingface:discofuse',
'huggingface:discovery',
'huggingface:disfl_qa',
'huggingface:doc2dial',
'huggingface:docred',
'huggingface:doqa',
'huggingface:dream',
'huggingface:drop',
'huggingface:duorc',
'huggingface:dutch_social',
'huggingface:dyk',
'huggingface:e2e_nlg',
'huggingface:e2e_nlg_cleaned',
'huggingface:ecb',
'huggingface:ecthr_cases',
'huggingface:eduge',
'huggingface:ehealth_kd',
'huggingface:eitb_parcc',
'huggingface:electricity_load_diagrams',
'huggingface:eli5',
'huggingface:eli5_category',
'huggingface:elkarhizketak',
'huggingface:emea',
'huggingface:emo',
'huggingface:emotion',
'huggingface:emotone_ar',
'huggingface:empathetic_dialogues',
'huggingface:enriched_web_nlg',
'huggingface:enwik8',
'huggingface:eraser_multi_rc',
'huggingface:esnli',
'huggingface:eth_py150_open',
'huggingface:ethos',
'huggingface:ett',
'huggingface:eu_regulatory_ir',
'huggingface:eurlex',
'huggingface:euronews',
'huggingface:europa_eac_tm',
'huggingface:europa_ecdc_tm',
'huggingface:europarl_bilingual',
'huggingface:event2Mind',
'huggingface:evidence_infer_treatment',
'huggingface:exams',
'huggingface:factckbr',
'huggingface:fake_news_english',
'huggingface:fake_news_filipino',
'huggingface:farsi_news',
'huggingface:fashion_mnist',
'huggingface:fever',
'huggingface:few_rel',
'huggingface:financial_phrasebank',
'huggingface:finer',
'huggingface:flores',
'huggingface:flue',
'huggingface:food101',
'huggingface:fquad',
'huggingface:freebase_qa',
'huggingface:gap',
'huggingface:gem',
'huggingface:generated_reviews_enth',
'huggingface:generics_kb',
'huggingface:german_legal_entity_recognition',
'huggingface:germaner',
'huggingface:germeval_14',
'huggingface:giga_fren',
'huggingface:gigaword',
'huggingface:glucose',
'huggingface:glue',
'huggingface:gnad10',
'huggingface:go_emotions',
'huggingface:gooaq',
'huggingface:google_wellformed_query',
'huggingface:grail_qa',
'huggingface:great_code',
'huggingface:greek_legal_code',
'huggingface:gsm8k',
'huggingface:guardian_authorship',
'huggingface:gutenberg_time',
'huggingface:hans',
'huggingface:hansards',
'huggingface:hard',
'huggingface:harem',
'huggingface:has_part',
'huggingface:hate_offensive',
'huggingface:hate_speech18',
'huggingface:hate_speech_filipino',
'huggingface:hate_speech_offensive',
'huggingface:hate_speech_pl',
'huggingface:hate_speech_portuguese',
'huggingface:hatexplain',
'huggingface:hausa_voa_ner',
'huggingface:hausa_voa_topics',
'huggingface:hda_nli_hindi',
'huggingface:head_qa',
'huggingface:health_fact',
'huggingface:hebrew_projectbenyehuda',
'huggingface:hebrew_sentiment',
'huggingface:hebrew_this_world',
'huggingface:hellaswag',
'huggingface:hendrycks_test',
'huggingface:hind_encorp',
'huggingface:hindi_discourse',
'huggingface:hippocorpus',
'huggingface:hkcancor',
'huggingface:hlgd',
'huggingface:hope_edi',
'huggingface:hotpot_qa',
'huggingface:hover',
'huggingface:hrenwac_para',
'huggingface:hrwac',
'huggingface:humicroedit',
'huggingface:hybrid_qa',
'huggingface:hyperpartisan_news_detection',
'huggingface:iapp_wiki_qa_squad',
'huggingface:id_clickbait',
'huggingface:id_liputan6',
'huggingface:id_nergrit_corpus',
'huggingface:id_newspapers_2018',
'huggingface:id_panl_bppt',
'huggingface:id_puisi',
'huggingface:igbo_english_machine_translation',
'huggingface:igbo_monolingual',
'huggingface:igbo_ner',
'huggingface:ilist',
'huggingface:imagenet-1k',
'huggingface:imagenet_sketch',
'huggingface:imdb',
'huggingface:imdb_urdu_reviews',
'huggingface:imppres',
'huggingface:indic_glue',
'huggingface:indonli',
'huggingface:indonlu',
'huggingface:inquisitive_qg',
'huggingface:interpress_news_category_tr',
'huggingface:interpress_news_category_tr_lite',
'huggingface:irc_disentangle',
'huggingface:isixhosa_ner_corpus',
'huggingface:isizulu_ner_corpus',
'huggingface:iwslt2017',
'huggingface:jeopardy',
'huggingface:jfleg',
'huggingface:jigsaw_toxicity_pred',
'huggingface:jigsaw_unintended_bias',
'huggingface:jnlpba',
'huggingface:journalists_questions',
'huggingface:kan_hope',
'huggingface:kannada_news',
'huggingface:kd_conv',
'huggingface:kde4',
'huggingface:kelm',
'huggingface:kilt_tasks',
'huggingface:kilt_wikipedia',
'huggingface:kinnews_kirnews',
'huggingface:klue',
'huggingface:kor_3i4k',
'huggingface:kor_hate',
'huggingface:kor_ner',
'huggingface:kor_nli',
'huggingface:kor_nlu',
'huggingface:kor_qpair',
'huggingface:kor_sae',
'huggingface:kor_sarcasm',
'huggingface:labr',
'huggingface:lama',
'huggingface:lambada',
'huggingface:large_spanish_corpus',
'huggingface:laroseda',
'huggingface:lc_quad',
'huggingface:lccc',
'huggingface:lener_br',
'huggingface:lex_glue',
'huggingface:liar',
'huggingface:librispeech_asr',
'huggingface:librispeech_lm',
'huggingface:limit',
'huggingface:lince',
'huggingface:linnaeus',
'huggingface:liveqa',
'huggingface:lj_speech',
'huggingface:lm1b',
'huggingface:lst20',
'huggingface:m_lama',
'huggingface:mac_morpho',
'huggingface:makhzan',
'huggingface:masakhaner',
'huggingface:math_dataset',
'huggingface:math_qa',
'huggingface:matinf',
'huggingface:mbpp',
'huggingface:mc4',
'huggingface:mc_taco',
'huggingface:md_gender_bias',
'huggingface:mdd',
'huggingface:med_hop',
'huggingface:medal',
'huggingface:medical_dialog',
'huggingface:medical_questions_pairs',
'huggingface:medmcqa',
'huggingface:menyo20k_mt',
'huggingface:meta_woz',
'huggingface:metashift',
'huggingface:metooma',
'huggingface:metrec',
'huggingface:miam',
'huggingface:mkb',
'huggingface:mkqa',
'huggingface:mlqa',
'huggingface:mlsum',
'huggingface:mnist',
'huggingface:mocha',
'huggingface:monash_tsf',
'huggingface:moroco',
'huggingface:movie_rationales',
'huggingface:mrqa',
'huggingface:ms_marco',
'huggingface:ms_terms',
'huggingface:msr_genomics_kbcomp',
'huggingface:msr_sqa',
'huggingface:msr_text_compression',
'huggingface:msr_zhen_translation_parity',
'huggingface:msra_ner',
'huggingface:mt_eng_vietnamese',
'huggingface:muchocine',
'huggingface:multi_booked',
'huggingface:multi_eurlex',
'huggingface:multi_news',
'huggingface:multi_nli',
'huggingface:multi_nli_mismatch',
'huggingface:multi_para_crawl',
'huggingface:multi_re_qa',
'huggingface:multi_woz_v22',
'huggingface:multi_x_science_sum',
'huggingface:multidoc2dial',
'huggingface:multilingual_librispeech',
'huggingface:mutual_friends',
'huggingface:mwsc',
'huggingface:myanmar_news',
'huggingface:narrativeqa',
'huggingface:narrativeqa_manual',
'huggingface:natural_questions',
'huggingface:ncbi_disease',
'huggingface:nchlt',
'huggingface:ncslgr',
'huggingface:nell',
'huggingface:neural_code_search',
'huggingface:news_commentary',
'huggingface:newsgroup',
'huggingface:newsph',
'huggingface:newsph_nli',
'huggingface:newspop',
'huggingface:newsqa',
'huggingface:newsroom',
'huggingface:nkjp-ner',
'huggingface:nli_tr',
'huggingface:nlu_evaluation_data',
'huggingface:norec',
'huggingface:norne',
'huggingface:norwegian_ner',
'huggingface:nq_open',
'huggingface:nsmc',
'huggingface:numer_sense',
'huggingface:numeric_fused_head',
'huggingface:oclar',
'huggingface:offcombr',
'huggingface:offenseval2020_tr',
'huggingface:offenseval_dravidian',
'huggingface:ofis_publik',
'huggingface:ohsumed',
'huggingface:ollie',
'huggingface:omp',
'huggingface:onestop_english',
'huggingface:onestop_qa',
'huggingface:open_subtitles',
'huggingface:openai_humaneval',
'huggingface:openbookqa',
'huggingface:openslr',
'huggingface:openwebtext',
'huggingface:opinosis',
'huggingface:opus100',
'huggingface:opus_books',
'huggingface:opus_dgt',
'huggingface:opus_dogc',
'huggingface:opus_elhuyar',
'huggingface:opus_euconst',
'huggingface:opus_finlex',
'huggingface:opus_fiskmo',
'huggingface:opus_gnome',
'huggingface:opus_infopankki',
'huggingface:opus_memat',
'huggingface:opus_montenegrinsubs',
'huggingface:opus_openoffice',
'huggingface:opus_paracrawl',
'huggingface:opus_rf',
'huggingface:opus_tedtalks',
'huggingface:opus_ubuntu',
'huggingface:opus_wikipedia',
'huggingface:opus_xhosanavy',
'huggingface:orange_sum',
'huggingface:oscar',
'huggingface:para_crawl',
'huggingface:para_pat',
'huggingface:parsinlu_reading_comprehension',
'huggingface:pass',
'huggingface:paws',
'huggingface:paws-x',
'huggingface:pec',
'huggingface:peer_read',
'huggingface:peoples_daily_ner',
'huggingface:per_sent',
'huggingface:persian_ner',
'huggingface:pg19',
'huggingface:php',
'huggingface:piaf',
'huggingface:pib',
'huggingface:piqa',
'huggingface:pn_summary',
'huggingface:poem_sentiment',
'huggingface:polemo2',
'huggingface:poleval2019_cyberbullying',
'huggingface:poleval2019_mt',
'huggingface:polsum',
'huggingface:polyglot_ner',
'huggingface:prachathai67k',
'huggingface:pragmeval',
'huggingface:proto_qa',
'huggingface:psc',
'huggingface:ptb_text_only',
'huggingface:pubmed',
'huggingface:pubmed_qa',
'huggingface:py_ast',
'huggingface:qa4mre',
'huggingface:qa_srl',
'huggingface:qa_zre',
'huggingface:qangaroo',
'huggingface:qanta',
'huggingface:qasc',
'huggingface:qasper',
'huggingface:qed',
'huggingface:qed_amara',
'huggingface:quac',
'huggingface:quail',
'huggingface:quarel',
'huggingface:quartz',
'huggingface:quickdraw',
'huggingface:quora',
'huggingface:quoref',
'huggingface:race',
'huggingface:re_dial',
'huggingface:reasoning_bg',
'huggingface:recipe_nlg',
'huggingface:reclor',
'huggingface:red_caps',
'huggingface:reddit',
'huggingface:reddit_tifu',
'huggingface:refresd',
'huggingface:reuters21578',
'huggingface:riddle_sense',
'huggingface:ro_sent',
'huggingface:ro_sts',
'huggingface:ro_sts_parallel',
'huggingface:roman_urdu',
'huggingface:roman_urdu_hate_speech',
'huggingface:ronec',
'huggingface:ropes',
'huggingface:rotten_tomatoes',
'huggingface:russian_super_glue',
'huggingface:rvl_cdip',
'huggingface:s2orc',
'huggingface:samsum',
'huggingface:sanskrit_classic',
'huggingface:saudinewsnet',
'huggingface:sberquad',
'huggingface:sbu_captions',
'huggingface:scan',
'huggingface:scb_mt_enth_2020',
'huggingface:scene_parse_150',
'huggingface:schema_guided_dstc8',
'huggingface:scicite',
'huggingface:scielo',
'huggingface:scientific_papers',
'huggingface:scifact',
'huggingface:sciq',
'huggingface:scitail',
...]
```
## Load a dataset
### tfds.load
The easiest way of loading a dataset is [`tfds.load`](https://www.tensorflow.org/datasets/api_docs/python/tfds/load). It will:
1. Download the data and save it as [`tfrecord`](https://www.tensorflow.org/tutorials/load_data/tfrecord) files.
2. Load the `tfrecord` and create the [`tf.data.Dataset`](https://www.tensorflow.org/api_docs/python/tf/data/Dataset).
ds = tfds.load('mnist', split='train', shuffle_files=True)
assert isinstance(ds, tf.data.Dataset)
print(ds)
```
<_PrefetchDataset element_spec={'image': TensorSpec(shape=(28, 28, 1), dtype=tf.uint8, name=None), 'label': TensorSpec(shape=(), dtype=tf.int64, name=None)}>
WARNING: All log messages before absl::InitializeLog() is called are written to STDERR
E0000 00:00:1793445031.600629 26835 cuda_platform.cc:52] failed call to cuInit: INTERNAL: CUDA error: Failed call to cuInit: CUDA_ERROR_NO_DEVICE: no CUDA-capable device is detected
```
Some common arguments:
- `split=`: Which split to read (e.g. `'train'`, `['train', 'test']`, `'train[80%:]'`,...). See our [split API guide](https://www.tensorflow.org/datasets/splits).
- `shuffle_files=`: Control whether to shuffle the files between each epoch (TFDS store big datasets in multiple smaller files).
- `data_dir=`: Location where the dataset is saved ( defaults to `~/tensorflow_datasets/`)
- `with_info=True`: Returns the [`tfds.core.DatasetInfo`](https://www.tensorflow.org/datasets/api_docs/python/tfds/core/DatasetInfo) containing dataset metadata
- `download=False`: Disable download
### tfds.builder
[`tfds.load`](https://www.tensorflow.org/datasets/api_docs/python/tfds/load) is a thin wrapper around [`tfds.core.DatasetBuilder`](https://www.tensorflow.org/datasets/api_docs/python/tfds/core/DatasetBuilder). You can get the same output using the [`tfds.core.DatasetBuilder`](https://www.tensorflow.org/datasets/api_docs/python/tfds/core/DatasetBuilder) API:
builder = tfds.builder('mnist')
# 1. Create the tfrecord files (no-op if already exists)
builder.download_and_prepare()
# 2. Load the `tf.data.Dataset`
ds = builder.as_dataset(split='train', shuffle_files=True)
print(ds)
```
<_PrefetchDataset element_spec={'image': TensorSpec(shape=(28, 28, 1), dtype=tf.uint8, name=None), 'label': TensorSpec(shape=(), dtype=tf.int64, name=None)}>
```
### `tfds build` CLI
If you want to generate a specific dataset, you can use the [`tfds` command line](https://www.tensorflow.org/datasets/cli). For example:
tfds build mnist
See [the doc](https://www.tensorflow.org/datasets/cli) for available flags.
## Iterate over a dataset
### As dict
By default, the [`tf.data.Dataset`](https://www.tensorflow.org/api_docs/python/tf/data/Dataset) object contains a `dict` of [`tf.Tensor`](https://www.tensorflow.org/api_docs/python/tf/Tensor)s:
ds = tfds.load('mnist', split='train')
ds = ds.take(1) # Only take a single example
for example in ds: # example is `{'image': tf.Tensor, 'label': tf.Tensor}`
print(list(example.keys()))
image = example["image"]
label = example["label"]
print(image.shape, label)
```
['image', 'label']
(28, 28, 1) tf.Tensor(4, shape=(), dtype=int64)
W0000 00:00:1793445032.760283 27040 cache_dataset_ops.cc:912] The calling iterator did not fully read the dataset being cached. In order to avoid unexpected truncation of the dataset, the partially cached contents of the dataset will be discarded. This can happen if you have an input pipeline similar to `dataset.cache().take(k).repeat()`. You should use `dataset.take(k).cache().repeat()` instead.
```
To find out the `dict` key names and structure, look at the dataset documentation in [our catalog](https://www.tensorflow.org/datasets/catalog/overview#all_datasets). For example: [mnist documentation](https://www.tensorflow.org/datasets/catalog/mnist).
### As tuple (`as_supervised=True`)
By using `as_supervised=True`, you can get a tuple `(features, label)` instead for supervised datasets.
ds = tfds.load('mnist', split='train', as_supervised=True)
ds = ds.take(1)
for image, label in ds: # example is (image, label)
print(image.shape, label)
```
(28, 28, 1) tf.Tensor(4, shape=(), dtype=int64)
W0000 00:00:1793445033.485795 27148 cache_dataset_ops.cc:912] The calling iterator did not fully read the dataset being cached. In order to avoid unexpected truncation of the dataset, the partially cached contents of the dataset will be discarded. This can happen if you have an input pipeline similar to `dataset.cache().take(k).repeat()`. You should use `dataset.take(k).cache().repeat()` instead.
```
### As numpy ([`tfds.as_numpy`](https://www.tensorflow.org/datasets/api_docs/python/tfds/as_numpy))
Uses [`tfds.as_numpy`](https://www.tensorflow.org/datasets/api_docs/python/tfds/as_numpy) to convert:
- [`tf.Tensor`](https://www.tensorflow.org/api_docs/python/tf/Tensor) -\> `np.array`
- [`tf.data.Dataset`](https://www.tensorflow.org/api_docs/python/tf/data/Dataset) -\> `Iterator[Tree[np.array]]` (`Tree` can be arbitrary nested `Dict`, `Tuple`)
ds = tfds.load('mnist', split='train', as_supervised=True)
ds = ds.take(1)
for image, label in tfds.as_numpy(ds):
print(type(image), type(label), label)
```
4
W0000 00:00:1793445034.130932 27256 cache_dataset_ops.cc:912] The calling iterator did not fully read the dataset being cached. In order to avoid unexpected truncation of the dataset, the partially cached contents of the dataset will be discarded. This can happen if you have an input pipeline similar to `dataset.cache().take(k).repeat()`. You should use `dataset.take(k).cache().repeat()` instead.
```
### As batched tf.Tensor (`batch_size=-1`)
By using `batch_size=-1`, you can load the full dataset in a single batch.
This can be combined with `as_supervised=True` and [`tfds.as_numpy`](https://www.tensorflow.org/datasets/api_docs/python/tfds/as_numpy) to get the the data as `(np.array, np.array)`:
image, label = tfds.as_numpy(tfds.load(
'mnist',
split='test',
batch_size=-1,
as_supervised=True,
))
print(type(image), image.shape)
```
(10000, 28, 28, 1)
```
Be careful that your dataset can fit in memory, and that all examples have the same shape.
## Benchmark your datasets
Benchmarking a dataset is a simple [`tfds.benchmark`](https://www.tensorflow.org/datasets/api_docs/python/tfds/benchmark) call on any iterable (e.g. [`tf.data.Dataset`](https://www.tensorflow.org/api_docs/python/tf/data/Dataset), [`tfds.as_numpy`](https://www.tensorflow.org/datasets/api_docs/python/tfds/as_numpy),...).
ds = tfds.load('mnist', split='train')
ds = ds.batch(32).prefetch(1)
tfds.benchmark(ds, batch_size=32)
tfds.benchmark(ds, batch_size=32) # Second epoch much faster due to auto-caching
```
************ Summary ************
Examples/sec (First included) 52971.17 ex/sec (total: 60032 ex, 1.13 sec)
Examples/sec (First only) 134.07 ex/sec (total: 32 ex, 0.24 sec)
Examples/sec (First excluded) 67068.22 ex/sec (total: 60000 ex, 0.89 sec)
************ Summary ************
Examples/sec (First included) 168289.53 ex/sec (total: 60032 ex, 0.36 sec)
Examples/sec (First only) 2024.91 ex/sec (total: 32 ex, 0.02 sec)
Examples/sec (First excluded) 175996.76 ex/sec (total: 60000 ex, 0.34 sec)
```
- Do not forget to normalize the results per batch size with the `batch_size=` kwarg.
- In the summary, the first warmup batch is separated from the other ones to capture [`tf.data.Dataset`](https://www.tensorflow.org/api_docs/python/tf/data/Dataset) extra setup time (e.g. buffers initialization,...).
- Notice how the second iteration is much faster due to [TFDS auto-caching](https://www.tensorflow.org/datasets/performances#auto-caching).
- [`tfds.benchmark`](https://www.tensorflow.org/datasets/api_docs/python/tfds/benchmark) returns a [`tfds.core.BenchmarkResult`](https://www.tensorflow.org/datasets/api_docs/python/tfds/core/BenchmarkResult) which can be inspected for further analysis.
### Build end-to-end pipeline
To go further, you can look:
- Our [end-to-end Keras example](https://www.tensorflow.org/datasets/keras_example) to see a full training pipeline (with batching, shuffling,...).
- Our [performance guide](https://www.tensorflow.org/datasets/performances) to improve the speed of your pipelines (tip: use [`tfds.benchmark(ds)`](https://www.tensorflow.org/datasets/api_docs/python/tfds/benchmark) to benchmark your datasets).
## Visualization
### tfds.as_dataframe
[`tf.data.Dataset`](https://www.tensorflow.org/api_docs/python/tf/data/Dataset) objects can be converted to [`pandas.DataFrame`](https://pandas.pydata.org/pandas-docs/stable/reference/api/pandas.DataFrame.html) with [`tfds.as_dataframe`](https://www.tensorflow.org/datasets/api_docs/python/tfds/as_dataframe) to be visualized on [Colab](https://colab.research.google.com).
- Add the [`tfds.core.DatasetInfo`](https://www.tensorflow.org/datasets/api_docs/python/tfds/core/DatasetInfo) as second argument of [`tfds.as_dataframe`](https://www.tensorflow.org/datasets/api_docs/python/tfds/as_dataframe) to visualize images, audio, texts, videos,...
- Use `ds.take(x)` to only display the first `x` examples. `pandas.DataFrame` will load the full dataset in-memory, and can be very expensive to display.
ds, info = tfds.load('mnist', split='train', with_info=True)
tfds.as_dataframe(ds.take(4), info)
```
W0000 00:00:1793445037.845493 27577 cache_dataset_ops.cc:912] The calling iterator did not fully read the dataset being cached. In order to avoid unexpected truncation of the dataset, the partially cached contents of the dataset will be discarded. This can happen if you have an input pipeline similar to `dataset.cache().take(k).repeat()`. You should use `dataset.take(k).cache().repeat()` instead.
```
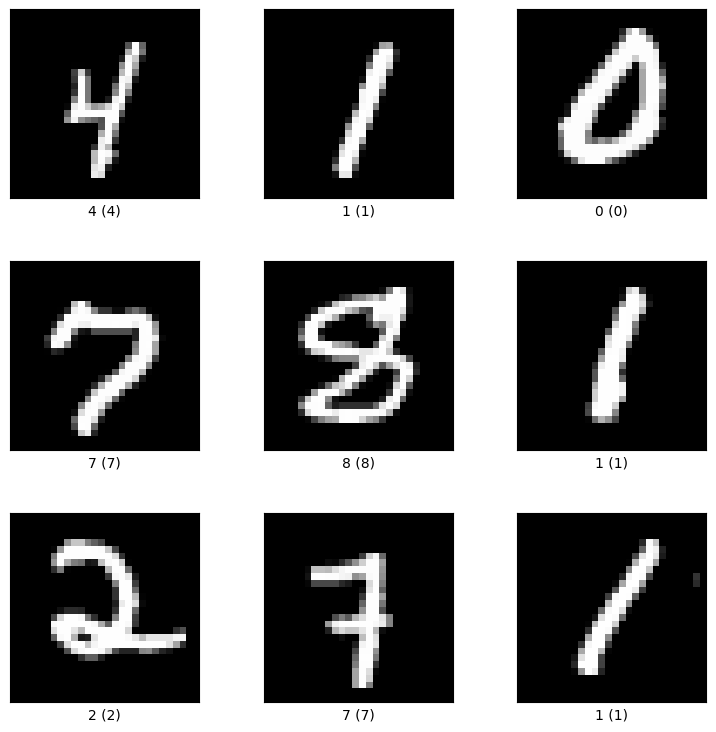
### tfds.show_examples
[`tfds.show_examples`](https://www.tensorflow.org/datasets/api_docs/python/tfds/visualization/show_examples) returns a `matplotlib.figure.Figure` (only image datasets supported now):
ds, info = tfds.load('mnist', split='train', with_info=True)
fig = tfds.show_examples(ds, info)
```
W0000 00:00:1793445038.616962 26835 cache_dataset_ops.cc:912] The calling iterator did not fully read the dataset being cached. In order to avoid unexpected truncation of the dataset, the partially cached contents of the dataset will be discarded. This can happen if you have an input pipeline similar to `dataset.cache().take(k).repeat()`. You should use `dataset.take(k).cache().repeat()` instead.
```
## Access the dataset metadata
All builders include a [`tfds.core.DatasetInfo`](https://www.tensorflow.org/datasets/api_docs/python/tfds/core/DatasetInfo) object containing the dataset metadata.
It can be accessed through:
- The [`tfds.load`](https://www.tensorflow.org/datasets/api_docs/python/tfds/load) API:
ds, info = tfds.load('mnist', with_info=True)
- The [`tfds.core.DatasetBuilder`](https://www.tensorflow.org/datasets/api_docs/python/tfds/core/DatasetBuilder) API:
builder = tfds.builder('mnist')
info = builder.info
The dataset info contains additional informations about the dataset (version, citation, homepage, description,...).
print(info)
```
tfds.core.DatasetInfo(
name='mnist',
full_name='mnist/3.0.1',
description="""
The MNIST database of handwritten digits.
""",
homepage='http://yann.lecun.com/exdb/mnist/',
data_dir='gs://tensorflow-datasets/datasets/mnist/3.0.1',
file_format=tfrecord,
download_size=11.06 MiB,
dataset_size=21.00 MiB,
features=FeaturesDict({
'image': Image(shape=(28, 28, 1), dtype=uint8),
'label': ClassLabel(shape=(), dtype=int64, num_classes=10),
}),
supervised_keys=('image', 'label'),
disable_shuffling=False,
nondeterministic_order=False,
splits={
'test': ,
'train': ,
},
citation="""@article{lecun2010mnist,
title={MNIST handwritten digit database},
author={LeCun, Yann and Cortes, Corinna and Burges, CJ},
journal={ATT Labs [Online]. Available: http://yann.lecun.com/exdb/mnist},
volume={2},
year={2010}
}""",
)
```
### Features metadata (label names, image shape,...)
Access the `tfds.features.FeatureDict`:
info.features
```
FeaturesDict({
'image': Image(shape=(28, 28, 1), dtype=uint8),
'label': ClassLabel(shape=(), dtype=int64, num_classes=10),
})
```
Number of classes, label names:
print(info.features["label"].num_classes)
print(info.features["label"].names)
print(info.features["label"].int2str(7)) # Human readable version (8 -> 'cat')
print(info.features["label"].str2int('7'))
```
10
['0', '1', '2', '3', '4', '5', '6', '7', '8', '9']
7
7
```
Shapes, dtypes:
print(info.features.shape)
print(info.features.dtype)
print(info.features['image'].shape)
print(info.features['image'].dtype)
```
WARNING:absl:`FeatureConnector.dtype` is deprecated. Please change your code to use NumPy with the field `FeatureConnector.np_dtype` or use TensorFlow with the field `FeatureConnector.tf_dtype`.
WARNING:absl:`FeatureConnector.dtype` is deprecated. Please change your code to use NumPy with the field `FeatureConnector.np_dtype` or use TensorFlow with the field `FeatureConnector.tf_dtype`.
{'image': (28, 28, 1), 'label': ()}
{'image': tf.uint8, 'label': tf.int64}
(28, 28, 1)
```
### Split metadata (e.g. split names, number of examples,...)
Access the [`tfds.core.SplitDict`](https://www.tensorflow.org/datasets/api_docs/python/tfds/core/SplitDict):
print(info.splits)
```
{'test': , 'train': }
```
Available splits:
print(list(info.splits.keys()))
```
['test', 'train']
```
Get info on individual split:
print(info.splits['train'].num_examples)
print(info.splits['train'].filenames)
print(info.splits['train'].num_shards)
```
60000
['mnist-train.tfrecord-00000-of-00001']
1
```
It also works with the subsplit API:
print(info.splits['train[15%:75%]'].num_examples)
print(info.splits['train[15%:75%]'].file_instructions)
```
36000
[FileInstruction(filename='gs://tensorflow-datasets/datasets/mnist/3.0.1/mnist-train.tfrecord-00000-of-00001', skip=9000, take=36000, examples_in_shard=60000)]
```
## Troubleshooting
### Manual download (if download fails)
If download fails for some reason (e.g. offline,...). You can always manually download the data yourself and place it in the `manual_dir` (defaults to `~/tensorflow_datasets/downloads/manual/`.
To find out which urls to download, look into:
- For new datasets (implemented as folder): [`tensorflow_datasets/`](https://github.com/tensorflow/datasets/tree/master/tensorflow_datasets/)`//checksums.tsv`. For example: [`tensorflow_datasets/datasets/bool_q/checksums.tsv`](https://github.com/tensorflow/datasets/blob/master/tensorflow_datasets/datasets/bool_q/checksums.tsv).
You can find the dataset source location in [our catalog](https://www.tensorflow.org/datasets/catalog/overview).
- For old datasets: [`tensorflow_datasets/url_checksums/.txt`](https://github.com/tensorflow/datasets/tree/master/tensorflow_datasets/url_checksums)
### Fixing `NonMatchingChecksumError`
TFDS ensure determinism by validating the checksums of downloaded urls.
If `NonMatchingChecksumError` is raised, might indicate:
- The website may be down (e.g. `503 status code`). Please check the url.
- For Google Drive URLs, try again later as Drive sometimes rejects downloads when too many people access the same URL. See [bug](https://github.com/tensorflow/datasets/issues/1482)
- The original datasets files may have been updated. In this case the TFDS dataset builder should be updated. Please open a new Github issue or PR:
- Register the new checksums with `tfds build --register_checksums`
- Eventually update the dataset generation code.
- Update the dataset `VERSION`
- Update the dataset `RELEASE_NOTES`: What caused the checksums to change ? Did some examples changed ?
- Make sure the dataset can still be built.
- Send us a PR
> [!NOTE]
> **Note:** You can also inspect the downloaded file in `~/tensorflow_datasets/download/`.
## Citation
If you're using `tensorflow-datasets` for a paper, please include the following citation, in addition to any citation specific to the used datasets (which can be found in the [dataset catalog](https://www.tensorflow.org/datasets/catalog/overview)).
@misc{TFDS,
title = { {TensorFlow Datasets}, A collection of ready-to-use datasets},
howpublished = {\url{https://www.tensorflow.org/datasets} },
}