**Author:** [fchollet](https://twitter.com/fchollet)
|---|---|---|---|
| [View on TensorFlow.org](https://www.tensorflow.org/guide/keras/transfer_learning) | [Run in Google Colab](https://colab.research.google.com/github/keras-team/keras-io/blob/master/guides/ipynb/transfer_learning.ipynb) | [View source on GitHub](https://github.com/keras-team/keras-io/blob/master/guides/transfer_learning.py) | [View on keras.io](https://keras.io/guides/transfer_learning) |
## Setup
import numpy as np
import tensorflow as tf
from tensorflow import keras
```
2023-10-03 11:11:08.160283: E tensorflow/compiler/xla/stream_executor/cuda/cuda_dnn.cc:9342] Unable to register cuDNN factory: Attempting to register factory for plugin cuDNN when one has already been registered
2023-10-03 11:11:08.160349: E tensorflow/compiler/xla/stream_executor/cuda/cuda_fft.cc:609] Unable to register cuFFT factory: Attempting to register factory for plugin cuFFT when one has already been registered
2023-10-03 11:11:08.160404: E tensorflow/compiler/xla/stream_executor/cuda/cuda_blas.cc:1518] Unable to register cuBLAS factory: Attempting to register factory for plugin cuBLAS when one has already been registered
```
## Introduction
**Transfer learning** consists of taking features learned on one problem, and
leveraging them on a new, similar problem. For instance, features from a model that has
learned to identify racoons may be useful to kick-start a model meant to identify
tanukis.
Transfer learning is usually done for tasks where your dataset has too little data to
train a full-scale model from scratch.
The most common incarnation of transfer learning in the context of deep learning is the
following workflow:
1. Take layers from a previously trained model.
2. Freeze them, so as to avoid destroying any of the information they contain during future training rounds.
3. Add some new, trainable layers on top of the frozen layers. They will learn to turn the old features into predictions on a new dataset.
4. Train the new layers on your dataset.
A last, optional step, is **fine-tuning**, which consists of unfreezing the entire
model you obtained above (or part of it), and re-training it on the new data with a
very low learning rate. This can potentially achieve meaningful improvements, by
incrementally adapting the pretrained features to the new data.
First, we will go over the Keras `trainable` API in detail, which underlies most
transfer learning \& fine-tuning workflows.
Then, we'll demonstrate the typical workflow by taking a model pretrained on the
ImageNet dataset, and retraining it on the Kaggle "cats vs dogs" classification
dataset.
This is adapted from
[Deep Learning with Python](https://www.manning.com/books/deep-learning-with-python)
and the 2016 blog post
["building powerful image classification models using very little
data"](https://blog.keras.io/building-powerful-image-classification-models-using-very-little-data.html).
## Freezing layers: understanding the `trainable` attribute
Layers \& models have three weight attributes:
- `weights` is the list of all weights variables of the layer.
- `trainable_weights` is the list of those that are meant to be updated (via gradient descent) to minimize the loss during training.
- `non_trainable_weights` is the list of those that aren't meant to be trained. Typically they are updated by the model during the forward pass.
**Example: the `Dense` layer has 2 trainable weights (kernel \& bias)**
layer = keras.layers.Dense(3)
layer.build((None, 4)) # Create the weights
print("weights:", len(layer.weights))
print("trainable_weights:", len(layer.trainable_weights))
print("non_trainable_weights:", len(layer.non_trainable_weights))
```
weights: 2
trainable_weights: 2
non_trainable_weights: 0
2023-10-03 11:11:10.677246: W tensorflow/core/common_runtime/gpu/gpu_device.cc:2211] Cannot dlopen some GPU libraries. Please make sure the missing libraries mentioned above are installed properly if you would like to use GPU. Follow the guide at https://www.tensorflow.org/install/gpu for how to download and setup the required libraries for your platform.
Skipping registering GPU devices...
```
In general, all weights are trainable weights. The only built-in layer that has
non-trainable weights is the `BatchNormalization` layer. It uses non-trainable weights
to keep track of the mean and variance of its inputs during training.
To learn how to use non-trainable weights in your own custom layers, see the
[guide to writing new layers from scratch](https://www.tensorflow.org/guide/keras/making_new_layers_and_models_via_subclassing).
**Example: the `BatchNormalization` layer has 2 trainable weights and 2 non-trainable
weights**
layer = keras.layers.BatchNormalization()
layer.build((None, 4)) # Create the weights
print("weights:", len(layer.weights))
print("trainable_weights:", len(layer.trainable_weights))
print("non_trainable_weights:", len(layer.non_trainable_weights))
```
weights: 4
trainable_weights: 2
non_trainable_weights: 2
```
Layers \& models also feature a boolean attribute `trainable`. Its value can be changed.
Setting `layer.trainable` to `False` moves all the layer's weights from trainable to
non-trainable. This is called "freezing" the layer: the state of a frozen layer won't
be updated during training (either when training with `fit()` or when training with
any custom loop that relies on `trainable_weights` to apply gradient updates).
**Example: setting `trainable` to `False`**
layer = keras.layers.Dense(3)
layer.build((None, 4)) # Create the weights
layer.trainable = False # Freeze the layer
print("weights:", len(layer.weights))
print("trainable_weights:", len(layer.trainable_weights))
print("non_trainable_weights:", len(layer.non_trainable_weights))
```
weights: 2
trainable_weights: 0
non_trainable_weights: 2
```
When a trainable weight becomes non-trainable, its value is no longer updated during
training.
# Make a model with 2 layers
layer1 = keras.layers.Dense(3, activation="relu")
layer2 = keras.layers.Dense(3, activation="sigmoid")
model = keras.Sequential([keras.Input(shape=(3,)), layer1, layer2])
# Freeze the first layer
layer1.trainable = False
# Keep a copy of the weights of layer1 for later reference
initial_layer1_weights_values = layer1.get_weights()
# Train the model
model.compile(optimizer="adam", loss="mse")
model.fit(np.random.random((2, 3)), np.random.random((2, 3)))
# Check that the weights of layer1 have not changed during training
final_layer1_weights_values = layer1.get_weights()
np.testing.assert_allclose(
initial_layer1_weights_values[0], final_layer1_weights_values[0]
)
np.testing.assert_allclose(
initial_layer1_weights_values[1], final_layer1_weights_values[1]
)
```
1/1 [==============================] - 0s 324ms/step - loss: 0.0178
```
Do not confuse the `layer.trainable` attribute with the argument `training` in
`layer.__call__()` (which controls whether the layer should run its forward pass in
inference mode or training mode). For more information, see the
[Keras FAQ](https://keras.io/getting_started/faq/#whats-the-difference-between-the-training-argument-in-call-and-the-trainable-attribute).
## Recursive setting of the `trainable` attribute
If you set `trainable = False` on a model or on any layer that has sublayers,
all children layers become non-trainable as well.
**Example:**
inner_model = keras.Sequential(
[
keras.Input(shape=(3,)),
keras.layers.Dense(3, activation="relu"),
keras.layers.Dense(3, activation="relu"),
]
)
model = keras.Sequential(
[
keras.Input(shape=(3,)),
inner_model,
keras.layers.Dense(3, activation="sigmoid"),
]
)
model.trainable = False # Freeze the outer model
assert inner_model.trainable == False # All layers in `model` are now frozen
assert inner_model.layers[0].trainable == False # `trainable` is propagated recursively
## The typical transfer-learning workflow
This leads us to how a typical transfer learning workflow can be implemented in Keras:
1. Instantiate a base model and load pre-trained weights into it.
2. Freeze all layers in the base model by setting `trainable = False`.
3. Create a new model on top of the output of one (or several) layers from the base model.
4. Train your new model on your new dataset.
Note that an alternative, more lightweight workflow could also be:
1. Instantiate a base model and load pre-trained weights into it.
2. Run your new dataset through it and record the output of one (or several) layers from the base model. This is called **feature extraction**.
3. Use that output as input data for a new, smaller model.
A key advantage of that second workflow is that you only run the base model once on
your data, rather than once per epoch of training. So it's a lot faster \& cheaper.
An issue with that second workflow, though, is that it doesn't allow you to dynamically
modify the input data of your new model during training, which is required when doing
data augmentation, for instance. Transfer learning is typically used for tasks when
your new dataset has too little data to train a full-scale model from scratch, and in
such scenarios data augmentation is very important. So in what follows, we will focus
on the first workflow.
Here's what the first workflow looks like in Keras:
First, instantiate a base model with pre-trained weights.
base_model = keras.applications.Xception(
weights='imagenet', # Load weights pre-trained on ImageNet.
input_shape=(150, 150, 3),
include_top=False) # Do not include the ImageNet classifier at the top.
Then, freeze the base model.
base_model.trainable = False
Create a new model on top.
inputs = keras.Input(shape=(150, 150, 3))
# We make sure that the base_model is running in inference mode here,
# by passing `training=False`. This is important for fine-tuning, as you will
# learn in a few paragraphs.
x = base_model(inputs, training=False)
# Convert features of shape `base_model.output_shape[1:]` to vectors
x = keras.layers.GlobalAveragePooling2D()(x)
# A Dense classifier with a single unit (binary classification)
outputs = keras.layers.Dense(1)(x)
model = keras.Model(inputs, outputs)
Train the model on new data.
model.compile(optimizer=keras.optimizers.Adam(),
loss=keras.losses.BinaryCrossentropy(from_logits=True),
metrics=[keras.metrics.BinaryAccuracy()])
model.fit(new_dataset, epochs=20, callbacks=..., validation_data=...)
## Fine-tuning
Once your model has converged on the new data, you can try to unfreeze all or part of
the base model and retrain the whole model end-to-end with a very low learning rate.
This is an optional last step that can potentially give you incremental improvements.
It could also potentially lead to quick overfitting -- keep that in mind.
It is critical to only do this step *after* the model with frozen layers has been
trained to convergence. If you mix randomly-initialized trainable layers with
trainable layers that hold pre-trained features, the randomly-initialized layers will
cause very large gradient updates during training, which will destroy your pre-trained
features.
It's also critical to use a very low learning rate at this stage, because
you are training a much larger model than in the first round of training, on a dataset
that is typically very small.
As a result, you are at risk of overfitting very quickly if you apply large weight
updates. Here, you only want to readapt the pretrained weights in an incremental way.
This is how to implement fine-tuning of the whole base model:
# Unfreeze the base model
base_model.trainable = True
# It's important to recompile your model after you make any changes
# to the `trainable` attribute of any inner layer, so that your changes
# are take into account
model.compile(optimizer=keras.optimizers.Adam(1e-5), # Very low learning rate
loss=keras.losses.BinaryCrossentropy(from_logits=True),
metrics=[keras.metrics.BinaryAccuracy()])
# Train end-to-end. Be careful to stop before you overfit!
model.fit(new_dataset, epochs=10, callbacks=..., validation_data=...)
**Important note about `compile()` and `trainable`**
Calling `compile()` on a model is meant to "freeze" the behavior of that model. This
implies that the `trainable`
attribute values at the time the model is compiled should be preserved throughout the
lifetime of that model,
until `compile` is called again. Hence, if you change any `trainable` value, make sure
to call `compile()` again on your
model for your changes to be taken into account.
**Important notes about `BatchNormalization` layer**
Many image models contain `BatchNormalization` layers. That layer is a special case on
every imaginable count. Here are a few things to keep in mind.
- `BatchNormalization` contains 2 non-trainable weights that get updated during training. These are the variables tracking the mean and variance of the inputs.
- When you set `bn_layer.trainable = False`, the `BatchNormalization` layer will run in inference mode, and will not update its mean \& variance statistics. This is not the case for other layers in general, as [weight trainability \& inference/training modes are two orthogonal concepts](https://keras.io/getting_started/faq/#whats-the-difference-between-the-training-argument-in-call-and-the-trainable-attribute). But the two are tied in the case of the `BatchNormalization` layer.
- When you unfreeze a model that contains `BatchNormalization` layers in order to do fine-tuning, you should keep the `BatchNormalization` layers in inference mode by passing `training=False` when calling the base model. Otherwise the updates applied to the non-trainable weights will suddenly destroy what the model has learned.
You'll see this pattern in action in the end-to-end example at the end of this guide.
## Transfer learning \& fine-tuning with a custom training loop
If instead of `fit()`, you are using your own low-level training loop, the workflow
stays essentially the same. You should be careful to only take into account the list
`model.trainable_weights` when applying gradient updates:
# Create base model
base_model = keras.applications.Xception(
weights='imagenet',
input_shape=(150, 150, 3),
include_top=False)
# Freeze base model
base_model.trainable = False
# Create new model on top.
inputs = keras.Input(shape=(150, 150, 3))
x = base_model(inputs, training=False)
x = keras.layers.GlobalAveragePooling2D()(x)
outputs = keras.layers.Dense(1)(x)
model = keras.Model(inputs, outputs)
loss_fn = keras.losses.BinaryCrossentropy(from_logits=True)
optimizer = keras.optimizers.Adam()
# Iterate over the batches of a dataset.
for inputs, targets in new_dataset:
# Open a GradientTape.
with tf.GradientTape() as tape:
# Forward pass.
predictions = model(inputs)
# Compute the loss value for this batch.
loss_value = loss_fn(targets, predictions)
# Get gradients of loss wrt the *trainable* weights.
gradients = tape.gradient(loss_value, model.trainable_weights)
# Update the weights of the model.
optimizer.apply_gradients(zip(gradients, model.trainable_weights))
Likewise for fine-tuning.
## An end-to-end example: fine-tuning an image classification model on a cats vs. dogs dataset
To solidify these concepts, let's walk you through a concrete end-to-end transfer
learning \& fine-tuning example. We will load the Xception model, pre-trained on
ImageNet, and use it on the Kaggle "cats vs. dogs" classification dataset.
### Getting the data
First, let's fetch the cats vs. dogs dataset using TFDS. If you have your own dataset,
you'll probably want to use the utility
[`keras.utils.image_dataset_from_directory`](https://www.tensorflow.org/api_docs/python/tf/keras/utils/image_dataset_from_directory) to generate similar labeled
dataset objects from a set of images on disk filed into class-specific folders.
Transfer learning is most useful when working with very small datasets. To keep our
dataset small, we will use 40% of the original training data (25,000 images) for
training, 10% for validation, and 10% for testing.
import tensorflow_datasets as tfds
tfds.disable_progress_bar()
train_ds, validation_ds, test_ds = tfds.load(
"cats_vs_dogs",
# Reserve 10% for validation and 10% for test
split=["train[:40%]", "train[40%:50%]", "train[50%:60%]"],
as_supervised=True, # Include labels
)
print("Number of training samples: %d" % tf.data.experimental.cardinality(train_ds))
print(
"Number of validation samples: %d" % tf.data.experimental.cardinality(validation_ds)
)
print("Number of test samples: %d" % tf.data.experimental.cardinality(test_ds))
```
Number of training samples: 9305
Number of validation samples: 2326
Number of test samples: 2326
```
These are the first 9 images in the training dataset -- as you can see, they're all
different sizes.
import matplotlib.pyplot as plt
plt.figure(figsize=(10, 10))
for i, (image, label) in enumerate(train_ds.take(9)):
ax = plt.subplot(3, 3, i + 1)
plt.imshow(image)
plt.title(int(label))
plt.axis("off")
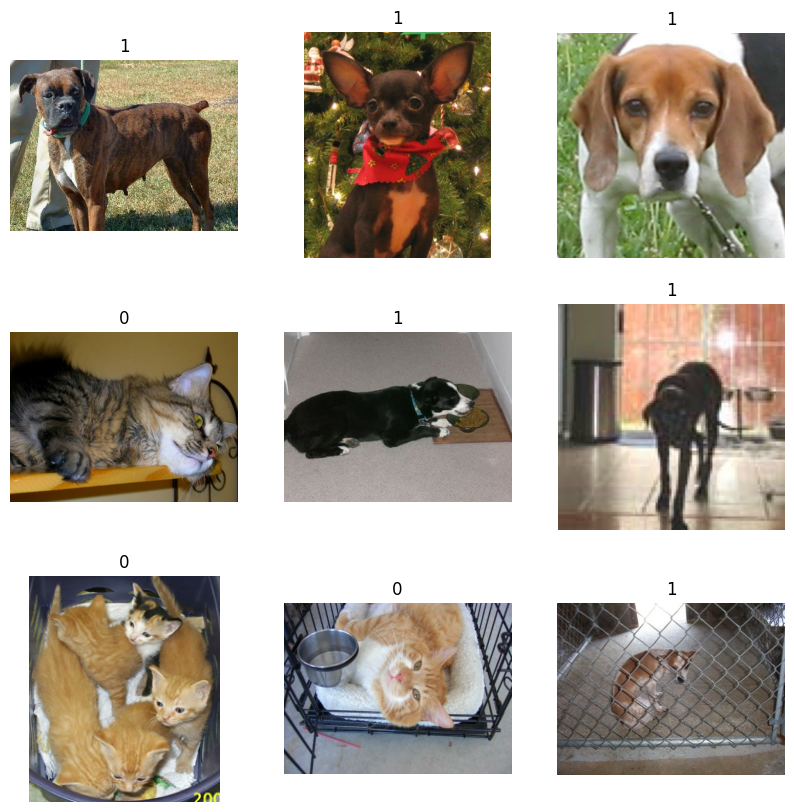
We can also see that label 1 is "dog" and label 0 is "cat".
### Standardizing the data
Our raw images have a variety of sizes. In addition, each pixel consists of 3 integer
values between 0 and 255 (RGB level values). This isn't a great fit for feeding a
neural network. We need to do 2 things:
- Standardize to a fixed image size. We pick 150x150.
- Normalize pixel values between -1 and 1. We'll do this using a `Normalization` layer as part of the model itself.
In general, it's a good practice to develop models that take raw data as input, as
opposed to models that take already-preprocessed data. The reason being that, if your
model expects preprocessed data, any time you export your model to use it elsewhere
(in a web browser, in a mobile app), you'll need to reimplement the exact same
preprocessing pipeline. This gets very tricky very quickly. So we should do the least
possible amount of preprocessing before hitting the model.
Here, we'll do image resizing in the data pipeline (because a deep neural network can
only process contiguous batches of data), and we'll do the input value scaling as part
of the model, when we create it.
Let's resize images to 150x150:
size = (150, 150)
train_ds = train_ds.map(lambda x, y: (tf.image.resize(x, size), y))
validation_ds = validation_ds.map(lambda x, y: (tf.image.resize(x, size), y))
test_ds = test_ds.map(lambda x, y: (tf.image.resize(x, size), y))
Besides, let's batch the data and use caching \& prefetching to optimize loading speed.
batch_size = 32
train_ds = train_ds.cache().batch(batch_size).prefetch(buffer_size=10)
validation_ds = validation_ds.cache().batch(batch_size).prefetch(buffer_size=10)
test_ds = test_ds.cache().batch(batch_size).prefetch(buffer_size=10)
### Using random data augmentation
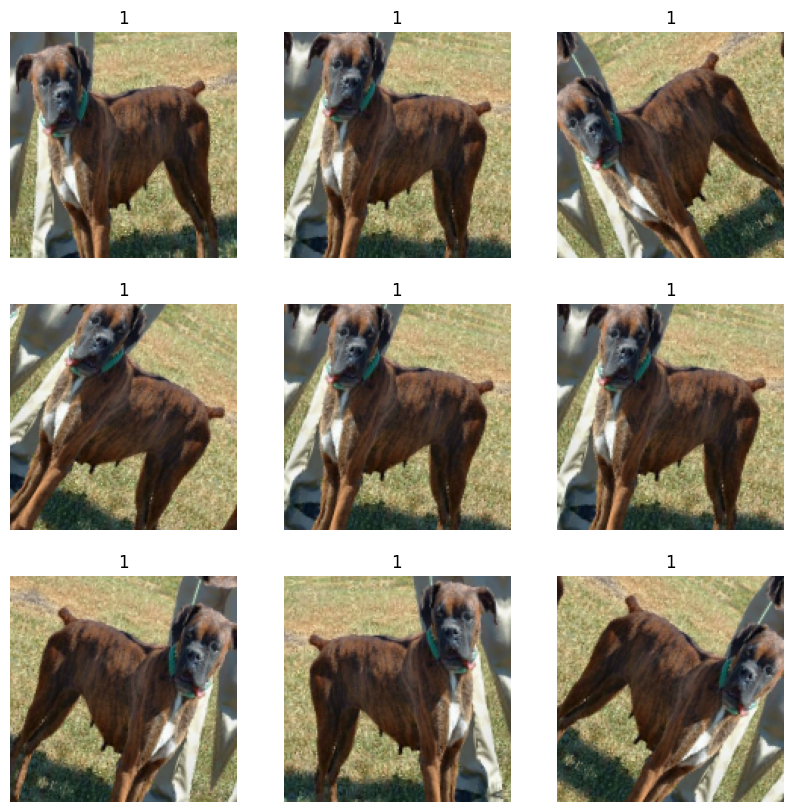
When you don't have a large image dataset, it's a good practice to artificially
introduce sample diversity by applying random yet realistic transformations to
the training images, such as random horizontal flipping or small random rotations. This
helps expose the model to different aspects of the training data while slowing down
overfitting.
from tensorflow import keras
from tensorflow.keras import layers
data_augmentation = keras.Sequential(
[
layers.RandomFlip("horizontal"),
layers.RandomRotation(0.1),
]
)
Let's visualize what the first image of the first batch looks like after various random
transformations:
import numpy as np
for images, labels in train_ds.take(1):
plt.figure(figsize=(10, 10))
first_image = images[0]
for i in range(9):
ax = plt.subplot(3, 3, i + 1)
augmented_image = data_augmentation(
tf.expand_dims(first_image, 0), training=True
)
plt.imshow(augmented_image[0].numpy().astype("int32"))
plt.title(int(labels[0]))
plt.axis("off")
```
2023-10-03 11:11:16.151536: W tensorflow/core/kernels/data/cache_dataset_ops.cc:854] The calling iterator did not fully read the dataset being cached. In order to avoid unexpected truncation of the dataset, the partially cached contents of the dataset will be discarded. This can happen if you have an input pipeline similar to `dataset.cache().take(k).repeat()`. You should use `dataset.take(k).cache().repeat()` instead.
```
## Build a model
Now let's built a model that follows the blueprint we've explained earlier.
Note that:
- We add a `Rescaling` layer to scale input values (initially in the `[0, 255]` range) to the `[-1, 1]` range.
- We add a `Dropout` layer before the classification layer, for regularization.
- We make sure to pass `training=False` when calling the base model, so that it runs in inference mode, so that batchnorm statistics don't get updated even after we unfreeze the base model for fine-tuning.
base_model = keras.applications.Xception(
weights="imagenet", # Load weights pre-trained on ImageNet.
input_shape=(150, 150, 3),
include_top=False,
) # Do not include the ImageNet classifier at the top.
# Freeze the base_model
base_model.trainable = False
# Create new model on top
inputs = keras.Input(shape=(150, 150, 3))
x = data_augmentation(inputs) # Apply random data augmentation
# Pre-trained Xception weights requires that input be scaled
# from (0, 255) to a range of (-1., +1.), the rescaling layer
# outputs: `(inputs * scale) + offset`
scale_layer = keras.layers.Rescaling(scale=1 / 127.5, offset=-1)
x = scale_layer(x)
# The base model contains batchnorm layers. We want to keep them in inference mode
# when we unfreeze the base model for fine-tuning, so we make sure that the
# base_model is running in inference mode here.
x = base_model(x, training=False)
x = keras.layers.GlobalAveragePooling2D()(x)
x = keras.layers.Dropout(0.2)(x) # Regularize with dropout
outputs = keras.layers.Dense(1)(x)
model = keras.Model(inputs, outputs)
model.summary()
```
Downloading data from https://storage.googleapis.com/tensorflow/keras-applications/xception/xception_weights_tf_dim_ordering_tf_kernels_notop.h5
83683744/83683744 [==============================] - 0s 0us/step
Model: "model"
_________________________________________________________________
Layer (type) Output Shape Param #
=================================================================
input_5 (InputLayer) [(None, 150, 150, 3)] 0
sequential_3 (Sequential) (None, 150, 150, 3) 0
rescaling (Rescaling) (None, 150, 150, 3) 0
xception (Functional) (None, 5, 5, 2048) 20861480
global_average_pooling2d ( (None, 2048) 0
GlobalAveragePooling2D)
dropout (Dropout) (None, 2048) 0
dense_7 (Dense) (None, 1) 2049
=================================================================
Total params: 20863529 (79.59 MB)
Trainable params: 2049 (8.00 KB)
Non-trainable params: 20861480 (79.58 MB)
_________________________________________________________________
```
## Train the top layer
model.compile(
optimizer=keras.optimizers.Adam(),
loss=keras.losses.BinaryCrossentropy(from_logits=True),
metrics=[keras.metrics.BinaryAccuracy()],
)
epochs = 20
model.fit(train_ds, epochs=epochs, validation_data=validation_ds)
```
Epoch 1/20
142/291 [=============>................] - ETA: 35s - loss: 0.2211 - binary_accuracy: 0.8963
Corrupt JPEG data: 65 extraneous bytes before marker 0xd9
258/291 [=========================>....] - ETA: 7s - loss: 0.1831 - binary_accuracy: 0.9172
Corrupt JPEG data: 239 extraneous bytes before marker 0xd9
272/291 [===========================>..] - ETA: 4s - loss: 0.1797 - binary_accuracy: 0.9190
Corrupt JPEG data: 1153 extraneous bytes before marker 0xd9
275/291 [===========================>..] - ETA: 3s - loss: 0.1789 - binary_accuracy: 0.9194
Corrupt JPEG data: 228 extraneous bytes before marker 0xd9
291/291 [==============================] - ETA: 0s - loss: 0.1771 - binary_accuracy: 0.9205
Corrupt JPEG data: 2226 extraneous bytes before marker 0xd9
291/291 [==============================] - 89s 295ms/step - loss: 0.1771 - binary_accuracy: 0.9205 - val_loss: 0.0835 - val_binary_accuracy: 0.9652
Epoch 2/20
291/291 [==============================] - 85s 293ms/step - loss: 0.1197 - binary_accuracy: 0.9493 - val_loss: 0.0846 - val_binary_accuracy: 0.9699
Epoch 3/20
291/291 [==============================] - 83s 286ms/step - loss: 0.1135 - binary_accuracy: 0.9531 - val_loss: 0.0751 - val_binary_accuracy: 0.9708
Epoch 4/20
291/291 [==============================] - 83s 285ms/step - loss: 0.1037 - binary_accuracy: 0.9558 - val_loss: 0.0704 - val_binary_accuracy: 0.9712
Epoch 5/20
291/291 [==============================] - 83s 285ms/step - loss: 0.1024 - binary_accuracy: 0.9582 - val_loss: 0.0718 - val_binary_accuracy: 0.9733
Epoch 6/20
291/291 [==============================] - 83s 284ms/step - loss: 0.1006 - binary_accuracy: 0.9595 - val_loss: 0.0749 - val_binary_accuracy: 0.9699
Epoch 7/20
291/291 [==============================] - 83s 287ms/step - loss: 0.0961 - binary_accuracy: 0.9580 - val_loss: 0.0720 - val_binary_accuracy: 0.9699
Epoch 8/20
291/291 [==============================] - 83s 285ms/step - loss: 0.0952 - binary_accuracy: 0.9598 - val_loss: 0.0737 - val_binary_accuracy: 0.9712
Epoch 9/20
291/291 [==============================] - 83s 286ms/step - loss: 0.0984 - binary_accuracy: 0.9614 - val_loss: 0.0729 - val_binary_accuracy: 0.9708
Epoch 10/20
291/291 [==============================] - 83s 285ms/step - loss: 0.1007 - binary_accuracy: 0.9581 - val_loss: 0.0811 - val_binary_accuracy: 0.9686
Epoch 11/20
291/291 [==============================] - 83s 285ms/step - loss: 0.0960 - binary_accuracy: 0.9611 - val_loss: 0.0813 - val_binary_accuracy: 0.9703
Epoch 12/20
291/291 [==============================] - 83s 287ms/step - loss: 0.0950 - binary_accuracy: 0.9606 - val_loss: 0.0745 - val_binary_accuracy: 0.9703
Epoch 13/20
291/291 [==============================] - 84s 289ms/step - loss: 0.0970 - binary_accuracy: 0.9602 - val_loss: 0.0756 - val_binary_accuracy: 0.9703
Epoch 14/20
291/291 [==============================] - 83s 285ms/step - loss: 0.0915 - binary_accuracy: 0.9632 - val_loss: 0.0754 - val_binary_accuracy: 0.9690
Epoch 15/20
291/291 [==============================] - 84s 290ms/step - loss: 0.0938 - binary_accuracy: 0.9628 - val_loss: 0.0786 - val_binary_accuracy: 0.9682
Epoch 16/20
291/291 [==============================] - 82s 283ms/step - loss: 0.0958 - binary_accuracy: 0.9609 - val_loss: 0.0784 - val_binary_accuracy: 0.9682
Epoch 17/20
291/291 [==============================] - 83s 284ms/step - loss: 0.0907 - binary_accuracy: 0.9616 - val_loss: 0.0720 - val_binary_accuracy: 0.9721
Epoch 18/20
291/291 [==============================] - 83s 287ms/step - loss: 0.0946 - binary_accuracy: 0.9621 - val_loss: 0.0751 - val_binary_accuracy: 0.9716
Epoch 19/20
291/291 [==============================] - 83s 286ms/step - loss: 0.1004 - binary_accuracy: 0.9597 - val_loss: 0.0726 - val_binary_accuracy: 0.9703
Epoch 20/20
291/291 [==============================] - 82s 283ms/step - loss: 0.0891 - binary_accuracy: 0.9635 - val_loss: 0.0736 - val_binary_accuracy: 0.9712
```
## Do a round of fine-tuning of the entire model
Finally, let's unfreeze the base model and train the entire model end-to-end with a low
learning rate.
Importantly, although the base model becomes trainable, it is still running in
inference mode since we passed `training=False` when calling it when we built the
model. This means that the batch normalization layers inside won't update their batch
statistics. If they did, they would wreck havoc on the representations learned by the
model so far.
# Unfreeze the base_model. Note that it keeps running in inference mode
# since we passed `training=False` when calling it. This means that
# the batchnorm layers will not update their batch statistics.
# This prevents the batchnorm layers from undoing all the training
# we've done so far.
base_model.trainable = True
model.summary()
model.compile(
optimizer=keras.optimizers.Adam(1e-5), # Low learning rate
loss=keras.losses.BinaryCrossentropy(from_logits=True),
metrics=[keras.metrics.BinaryAccuracy()],
)
epochs = 10
model.fit(train_ds, epochs=epochs, validation_data=validation_ds)
```
Model: "model"
_________________________________________________________________
Layer (type) Output Shape Param #
=================================================================
input_5 (InputLayer) [(None, 150, 150, 3)] 0
sequential_3 (Sequential) (None, 150, 150, 3) 0
rescaling (Rescaling) (None, 150, 150, 3) 0
xception (Functional) (None, 5, 5, 2048) 20861480
global_average_pooling2d ( (None, 2048) 0
GlobalAveragePooling2D)
dropout (Dropout) (None, 2048) 0
dense_7 (Dense) (None, 1) 2049
=================================================================
Total params: 20863529 (79.59 MB)
Trainable params: 20809001 (79.38 MB)
Non-trainable params: 54528 (213.00 KB)
_________________________________________________________________
Epoch 1/10
291/291 [==============================] - 321s 1s/step - loss: 0.0751 - binary_accuracy: 0.9698 - val_loss: 0.0537 - val_binary_accuracy: 0.9781
Epoch 2/10
291/291 [==============================] - 302s 1s/step - loss: 0.0566 - binary_accuracy: 0.9787 - val_loss: 0.0490 - val_binary_accuracy: 0.9802
Epoch 3/10
291/291 [==============================] - 296s 1s/step - loss: 0.0455 - binary_accuracy: 0.9810 - val_loss: 0.0477 - val_binary_accuracy: 0.9794
Epoch 4/10
291/291 [==============================] - 289s 994ms/step - loss: 0.0351 - binary_accuracy: 0.9859 - val_loss: 0.0457 - val_binary_accuracy: 0.9789
Epoch 5/10
291/291 [==============================] - 289s 993ms/step - loss: 0.0268 - binary_accuracy: 0.9907 - val_loss: 0.0522 - val_binary_accuracy: 0.9794
Epoch 6/10
291/291 [==============================] - 288s 990ms/step - loss: 0.0258 - binary_accuracy: 0.9900 - val_loss: 0.0529 - val_binary_accuracy: 0.9789
Epoch 7/10
291/291 [==============================] - 286s 982ms/step - loss: 0.0209 - binary_accuracy: 0.9918 - val_loss: 0.0518 - val_binary_accuracy: 0.9776
Epoch 8/10
291/291 [==============================] - 289s 994ms/step - loss: 0.0185 - binary_accuracy: 0.9936 - val_loss: 0.0467 - val_binary_accuracy: 0.9832
Epoch 9/10
291/291 [==============================] - 289s 994ms/step - loss: 0.0150 - binary_accuracy: 0.9953 - val_loss: 0.0509 - val_binary_accuracy: 0.9802
Epoch 10/10
291/291 [==============================] - 292s 1s/step - loss: 0.0148 - binary_accuracy: 0.9952 - val_loss: 0.0501 - val_binary_accuracy: 0.9832
```
After 10 epochs, fine-tuning gains us a nice improvement here.