<br />

|---|---|---|---|---|
| [![](https://www.tensorflow.org/images/tf_logo_32px.png)View on TensorFlow.org](https://www.tensorflow.org/hub/tutorials/cord_19_embeddings_keras) | [![](https://www.tensorflow.org/images/colab_logo_32px.png)Run in Google Colab](https://colab.research.google.com/github/tensorflow/docs/blob/master/site/en/hub/tutorials/cord_19_embeddings_keras.ipynb) | [![](https://www.tensorflow.org/images/GitHub-Mark-32px.png)View on GitHub](https://github.com/tensorflow/docs/blob/master/site/en/hub/tutorials/cord_19_embeddings_keras.ipynb) | [![](https://www.tensorflow.org/images/download_logo_32px.png)Download notebook](https://storage.googleapis.com/tensorflow_docs/docs/site/en/hub/tutorials/cord_19_embeddings_keras.ipynb) | [![](https://www.tensorflow.org/images/hub_logo_32px.png)See TF Hub model](https://tfhub.dev/tensorflow/cord-19/swivel-128d/3) |

The CORD-19 Swivel text embedding module from TF-Hub (<https://tfhub.dev/tensorflow/cord-19/swivel-128d/3>)
was built to support researchers analyzing natural languages text related to COVID-19.
These embeddings were trained on the titles, authors, abstracts, body texts, and
reference titles of articles in the [CORD-19 dataset](https://api.semanticscholar.org/CorpusID:216056360).

In this colab we will:

- Analyze semantically similar words in the embedding space
- Train a classifier on the SciCite dataset using the CORD-19 embeddings

## Setup

    import functools
    import itertools
    import matplotlib.pyplot as plt
    import numpy as np
    import seaborn as sns
    import pandas as pd

    import tensorflow as tf

    import tensorflow_datasets as tfds
    import tensorflow_hub as hub

    from tqdm import trange

```
/tmpfs/src/tf_docs_env/lib/python3.11/site-packages/tensorflow_hub/__init__.py:61: UserWarning: pkg_resources is deprecated as an API. See https://setuptools.pypa.io/en/latest/pkg_resources.html. The pkg_resources package is slated for removal as early as 2025-11-30. Refrain from using this package or pin to Setuptools<81.
  from pkg_resources import parse_version
```

# Analyze the embeddings

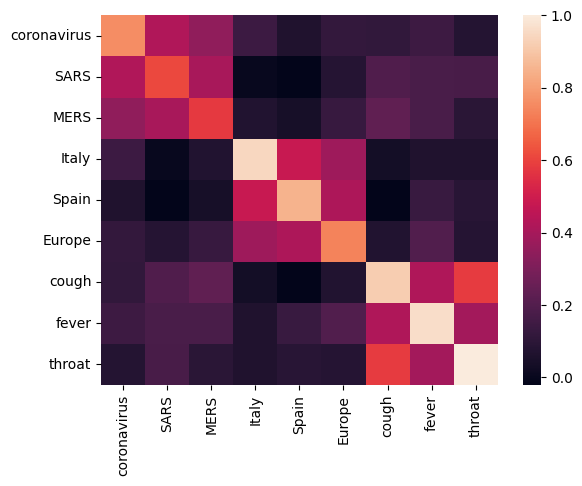
Let's start off by analyzing the embedding by calculating and plotting a correlation matrix between different terms. If the embedding learned to successfully capture the meaning of different words, the embedding vectors of semantically similar words should be close together. Let's take a look at some COVID-19 related terms.

    # Use the inner product between two embedding vectors as the similarity measure
    def plot_correlation(labels, features):
      corr = np.inner(features, features)
      corr /= np.max(corr)
      sns.heatmap(corr, xticklabels=labels, yticklabels=labels)

    # Generate embeddings for some terms
    queries = [
      # Related viruses
      'coronavirus', 'SARS', 'MERS',
      # Regions
      'Italy', 'Spain', 'Europe',
      # Symptoms
      'cough', 'fever', 'throat'
    ]

    module = hub.load('https://tfhub.dev/tensorflow/cord-19/swivel-128d/3')
    embeddings = module(queries)

    plot_correlation(queries, embeddings)

```
WARNING: All log messages before absl::InitializeLog() is called are written to STDERR
E0000 00:00:1793887273.720079   95724 cuda_platform.cc:52] failed call to cuInit: INTERNAL: CUDA error: Failed call to cuInit: CUDA_ERROR_NO_DEVICE: no CUDA-capable device is detected
```

We can see that the embedding successfully captured the meaning of the different terms. Each word is similar to the other words of its cluster (i.e. "coronavirus" highly correlates with "SARS" and "MERS"), while they are different from terms of other clusters (i.e. the similarity between "SARS" and "Spain" is close to 0).

Now let's see how we can use these embeddings to solve a specific task.

## SciCite: Citation Intent Classification

This section shows how one can use the embedding for downstream tasks such as text classification. We'll use the [SciCite dataset](https://www.tensorflow.org/datasets/catalog/scicite) from TensorFlow Datasets to classify citation intents in academic papers. Given a sentence with a citation from an academic paper, classify whether the main intent of the citation is as background information, use of methods, or comparing results.

    builder = tfds.builder(name='scicite')
    builder.download_and_prepare()
    train_data, validation_data, test_data = builder.as_dataset(
        split=('train', 'validation', 'test'),
        as_supervised=True)
![png](https://www.tensorflow.org/static/hub/tutorials/cord_19_embeddings_keras_files/output_Ghc-CzT8DDaZ_0.png)

### Let's take a look at a few labeled examples from the training set

<br />

<button type="button" class="button-red button expand-control">Toggle code</button>

<br />

    NUM_EXAMPLES =   10

    TEXT_FEATURE_NAME = builder.info.supervised_keys[0]
    LABEL_NAME = builder.info.supervised_keys[1]

    def label2str(numeric_label):
      m = builder.info.features[LABEL_NAME].names
      return m[numeric_label]

    data = next(iter(train_data.batch(NUM_EXAMPLES)))


    pd.DataFrame({
        TEXT_FEATURE_NAME: [ex.numpy().decode('utf8') for ex in data[0]],
        LABEL_NAME: [label2str(x) for x in data[1]]
    })

<br />

<br />

<iframe src="https:///frame/hub/tutorials/cord_19_embeddings_keras_5bdd6047b0cca44ebb3d89c413f915ee75c0bfd91c6270eb01ce17b8ef5d6a9f.frame" class="framebox inherit-locale " allow="clipboard-write https://" allowfullscreen is-upgraded></iframe>

## Training a citaton intent classifier

We'll train a classifier on the [SciCite dataset](https://www.tensorflow.org/datasets/catalog/scicite) using Keras. Let's build a model which use the CORD-19 embeddings with a classification layer on top.

### Hyperparameters

<br />

<button type="button" class="button-red button expand-control">Toggle code</button>

<br />

    EMBEDDING = 'https://tfhub.dev/tensorflow/cord-19/swivel-128d/3' 
    TRAINABLE_MODULE = False 

    hub_layer = hub.KerasLayer(EMBEDDING, input_shape=[], 
                               dtype=tf.string, trainable=TRAINABLE_MODULE)

    model = tf.keras.Sequential()
    model.add(hub_layer)
    model.add(tf.keras.layers.Dense(3))
    model.summary()
    model.compile(optimizer='adam',
                  loss=tf.keras.losses.SparseCategoricalCrossentropy(from_logits=True),
                  metrics=['accuracy'])

<br />

<br />

```
Model: "sequential"
_________________________________________________________________
Layer (type)                Output Shape              Param #
=================================================================
keras_layer (KerasLayer)    (None, 128)               17301632

dense (Dense)               (None, 3)                 387

=================================================================
Total params: 17302019 (132.00 MB)
Trainable params: 387 (1.51 KB)
Non-trainable params: 17301632 (132.00 MB)
_________________________________________________________________
```

## Train and evaluate the model

Let's train and evaluate the model to see the performance on the SciCite task

    EPOCHS = 35
    BATCH_SIZE = 32

    history = model.fit(train_data.shuffle(10000).batch(BATCH_SIZE),
                        epochs=EPOCHS,
                        validation_data=validation_data.batch(BATCH_SIZE),
                        verbose=1)

```
Epoch 1/35
257/257 [==============================] - 2s 4ms/step - loss: 0.8583 - accuracy: 0.6339 - val_loss: 0.7580 - val_accuracy: 0.7041
Epoch 2/35
257/257 [==============================] - 1s 3ms/step - loss: 0.6873 - accuracy: 0.7221 - val_loss: 0.6680 - val_accuracy: 0.7413
Epoch 3/35
257/257 [==============================] - 1s 3ms/step - loss: 0.6199 - accuracy: 0.7563 - val_loss: 0.6234 - val_accuracy: 0.7555
Epoch 4/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5863 - accuracy: 0.7751 - val_loss: 0.6020 - val_accuracy: 0.7544
Epoch 5/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5663 - accuracy: 0.7818 - val_loss: 0.5857 - val_accuracy: 0.7718
Epoch 6/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5539 - accuracy: 0.7864 - val_loss: 0.5769 - val_accuracy: 0.7707
Epoch 7/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5449 - accuracy: 0.7897 - val_loss: 0.5716 - val_accuracy: 0.7718
Epoch 8/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5384 - accuracy: 0.7906 - val_loss: 0.5668 - val_accuracy: 0.7773
Epoch 9/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5331 - accuracy: 0.7940 - val_loss: 0.5624 - val_accuracy: 0.7795
Epoch 10/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5285 - accuracy: 0.7924 - val_loss: 0.5590 - val_accuracy: 0.7740
Epoch 11/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5247 - accuracy: 0.7959 - val_loss: 0.5552 - val_accuracy: 0.7806
Epoch 12/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5222 - accuracy: 0.7946 - val_loss: 0.5540 - val_accuracy: 0.7762
Epoch 13/35
257/257 [==============================] - 3s 3ms/step - loss: 0.5193 - accuracy: 0.7964 - val_loss: 0.5559 - val_accuracy: 0.7707
Epoch 14/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5162 - accuracy: 0.7957 - val_loss: 0.5501 - val_accuracy: 0.7817
Epoch 15/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5152 - accuracy: 0.7953 - val_loss: 0.5509 - val_accuracy: 0.7784
Epoch 16/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5138 - accuracy: 0.7962 - val_loss: 0.5502 - val_accuracy: 0.7828
Epoch 17/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5119 - accuracy: 0.7978 - val_loss: 0.5508 - val_accuracy: 0.7784
Epoch 18/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5105 - accuracy: 0.7979 - val_loss: 0.5490 - val_accuracy: 0.7784
Epoch 19/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5090 - accuracy: 0.7991 - val_loss: 0.5456 - val_accuracy: 0.7871
Epoch 20/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5083 - accuracy: 0.7986 - val_loss: 0.5479 - val_accuracy: 0.7860
Epoch 21/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5076 - accuracy: 0.7991 - val_loss: 0.5475 - val_accuracy: 0.7806
Epoch 22/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5069 - accuracy: 0.7995 - val_loss: 0.5469 - val_accuracy: 0.7838
Epoch 23/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5059 - accuracy: 0.7991 - val_loss: 0.5475 - val_accuracy: 0.7817
Epoch 24/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5051 - accuracy: 0.8001 - val_loss: 0.5453 - val_accuracy: 0.7828
Epoch 25/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5043 - accuracy: 0.7985 - val_loss: 0.5485 - val_accuracy: 0.7828
Epoch 26/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5034 - accuracy: 0.8005 - val_loss: 0.5443 - val_accuracy: 0.7806
Epoch 27/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5032 - accuracy: 0.8014 - val_loss: 0.5450 - val_accuracy: 0.7893
Epoch 28/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5025 - accuracy: 0.7997 - val_loss: 0.5460 - val_accuracy: 0.7871
Epoch 29/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5017 - accuracy: 0.8017 - val_loss: 0.5450 - val_accuracy: 0.7871
Epoch 30/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5011 - accuracy: 0.8008 - val_loss: 0.5458 - val_accuracy: 0.7904
Epoch 31/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5005 - accuracy: 0.8024 - val_loss: 0.5442 - val_accuracy: 0.7838
Epoch 32/35
257/257 [==============================] - 1s 3ms/step - loss: 0.5006 - accuracy: 0.8021 - val_loss: 0.5435 - val_accuracy: 0.7893
Epoch 33/35
257/257 [==============================] - 1s 3ms/step - loss: 0.4999 - accuracy: 0.8034 - val_loss: 0.5450 - val_accuracy: 0.7893
Epoch 34/35
257/257 [==============================] - 1s 3ms/step - loss: 0.4995 - accuracy: 0.8016 - val_loss: 0.5435 - val_accuracy: 0.7915
Epoch 35/35
257/257 [==============================] - 1s 3ms/step - loss: 0.4993 - accuracy: 0.8028 - val_loss: 0.5468 - val_accuracy: 0.7871
```

    from matplotlib import pyplot as plt
    def display_training_curves(training, validation, title, subplot):
      if subplot%10==1: # set up the subplots on the first call
        plt.subplots(figsize=(10,10), facecolor='#F0F0F0')
        plt.tight_layout()
      ax = plt.subplot(subplot)
      ax.set_facecolor('#F8F8F8')
      ax.plot(training)
      ax.plot(validation)
      ax.set_title('model '+ title)
      ax.set_ylabel(title)
      ax.set_xlabel('epoch')
      ax.legend(['train', 'valid.'])

    display_training_curves(history.history['accuracy'], history.history['val_accuracy'], 'accuracy', 211)
    display_training_curves(history.history['loss'], history.history['val_loss'], 'loss', 212)

![png](https://www.tensorflow.org/static/hub/tutorials/cord_19_embeddings_keras_files/output_nnQfxevhLKld_0.png)

## Evaluate the model

And let's see how the model performs. Two values will be returned. Loss (a number which represents our error, lower values are better), and accuracy.

    results = model.evaluate(test_data.batch(512), verbose=2)

    for name, value in zip(model.metrics_names, results):
      print('%s: %.3f' % (name, value))

```
4/4 - 0s - loss: 0.5388 - accuracy: 0.7827 - 286ms/epoch - 72ms/step
loss: 0.539
accuracy: 0.783
```

We can see that the loss quickly decreases while especially the accuracy rapidly increases. Let's plot some examples to check how the prediction relates to the true labels:

    prediction_dataset = next(iter(test_data.batch(20)))

    prediction_texts = [ex.numpy().decode('utf8') for ex in prediction_dataset[0]]
    prediction_labels = [label2str(x) for x in prediction_dataset[1]]

    predictions = [
        label2str(x) for x in np.argmax(model.predict(prediction_texts), axis=-1)]


    pd.DataFrame({
        TEXT_FEATURE_NAME: prediction_texts,
        LABEL_NAME: prediction_labels,
        'prediction': predictions
    })

```
1/1 [==============================] - 0s 121ms/step
```
<iframe src="https:///frame/hub/tutorials/cord_19_embeddings_keras_1621ee03ee65d9175c81d7e3f4fda19a0fec32b9b51d38e416f118235adf88be.frame" class="framebox inherit-locale " allow="clipboard-write https://" allowfullscreen is-upgraded></iframe>

We can see that for this random sample, the model predicts the correct label most of the times, indicating that it can embed scientific sentences pretty well.

# What's next?

Now that you've gotten to know a bit more about the CORD-19 Swivel embeddings from TF-Hub, we encourage you to participate in the CORD-19 Kaggle competition to contribute to gaining scientific insights from COVID-19 related academic texts.

- Participate in the [CORD-19 Kaggle Challenge](https://www.kaggle.com/allen-institute-for-ai/CORD-19-research-challenge)
- Learn more about the [COVID-19 Open Research Dataset (CORD-19)](https://api.semanticscholar.org/CorpusID:216056360)
- See documentation and more about the TF-Hub embeddings at <https://tfhub.dev/tensorflow/cord-19/swivel-128d/3>
- Explore the CORD-19 embedding space with the [TensorFlow Embedding Projector](http://projector.tensorflow.org/?config=https://storage.googleapis.com/tfhub-examples/tensorflow/cord-19/swivel-128d/3/tensorboard/projector_config.json)