|---|---|---|---|
| [View on TensorFlow.org](https://www.tensorflow.org/text/tutorials/image_captioning) | [Run in Google Colab](https://colab.research.google.com/github/tensorflow/text/blob/master/docs/tutorials/image_captioning.ipynb) | [View on GitHub](https://github.com/tensorflow/text/blob/master/docs/tutorials/image_captioning.ipynb) | [Download notebook](https://storage.googleapis.com/tensorflow_docs/text/docs/tutorials/image_captioning.ipynb) |
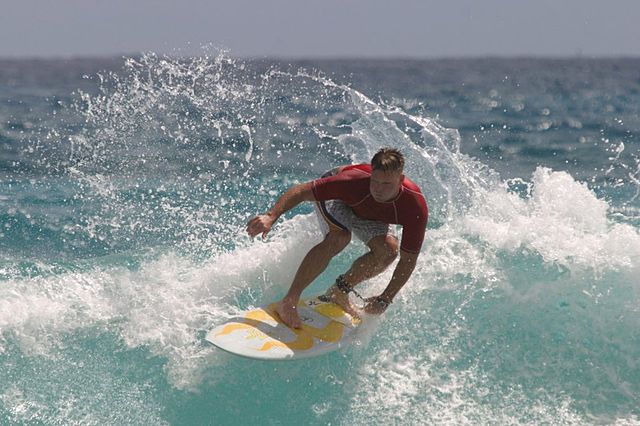
Given an image like the example below, your goal is to generate a
caption such as "a surfer riding on a wave".
|---|
|  |
The model architecture used here is inspired by [Show, Attend and Tell: Neural Image Caption Generation with Visual Attention](https://arxiv.org/abs/1502.03044), but has been updated to use a 2-layer Transformer-decoder. To get the most out of this tutorial you should have some experience with [text generation](https://www.tensorflow.org/text/tutorials/text_generation), [seq2seq models \& attention](https://www.tensorflow.org/text/tutorials/nmt_with_attention), or [transformers](https://www.tensorflow.org/text/tutorials/transformer).
The model architecture built in this tutorial is shown below. Features are extracted from the image, and passed to the cross-attention layers of the Transformer-decoder.
| The model architecture |
|---|
| 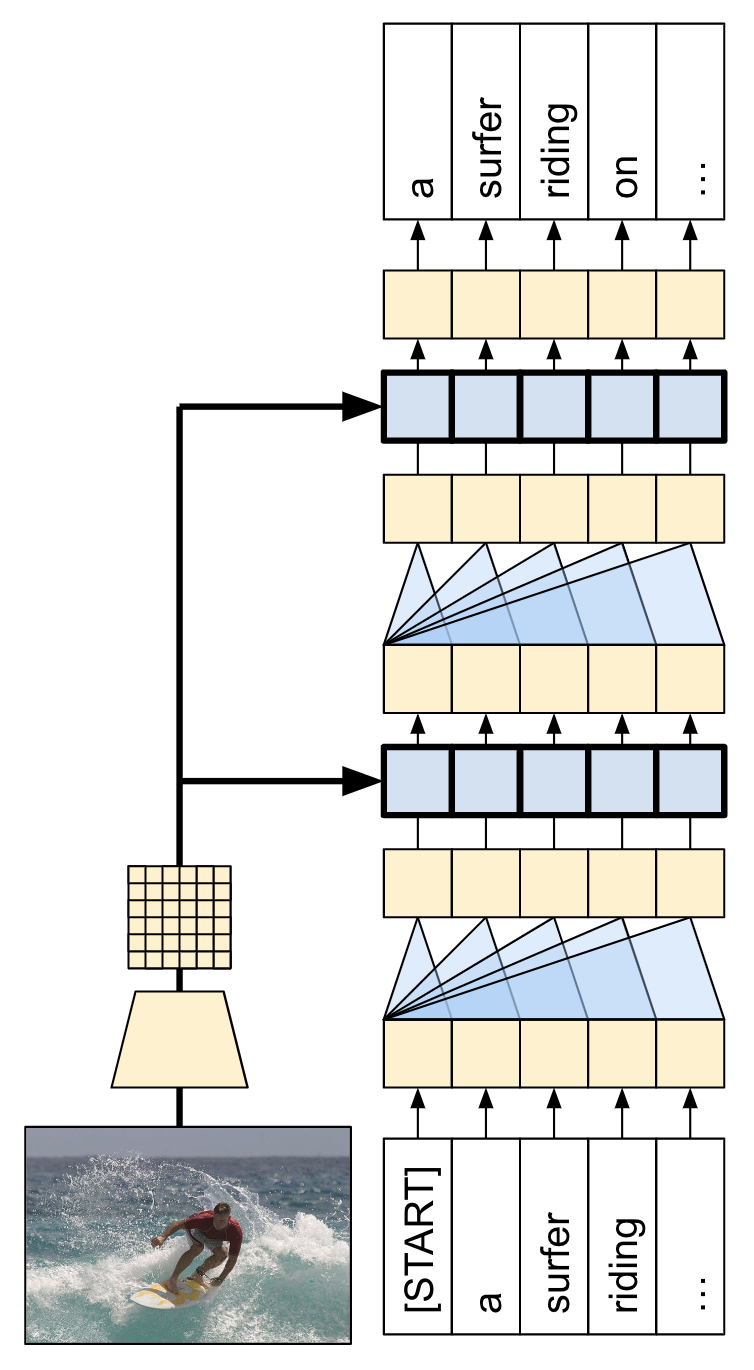 |
The transformer decoder is mainly built from attention layers. It uses self-attention to process the sequence being generated, and it uses cross-attention to attend to the image.
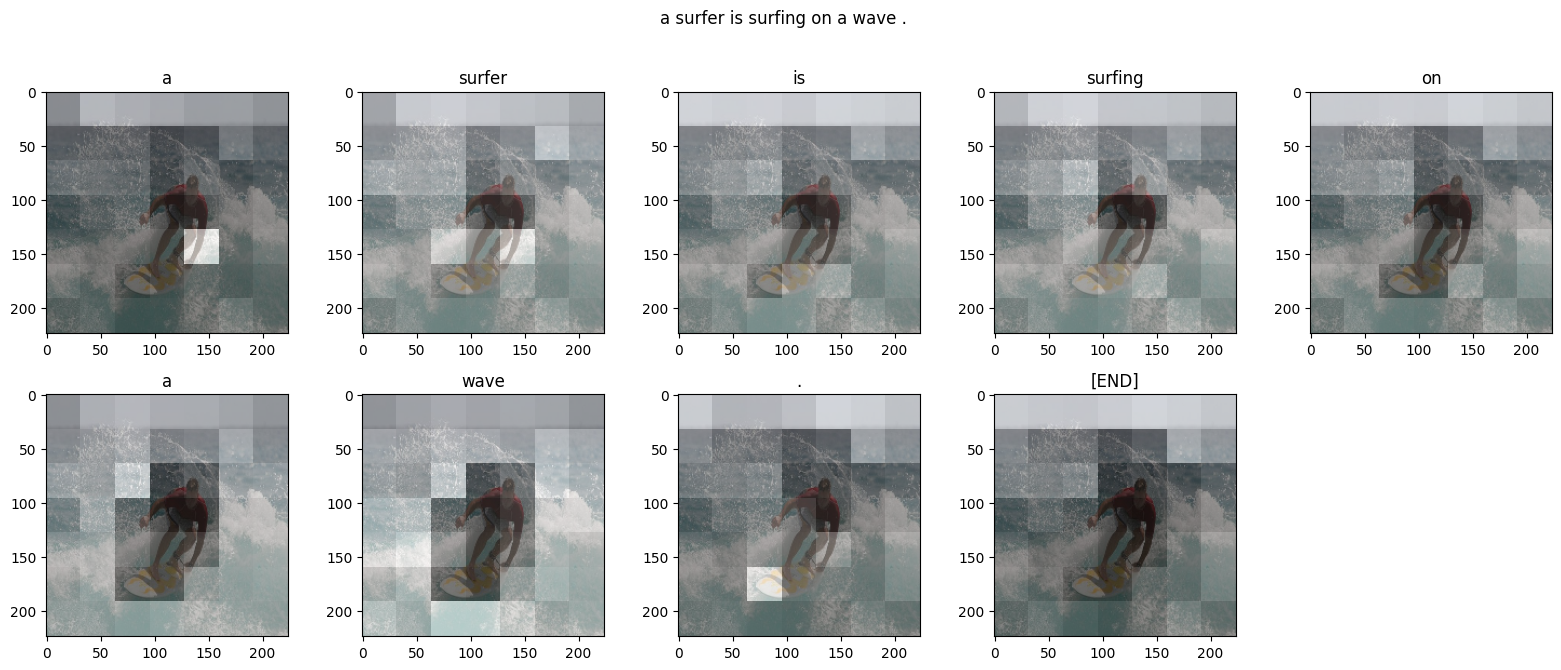
By inspecting the attention weights of the cross attention layers you will see what parts of the image the model is looking at as it generates words.
This notebook is an end-to-end example. When you run the notebook, it downloads a dataset, extracts and caches the image features, and trains a decoder model. It then uses the model to generate captions on new images.
## Setup
pip install -q -U tensorflow-text tensorflow_datasets tf-keras
pip install -q einops
This tutorial uses lots of imports, mostly for loading the dataset(s).
import os
os.environ['TF_USE_LEGACY_KERAS'] = '1'
import concurrent.futures
import collections
import dataclasses
import hashlib
import itertools
import json
import math
import pathlib
import random
import re
import string
import time
import urllib.request
import einops
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
from PIL import Image
import requests
import tqdm
import tensorflow as tf
import tensorflow_hub as hub
import tensorflow_text as text
import tensorflow_datasets as tfds
```
/tmpfs/src/tf_docs_env/lib/python3.11/site-packages/tensorflow_hub/__init__.py:61: UserWarning: pkg_resources is deprecated as an API. See https://setuptools.pypa.io/en/latest/pkg_resources.html. The pkg_resources package is slated for removal as early as 2025-11-30. Refrain from using this package or pin to Setuptools<81.
from pkg_resources import parse_version
```
## \[Optional\] Data handling
This section downloads a captions dataset and prepares it for training. It tokenizes the input text, and caches the results of running all the images through a pretrained feature-extractor model. It's not critical to understand everything in this section.
### Choose a dataset
This tutorial is set up to give a choice of datasets. Either [Flickr8k](https://www.ijcai.org/Proceedings/15/Papers/593.pdf) or a small slice of the [Conceptual Captions](https://ai.google.com/research/ConceptualCaptions/) dataset. These two are downloaded and converted from scratch, but it wouldn't be hard to convert the tutorial to use the caption datasets available in [TensorFlow Datasets](https://www.tensorflow.org/datasets): [Coco Captions](https://www.tensorflow.org/datasets/catalog/coco_captions) and the full [Conceptual Captions](https://www.tensorflow.org/datasets/community_catalog/huggingface/conceptual_captions).
#### Flickr8k
def flickr8k(path='flickr8k'):
path = pathlib.Path(path)
if len(list(path.rglob('*'))) < 16197:
tf.keras.utils.get_file(
origin='https://github.com/jbrownlee/Datasets/releases/download/Flickr8k/Flickr8k_Dataset.zip',
cache_dir='.',
cache_subdir=path,
extract=True)
tf.keras.utils.get_file(
origin='https://github.com/jbrownlee/Datasets/releases/download/Flickr8k/Flickr8k_text.zip',
cache_dir='.',
cache_subdir=path,
extract=True)
captions = (path/"Flickr8k.token.txt").read_text().splitlines()
captions = (line.split('\t') for line in captions)
captions = ((fname.split('#')[0], caption) for (fname, caption) in captions)
cap_dict = collections.defaultdict(list)
for fname, cap in captions:
cap_dict[fname].append(cap)
train_files = (path/'Flickr_8k.trainImages.txt').read_text().splitlines()
train_captions = [(str(path/'Flicker8k_Dataset'/fname), cap_dict[fname]) for fname in train_files]
test_files = (path/'Flickr_8k.testImages.txt').read_text().splitlines()
test_captions = [(str(path/'Flicker8k_Dataset'/fname), cap_dict[fname]) for fname in test_files]
train_ds = tf.data.experimental.from_list(train_captions)
test_ds = tf.data.experimental.from_list(test_captions)
return train_ds, test_ds
#### Conceptual Captions
def conceptual_captions(*, data_dir="conceptual_captions", num_train, num_val):
def iter_index(index_path):
with open(index_path) as f:
for line in f:
caption, url = line.strip().split('\t')
yield caption, url
def download_image_urls(data_dir, urls):
ex = concurrent.futures.ThreadPoolExecutor(max_workers=100)
def save_image(url):
hash = hashlib.sha1(url.encode())
# Name the files after the hash of the URL.
file_path = data_dir/f'{hash.hexdigest()}.jpeg'
if file_path.exists():
# Only download each file once.
return file_path
try:
result = requests.get(url, timeout=5)
except Exception:
file_path = None
else:
file_path.write_bytes(result.content)
return file_path
result = []
out_paths = ex.map(save_image, urls)
for file_path in tqdm.tqdm(out_paths, total=len(urls)):
result.append(file_path)
return result
def ds_from_index_file(index_path, data_dir, count):
data_dir.mkdir(exist_ok=True)
index = list(itertools.islice(iter_index(index_path), count))
captions = [caption for caption, url in index]
urls = [url for caption, url in index]
paths = download_image_urls(data_dir, urls)
new_captions = []
new_paths = []
for cap, path in zip(captions, paths):
if path is None:
# Download failed, so skip this pair.
continue
new_captions.append(cap)
new_paths.append(path)
new_paths = [str(p) for p in new_paths]
ds = tf.data.Dataset.from_tensor_slices((new_paths, new_captions))
ds = ds.map(lambda path,cap: (path, cap[tf.newaxis])) # 1 caption per image
return ds
data_dir = pathlib.Path(data_dir)
train_index_path = tf.keras.utils.get_file(
origin='https://storage.googleapis.com/gcc-data/Train/GCC-training.tsv',
cache_subdir=data_dir,
cache_dir='.')
val_index_path = tf.keras.utils.get_file(
origin='https://storage.googleapis.com/gcc-data/Validation/GCC-1.1.0-Validation.tsv',
cache_subdir=data_dir,
cache_dir='.')
train_raw = ds_from_index_file(train_index_path, data_dir=data_dir/'train', count=num_train)
test_raw = ds_from_index_file(val_index_path, data_dir=data_dir/'val', count=num_val)
return train_raw, test_raw
#### Download the dataset
The Flickr8k is a good choice because it contains 5-captions per image, more data for a smaller download.
choose = 'flickr8k'
if choose == 'flickr8k':
train_raw, test_raw = flickr8k()
else:
train_raw, test_raw = conceptual_captions(num_train=10000, num_val=5000)
```
Downloading data from https://github.com/jbrownlee/Datasets/releases/download/Flickr8k/Flickr8k_Dataset.zip
1115419746/1115419746 [==============================] - 45s 0us/step
Downloading data from https://github.com/jbrownlee/Datasets/releases/download/Flickr8k/Flickr8k_text.zip
2340801/2340801 [==============================] - 0s 0us/step
```
The loaders for both datasets above return [`tf.data.Dataset`](https://www.tensorflow.org/api_docs/python/tf/data/Dataset)s containing `(image_path, captions)` pairs. The Flickr8k dataset contains 5 captions per image, while Conceptual Captions has 1:
train_raw.element_spec
```
(TensorSpec(shape=(), dtype=tf.string, name=None),
TensorSpec(shape=(5,), dtype=tf.string, name=None))
```
for ex_path, ex_captions in train_raw.take(1):
print(ex_path)
print(ex_captions)
```
tf.Tensor(b'flickr8k/Flicker8k_Dataset/2513260012_03d33305cf.jpg', shape=(), dtype=string)
tf.Tensor(
[b'A black dog is running after a white dog in the snow .'
b'Black dog chasing brown dog through snow'
b'Two dogs chase each other across the snowy ground .'
b'Two dogs play together in the snow .'
b'Two dogs running through a low lying body of water .'], shape=(5,), dtype=string)
```
### Image feature extractor
You will use an image model (pretrained on imagenet) to extract the features from each image. The model was trained as an image classifier, but setting `include_top=False` returns the model without the final classification layer, so you can use the last layer of feature-maps:
IMAGE_SHAPE=(224, 224, 3)
mobilenet = tf.keras.applications.MobileNetV3Small(
input_shape=IMAGE_SHAPE,
include_top=False,
include_preprocessing=True)
mobilenet.trainable=False
```
Downloading data from https://storage.googleapis.com/tensorflow/keras-applications/mobilenet_v3/weights_mobilenet_v3_small_224_1.0_float_no_top_v2.h5
4334752/4334752 [==============================] - 0s 0us/step
```
Here's a function to load an image and resize it for the model:
def load_image(image_path):
img = tf.io.read_file(image_path)
img = tf.io.decode_jpeg(img, channels=3)
img = tf.image.resize(img, IMAGE_SHAPE[:-1])
return img
The model returns a feature map for each image in the input batch:
test_img_batch = load_image(ex_path)[tf.newaxis, :]
print(test_img_batch.shape)
print(mobilenet(test_img_batch).shape)
```
(1, 224, 224, 3)
(1, 7, 7, 576)
```
### Setup the text tokenizer/vectorizer
You will transform the text captions into integer sequences using the [TextVectorization](https://www.tensorflow.org/api_docs/python/tf/keras/layers/TextVectorization) layer, with the following steps:
- Use [adapt](https://www.tensorflow.org/api_docs/python/tf/keras/layers/TextVectorization#adapt) to iterate over all captions, split the captions into words, and compute a vocabulary of the top words.
- Tokenize all captions by mapping each word to its index in the vocabulary. All output sequences will be padded to length 50.
- Create word-to-index and index-to-word mappings to display results.
def standardize(s):
s = tf.strings.lower(s)
s = tf.strings.regex_replace(s, f'[{re.escape(string.punctuation)}]', '')
s = tf.strings.join(['[START]', s, '[END]'], separator=' ')
return s
# Use the top 5000 words for a vocabulary.
vocabulary_size = 5000
tokenizer = tf.keras.layers.TextVectorization(
max_tokens=vocabulary_size,
standardize=standardize,
ragged=True)
# Learn the vocabulary from the caption data.
tokenizer.adapt(train_raw.map(lambda fp,txt: txt).unbatch().batch(1024))
tokenizer.get_vocabulary()[:10]
```
['',
'[UNK]',
np.str_('a'),
np.str_('[START]'),
np.str_('[END]'),
np.str_('in'),
np.str_('the'),
np.str_('on'),
np.str_('is'),
np.str_('and')]
```
t = tokenizer([['a cat in a hat'], ['a robot dog']])
t
```
```
# Create mappings for words to indices and indices to words.
word_to_index = tf.keras.layers.StringLookup(
mask_token="",
vocabulary=tokenizer.get_vocabulary())
index_to_word = tf.keras.layers.StringLookup(
mask_token="",
vocabulary=tokenizer.get_vocabulary(),
invert=True)
w = index_to_word(t)
w.to_list()
```
[[b'[START]', b'a', b'cat', b'in', b'a', b'hat', b'[END]'],
[b'[START]', b'a', b'robot', b'dog', b'[END]']]
```
tf.strings.reduce_join(w, separator=' ', axis=-1).numpy()
```
array([b'[START] a cat in a hat [END]', b'[START] a robot dog [END]'],
dtype=object)
```
### Prepare the datasets
The `train_raw` and `test_raw` datasets contain 1:many `(image, captions)` pairs.
This function will replicate the image so there are 1:1 images to captions:
def match_shapes(images, captions):
caption_shape = einops.parse_shape(captions, 'b c')
captions = einops.rearrange(captions, 'b c -> (b c)')
images = einops.repeat(
images, 'b ... -> (b c) ...',
c = caption_shape['c'])
return images, captions
for ex_paths, ex_captions in train_raw.batch(32).take(1):
break
print('image paths:', ex_paths.shape)
print('captions:', ex_captions.shape)
print()
ex_paths, ex_captions = match_shapes(images=ex_paths, captions=ex_captions)
print('image_paths:', ex_paths.shape)
print('captions:', ex_captions.shape)
```
image paths: (32,)
captions: (32, 5)
image_paths: (160,)
captions: (160,)
```
To be compatible with keras training the dataset should contain `(inputs, labels)` pairs. For text generation the tokens are both an input and the labels, shifted by one step. This function will convert an `(images, texts)` pair to an `((images, input_tokens), label_tokens)` pair:
def prepare_txt(imgs, txts):
tokens = tokenizer(txts)
input_tokens = tokens[..., :-1]
label_tokens = tokens[..., 1:]
return (imgs, input_tokens), label_tokens
This function adds operations to a dataset. The steps are:
1. Load the images (and ignore images that fail to load).
2. Replicate images to match the number of captions.
3. Shuffle and rebatch the `image, caption` pairs.
4. Tokenize the text, shift the tokens and add `label_tokens`.
5. Convert the text from a `RaggedTensor` representation to padded dense `Tensor` representation.
def prepare_dataset(ds, tokenizer, batch_size=32, shuffle_buffer=1000):
# Load the images and make batches.
ds = (ds
.shuffle(10000)
.map(lambda path, caption: (load_image(path), caption))
.apply(tf.data.experimental.ignore_errors())
.batch(batch_size))
def to_tensor(inputs, labels):
(images, in_tok), out_tok = inputs, labels
return (images, in_tok.to_tensor()), out_tok.to_tensor()
return (ds
.map(match_shapes, tf.data.AUTOTUNE)
.unbatch()
.shuffle(shuffle_buffer)
.batch(batch_size)
.map(prepare_txt, tf.data.AUTOTUNE)
.map(to_tensor, tf.data.AUTOTUNE)
)
You could install the feature extractor in your model and train on the datasets like this:
train_ds = prepare_dataset(train_raw, tokenizer)
train_ds.element_spec
```
WARNING:tensorflow:From /tmpfs/tmp/ipykernel_29150/1004139779.py:6: ignore_errors (from tensorflow.python.data.experimental.ops.error_ops) is deprecated and will be removed in a future version.
Instructions for updating:
Use `tf.data.Dataset.ignore_errors` instead.
((TensorSpec(shape=(None, 224, 224, 3), dtype=tf.float32, name=None),
TensorSpec(shape=(None, None), dtype=tf.int64, name=None)),
TensorSpec(shape=(None, None), dtype=tf.int64, name=None))
```
test_ds = prepare_dataset(test_raw, tokenizer)
test_ds.element_spec
```
((TensorSpec(shape=(None, 224, 224, 3), dtype=tf.float32, name=None),
TensorSpec(shape=(None, None), dtype=tf.int64, name=None)),
TensorSpec(shape=(None, None), dtype=tf.int64, name=None))
```
### \[Optional\] Cache the image features
Since the image feature extractor is not changing, and this tutorial is not using image augmentation, the image features can be cached. Same for the text tokenization. The time it takes to set up the cache is earned back on each epoch during training and validation. The code below defines two functions `save_dataset` and `load_dataset`:
def save_dataset(ds, save_path, image_model, tokenizer, shards=10, batch_size=32):
# Load the images and make batches.
ds = (ds
.map(lambda path, caption: (load_image(path), caption))
.apply(tf.data.experimental.ignore_errors())
.batch(batch_size))
# Run the feature extractor on each batch
# Don't do this in a .map, because tf.data runs on the CPU.
def gen():
for (images, captions) in tqdm.tqdm(ds):
feature_maps = image_model(images)
feature_maps, captions = match_shapes(feature_maps, captions)
yield feature_maps, captions
# Wrap the generator in a new tf.data.Dataset.
new_ds = tf.data.Dataset.from_generator(
gen,
output_signature=(
tf.TensorSpec(shape=image_model.output_shape),
tf.TensorSpec(shape=(None,), dtype=tf.string)))
# Apply the tokenization
new_ds = (new_ds
.map(prepare_txt, tf.data.AUTOTUNE)
.unbatch()
.shuffle(1000))
# Save the dataset into shard files.
def shard_func(i, item):
return i % shards
new_ds.enumerate().save(save_path, shard_func=shard_func)
def load_dataset(save_path, batch_size=32, shuffle=1000, cycle_length=2):
def custom_reader_func(datasets):
datasets = datasets.shuffle(1000)
return datasets.interleave(lambda x: x, cycle_length=cycle_length)
ds = tf.data.Dataset.load(save_path, reader_func=custom_reader_func)
def drop_index(i, x):
return x
ds = (ds
.map(drop_index, tf.data.AUTOTUNE)
.shuffle(shuffle)
.padded_batch(batch_size)
.prefetch(tf.data.AUTOTUNE))
return ds
save_dataset(train_raw, 'train_cache', mobilenet, tokenizer)
save_dataset(test_raw, 'test_cache', mobilenet, tokenizer)
```
0it [00:00, ?it/s]
1it [00:01, 1.42s/it]
2it [00:01, 1.49it/s]
3it [00:01, 2.28it/s]
4it [00:01, 3.06it/s]
5it [00:02, 3.74it/s]
6it [00:02, 4.34it/s]
7it [00:02, 4.85it/s]
8it [00:02, 5.21it/s]
9it [00:02, 5.51it/s]
10it [00:02, 5.73it/s]
11it [00:03, 5.88it/s]
12it [00:03, 6.02it/s]
13it [00:03, 6.29it/s]
14it [00:03, 6.49it/s]
15it [00:03, 6.47it/s]
16it [00:03, 6.43it/s]
17it [00:03, 6.47it/s]
18it [00:04, 6.42it/s]
19it [00:04, 6.40it/s]
20it [00:04, 6.37it/s]
21it [00:04, 6.36it/s]
22it [00:04, 6.35it/s]
23it [00:04, 6.39it/s]
24it [00:05, 6.40it/s]
25it [00:05, 6.44it/s]
26it [00:05, 6.42it/s]
27it [00:05, 6.41it/s]
28it [00:05, 6.42it/s]
29it [00:05, 6.42it/s]
30it [00:05, 6.42it/s]
31it [00:06, 6.36it/s]
32it [00:06, 6.47it/s]
33it [00:06, 6.63it/s]
34it [00:06, 6.59it/s]
35it [00:06, 6.54it/s]
36it [00:06, 6.51it/s]
37it [00:07, 6.63it/s]
38it [00:07, 6.73it/s]
39it [00:07, 6.68it/s]
40it [00:07, 6.61it/s]
41it [00:07, 6.53it/s]
42it [00:07, 6.40it/s]
43it [00:07, 6.36it/s]
44it [00:08, 6.37it/s]
45it [00:08, 6.55it/s]
46it [00:08, 6.67it/s]
47it [00:08, 6.61it/s]
48it [00:08, 6.56it/s]
49it [00:08, 6.48it/s]
50it [00:09, 6.42it/s]
51it [00:09, 6.40it/s]
52it [00:09, 6.41it/s]
53it [00:09, 6.42it/s]
54it [00:09, 6.40it/s]
55it [00:09, 6.54it/s]
56it [00:09, 6.71it/s]
57it [00:10, 6.64it/s]
58it [00:10, 6.55it/s]
59it [00:10, 6.55it/s]
60it [00:10, 6.50it/s]
61it [00:10, 6.44it/s]
62it [00:10, 6.45it/s]
63it [00:11, 6.45it/s]
64it [00:11, 6.47it/s]
65it [00:11, 6.47it/s]
66it [00:11, 6.43it/s]
67it [00:11, 6.40it/s]
68it [00:11, 6.40it/s]
69it [00:11, 6.54it/s]
70it [00:12, 6.52it/s]
71it [00:12, 6.46it/s]
72it [00:12, 6.36it/s]
73it [00:12, 6.35it/s]
74it [00:12, 6.39it/s]
75it [00:12, 6.40it/s]
76it [00:13, 6.35it/s]
77it [00:13, 6.38it/s]
78it [00:13, 6.39it/s]
79it [00:13, 6.36it/s]
80it [00:13, 6.33it/s]
81it [00:13, 6.43it/s]
82it [00:13, 6.38it/s]
83it [00:14, 6.35it/s]
84it [00:14, 6.34it/s]
85it [00:14, 6.42it/s]
86it [00:14, 6.38it/s]
87it [00:14, 6.41it/s]
88it [00:14, 6.48it/s]
89it [00:15, 6.47it/s]
90it [00:15, 6.58it/s]
91it [00:15, 6.66it/s]
92it [00:15, 6.73it/s]
93it [00:15, 6.64it/s]
94it [00:15, 6.55it/s]
95it [00:15, 6.50it/s]
96it [00:16, 6.51it/s]
97it [00:16, 6.53it/s]
98it [00:16, 6.50it/s]
99it [00:16, 6.44it/s]
100it [00:16, 6.46it/s]
101it [00:16, 6.46it/s]
102it [00:17, 6.45it/s]
103it [00:17, 6.44it/s]
104it [00:17, 6.48it/s]
105it [00:17, 6.47it/s]
106it [00:17, 6.47it/s]
107it [00:17, 6.65it/s]
108it [00:17, 6.61it/s]
109it [00:18, 6.55it/s]
110it [00:18, 6.52it/s]
111it [00:18, 6.49it/s]
112it [00:18, 6.47it/s]
113it [00:18, 6.47it/s]
114it [00:18, 6.46it/s]
115it [00:19, 6.46it/s]
116it [00:19, 6.50it/s]
117it [00:19, 6.54it/s]
118it [00:19, 6.46it/s]
119it [00:19, 6.39it/s]
120it [00:19, 6.39it/s]
121it [00:19, 6.53it/s]
122it [00:20, 6.50it/s]
123it [00:20, 6.47it/s]
124it [00:20, 6.48it/s]
125it [00:20, 6.47it/s]
126it [00:20, 6.45it/s]
127it [00:20, 6.49it/s]
128it [00:21, 6.45it/s]
129it [00:21, 6.44it/s]
130it [00:21, 6.63it/s]
131it [00:21, 6.41it/s]
132it [00:21, 6.37it/s]
133it [00:21, 6.41it/s]
134it [00:21, 6.40it/s]
135it [00:22, 6.39it/s]
136it [00:22, 6.43it/s]
137it [00:22, 6.44it/s]
138it [00:22, 6.45it/s]
139it [00:22, 6.40it/s]
140it [00:22, 6.57it/s]
141it [00:23, 6.71it/s]
142it [00:23, 6.84it/s]
143it [00:23, 6.90it/s]
144it [00:23, 6.95it/s]
145it [00:23, 6.82it/s]
146it [00:23, 6.71it/s]
147it [00:23, 6.61it/s]
148it [00:24, 6.56it/s]
149it [00:24, 6.54it/s]
150it [00:24, 6.50it/s]
151it [00:24, 6.48it/s]
152it [00:24, 6.44it/s]
153it [00:24, 6.43it/s]
154it [00:25, 6.43it/s]
155it [00:25, 6.41it/s]
156it [00:25, 6.41it/s]
157it [00:25, 6.41it/s]
158it [00:25, 6.40it/s]
159it [00:25, 6.39it/s]
160it [00:25, 6.40it/s]
161it [00:26, 6.41it/s]
162it [00:26, 6.41it/s]
163it [00:26, 6.41it/s]
164it [00:26, 6.41it/s]
165it [00:26, 6.44it/s]
166it [00:26, 6.47it/s]
167it [00:27, 6.45it/s]
168it [00:27, 6.43it/s]
169it [00:27, 6.41it/s]
170it [00:27, 6.39it/s]
171it [00:27, 6.50it/s]
172it [00:27, 6.61it/s]
173it [00:27, 6.70it/s]
174it [00:28, 6.64it/s]
175it [00:28, 6.58it/s]
176it [00:28, 6.55it/s]
177it [00:28, 6.69it/s]
178it [00:28, 6.60it/s]
179it [00:28, 6.70it/s]
180it [00:29, 6.82it/s]
181it [00:29, 6.71it/s]
182it [00:29, 6.63it/s]
183it [00:29, 6.57it/s]
184it [00:29, 6.54it/s]
185it [00:29, 6.51it/s]
186it [00:29, 6.60it/s]
187it [00:30, 6.75it/s]
188it [00:30, 6.01it/s]
188it [00:30, 6.21it/s]
0it [00:00, ?it/s]
1it [00:00, 2.71it/s]
2it [00:00, 4.12it/s]
3it [00:00, 4.94it/s]
4it [00:00, 5.45it/s]
5it [00:00, 5.68it/s]
6it [00:01, 5.85it/s]
7it [00:01, 5.96it/s]
8it [00:01, 6.08it/s]
9it [00:01, 6.14it/s]
10it [00:01, 6.32it/s]
11it [00:01, 6.34it/s]
12it [00:02, 6.35it/s]
13it [00:02, 6.37it/s]
14it [00:02, 6.40it/s]
15it [00:02, 6.40it/s]
16it [00:02, 6.37it/s]
17it [00:02, 6.46it/s]
18it [00:03, 6.58it/s]
19it [00:03, 6.51it/s]
20it [00:03, 6.44it/s]
21it [00:03, 6.43it/s]
22it [00:03, 6.40it/s]
23it [00:03, 6.35it/s]
24it [00:03, 6.33it/s]
25it [00:04, 6.31it/s]
26it [00:04, 6.30it/s]
27it [00:04, 6.33it/s]
28it [00:04, 6.36it/s]
29it [00:04, 6.36it/s]
30it [00:04, 6.46it/s]
31it [00:05, 6.60it/s]
32it [00:05, 6.15it/s]
32it [00:05, 6.11it/s]
```
## Data ready for training
After those preprocessing steps, here are the datasets:
train_ds = load_dataset('train_cache')
test_ds = load_dataset('test_cache')
train_ds.element_spec
```
((TensorSpec(shape=(None, 7, 7, 576), dtype=tf.float32, name=None),
TensorSpec(shape=(None, None), dtype=tf.int64, name=None)),
TensorSpec(shape=(None, None), dtype=tf.int64, name=None))
```
The dataset now returns `(input, label)` pairs suitable for training with keras. The `inputs` are `(images, input_tokens)` pairs. The `images` have been processed with the feature-extractor model. For each location in the `input_tokens` the model looks at the text so far and tries to predict the next which is lined up at the same location in the `labels`.
for (inputs, ex_labels) in train_ds.take(1):
(ex_img, ex_in_tok) = inputs
print(ex_img.shape)
print(ex_in_tok.shape)
print(ex_labels.shape)
```
(32, 7, 7, 576)
(32, 20)
(32, 20)
```
The input tokens and the labels are the same, just shifted by 1 step:
print(ex_in_tok[0].numpy())
print(ex_labels[0].numpy())
```
[ 3 2 12 8 61 115 2 51 0 0 0 0 0 0 0 0 0 0
0 0]
[ 2 12 8 61 115 2 51 4 0 0 0 0 0 0 0 0 0 0
0 0]
```
## A Transformer decoder model
This model assumes that the pretrained image encoder is sufficient, and just focuses on building the text decoder. This tutorial uses a 2-layer Transformer-decoder.
The implementations are almost identical to those in the [Transformers tutorial](https://www.tensorflow.org/text/tutorials/transformer). Refer back to it for more details.
| The Transformer encoder and decoder. |
|---|
| 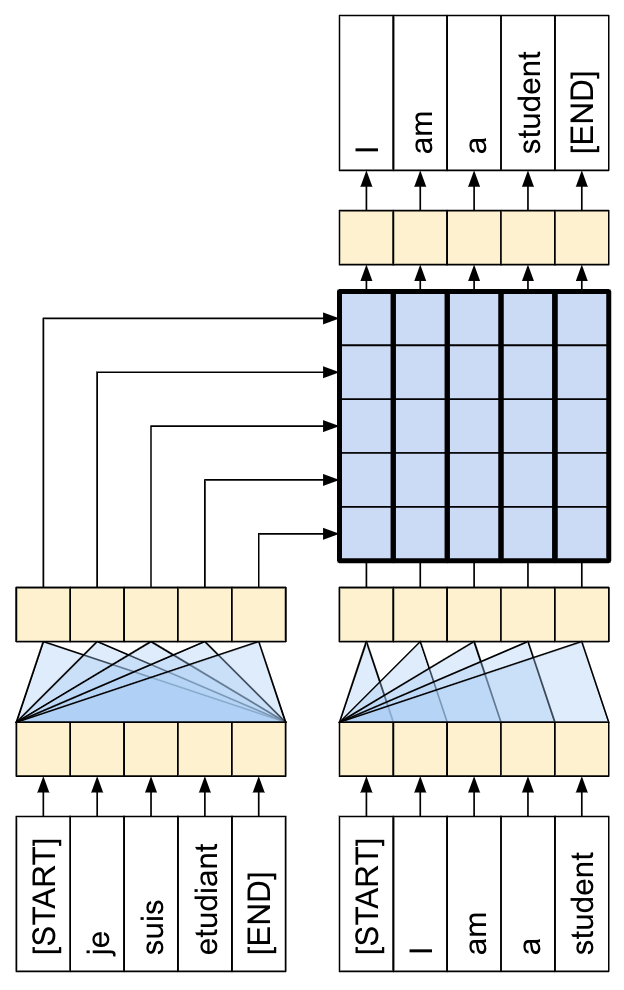 |
The model will be implemented in three main parts:
1. Input - The token embedding and positional encoding (`SeqEmbedding`).
2. Decoder - A stack of transformer decoder layers (`DecoderLayer`) where each contains:
1. A causal self attention later (`CausalSelfAttention`), where each output location can attend to the output so far.
2. A cross attention layer (`CrossAttention`) where each output location can attend to the input image.
3. A feed forward network (`FeedForward`) layer which further processes each output location independently.
3. Output - A multiclass-classification over the output vocabulary.
### Input
The input text has already been split up into tokens and converted to sequences of IDs.
Remember that unlike a CNN or RNN the Transformer's attention layers are invariant to the order of the sequence. Without some positional input, it just sees an unordered set not a sequence. So in addition to a simple vector embedding for each token ID, the embedding layer will also include an embedding for each position in the sequence.
The `SeqEmbedding` layer defined below:
- It looks up the embedding vector for each token.
- It looks up an embedding vector for each sequence location.
- It adds the two together.
- It uses `mask_zero=True` to initialize the keras-masks for the model.
> [!NOTE]
> **Note:** This implementation learns the position embeddings instead of using fixed embeddings like in the [Transformer tutorial](https://www.tensorflow.org/text/tutorials/transformer). Learning the embeddings is slightly less code, but doesn't generalize to longer sequences.
class SeqEmbedding(tf.keras.layers.Layer):
def __init__(self, vocab_size, max_length, depth):
super().__init__()
self.pos_embedding = tf.keras.layers.Embedding(input_dim=max_length, output_dim=depth)
self.token_embedding = tf.keras.layers.Embedding(
input_dim=vocab_size,
output_dim=depth,
mask_zero=True)
self.add = tf.keras.layers.Add()
def call(self, seq):
seq = self.token_embedding(seq) # (batch, seq, depth)
x = tf.range(tf.shape(seq)[1]) # (seq)
x = x[tf.newaxis, :] # (1, seq)
x = self.pos_embedding(x) # (1, seq, depth)
return self.add([seq,x])
### Decoder
The decoder is a standard Transformer-decoder, it contains a stack of `DecoderLayers` where each contains three sublayers: a `CausalSelfAttention`, a `CrossAttention`, and a`FeedForward`. The implementations are almost identical to the [Transformer tutorial](https://www.tensorflow.org/text/tutorials/transformer), refer to it for more details.
The `CausalSelfAttention` layer is below:
class CausalSelfAttention(tf.keras.layers.Layer):
def __init__(self, **kwargs):
super().__init__()
self.mha = tf.keras.layers.MultiHeadAttention(**kwargs)
# Use Add instead of + so the keras mask propagates through.
self.add = tf.keras.layers.Add()
self.layernorm = tf.keras.layers.LayerNormalization()
def call(self, x):
attn = self.mha(query=x, value=x,
use_causal_mask=True)
x = self.add([x, attn])
return self.layernorm(x)
The `CrossAttention` layer is below. Note the use of `return_attention_scores`.
class CrossAttention(tf.keras.layers.Layer):
def __init__(self,**kwargs):
super().__init__()
self.mha = tf.keras.layers.MultiHeadAttention(**kwargs)
self.add = tf.keras.layers.Add()
self.layernorm = tf.keras.layers.LayerNormalization()
def call(self, x, y, **kwargs):
attn, attention_scores = self.mha(
query=x, value=y,
return_attention_scores=True)
self.last_attention_scores = attention_scores
x = self.add([x, attn])
return self.layernorm(x)
The `FeedForward` layer is below. Remember that a [`layers.Dense`](https://www.tensorflow.org/api_docs/python/tf/keras/layers/Dense) layer is applied to the last axis of the input. The input will have a shape of `(batch, sequence, channels)`, so it automatically applies pointwise across the `batch` and `sequence` axes.
class FeedForward(tf.keras.layers.Layer):
def __init__(self, units, dropout_rate=0.1):
super().__init__()
self.seq = tf.keras.Sequential([
tf.keras.layers.Dense(units=2*units, activation='relu'),
tf.keras.layers.Dense(units=units),
tf.keras.layers.Dropout(rate=dropout_rate),
])
self.layernorm = tf.keras.layers.LayerNormalization()
def call(self, x):
x = x + self.seq(x)
return self.layernorm(x)
Next arrange these three layers into a larger `DecoderLayer`. Each decoder layer applies the three smaller layers in sequence. After each sublayer the shape of `out_seq` is `(batch, sequence, channels)`. The decoder layer also returns the `attention_scores` for later visualizations.
class DecoderLayer(tf.keras.layers.Layer):
def __init__(self, units, num_heads=1, dropout_rate=0.1):
super().__init__()
self.self_attention = CausalSelfAttention(num_heads=num_heads,
key_dim=units,
dropout=dropout_rate)
self.cross_attention = CrossAttention(num_heads=num_heads,
key_dim=units,
dropout=dropout_rate)
self.ff = FeedForward(units=units, dropout_rate=dropout_rate)
def call(self, inputs, training=False):
in_seq, out_seq = inputs
# Text input
out_seq = self.self_attention(out_seq)
out_seq = self.cross_attention(out_seq, in_seq)
self.last_attention_scores = self.cross_attention.last_attention_scores
out_seq = self.ff(out_seq)
return out_seq
### Output
At minimum the output layer needs a [`layers.Dense`](https://www.tensorflow.org/api_docs/python/tf/keras/layers/Dense) layer to generate logit-predictions for each token at each location.
But there are a few other features you can add to make this work a little better:
1. **Handle bad tokens** : The model will be generating text. It should
never generate a pad, unknown, or start token (`''`, `'[UNK]'`,
`'[START]'`). So set the bias for these to a large negative value.
> > [!NOTE]
> > **Note:** You'll need to ignore these tokens in the loss function as well.
>
2. **Smart initialization** : The default initialization of a dense layer will
give a model that initially predicts each token with almost uniform
likelihood. The actual token distribution is far from uniform. The
optimal value for the initial bias of the output layer is the log of the
probability of each token. So include an `adapt` method to count the tokens
and set the optimal initial bias. This reduces the initial loss from the
entropy of the uniform distribution (`log(vocabulary_size)`) to the marginal
entropy of the distribution (`-p*log(p)`).
class TokenOutput(tf.keras.layers.Layer):
def __init__(self, tokenizer, banned_tokens=('', '[UNK]', '[START]'), **kwargs):
super().__init__()
self.dense = tf.keras.layers.Dense(
units=tokenizer.vocabulary_size(), **kwargs)
self.tokenizer = tokenizer
self.banned_tokens = banned_tokens
self.bias = None
def adapt(self, ds):
counts = collections.Counter()
vocab_dict = {name: id
for id, name in enumerate(self.tokenizer.get_vocabulary())}
for tokens in tqdm.tqdm(ds):
counts.update(tokens.numpy().flatten())
counts_arr = np.zeros(shape=(self.tokenizer.vocabulary_size(),))
counts_arr[np.array(list(counts.keys()), dtype=np.int32)] = list(counts.values())
counts_arr = counts_arr[:]
for token in self.banned_tokens:
counts_arr[vocab_dict[token]] = 0
total = counts_arr.sum()
p = counts_arr/total
p[counts_arr==0] = 1.0
log_p = np.log(p) # log(1) == 0
entropy = -(log_p*p).sum()
print()
print(f"Uniform entropy: {np.log(self.tokenizer.vocabulary_size()):0.2f}")
print(f"Marginal entropy: {entropy:0.2f}")
self.bias = log_p
self.bias[counts_arr==0] = -1e9
def call(self, x):
x = self.dense(x)
# TODO(b/250038731): Fix this.
# An Add layer doesn't work because of the different shapes.
# This clears the mask, that's okay because it prevents keras from rescaling
# the losses.
return x + self.bias
The smart initialization will significantly reduce the initial loss:
output_layer = TokenOutput(tokenizer, banned_tokens=('', '[UNK]', '[START]'))
# This might run a little faster if the dataset didn't also have to load the image data.
output_layer.adapt(train_ds.map(lambda inputs, labels: labels))
```
0%| | 0/938 [00:00 b (h w) c')
if txt.dtype == tf.string:
# Apply the tokenizer if you get string inputs.
txt = tokenizer(txt)
txt = self.seq_embedding(txt)
# Look at the image
for dec_layer in self.decoder_layers:
txt = dec_layer(inputs=(image, txt))
txt = self.output_layer(txt)
return txt
model = Captioner(tokenizer, feature_extractor=mobilenet, output_layer=output_layer,
units=256, dropout_rate=0.5, num_layers=2, num_heads=2)
### Generate captions
Before getting into training, write a bit of code to generate captions. You'll use this to see how training is progressing.
Start by downloading a test image:
image_url = 'https://tensorflow.org/images/surf.jpg'
image_path = tf.keras.utils.get_file('surf.jpg', origin=image_url)
image = load_image(image_path)
```
Downloading data from https://tensorflow.org/images/surf.jpg
64400/64400 [==============================] - 0s 0us/step
```
To caption an image with this model:
- Extract the `img_features`
- Initialize the list of output tokens with a `[START]` token.
- Pass `img_features` and `tokens` into the model.
- It returns a list of logits.
- Choose the next token based on those logits.
- Add it to the list of tokens, and continue the loop.
- If it generates an `'[END]'` token, break out of the loop.
So add a "simple" method to do just that:
@Captioner.add_method
def simple_gen(self, image, temperature=1):
initial = self.word_to_index([['[START]']]) # (batch, sequence)
img_features = self.feature_extractor(image[tf.newaxis, ...])
tokens = initial # (batch, sequence)
for n in range(50):
preds = self((img_features, tokens)).numpy() # (batch, sequence, vocab)
preds = preds[:,-1, :] #(batch, vocab)
if temperature==0:
next = tf.argmax(preds, axis=-1)[:, tf.newaxis] # (batch, 1)
else:
next = tf.random.categorical(preds/temperature, num_samples=1) # (batch, 1)
tokens = tf.concat([tokens, next], axis=1) # (batch, sequence)
if next[0] == self.word_to_index('[END]'):
break
words = index_to_word(tokens[0, 1:-1])
result = tf.strings.reduce_join(words, axis=-1, separator=' ')
return result.numpy().decode()
Here are some generated captions for that image, the model's untrained, so they don't make much sense yet:
for t in (0.0, 0.5, 1.0):
result = model.simple_gen(image, temperature=t)
print(result)
```
a
and is its the a a
```
The temperature parameter allows you to interpolate between 3 modes:
1. Greedy decoding (`temperature=0.0`) - Chooses the most likely next token at each step.
2. Random sampling according to the logits (`temperature=1.0`).
3. Uniform random sampling (`temperature >> 1.0`).
Since the model is untrained, and it used the frequency-based initialization, the "greedy" output (first) usually only contains the most common tokens: `['a', '.', '[END]']`.
## Train
To train the model you'll need several additional components:
- The Loss and metrics
- The Optimizer
- Optional Callbacks
### Losses and metrics
Here's an implementation of a masked loss and accuracy:
When calculating the mask for the loss, note the `loss < 1e8`. This term discards the artificial, impossibly high losses for the `banned_tokens`.
def masked_loss(labels, preds):
loss = tf.nn.sparse_softmax_cross_entropy_with_logits(labels, preds)
mask = (labels != 0) & (loss < 1e8)
mask = tf.cast(mask, loss.dtype)
loss = loss*mask
loss = tf.reduce_sum(loss)/tf.reduce_sum(mask)
return loss
def masked_acc(labels, preds):
mask = tf.cast(labels!=0, tf.float32)
preds = tf.argmax(preds, axis=-1)
labels = tf.cast(labels, tf.int64)
match = tf.cast(preds == labels, mask.dtype)
acc = tf.reduce_sum(match*mask)/tf.reduce_sum(mask)
return acc
### Callbacks
For feedback during training setup a [`keras.callbacks.Callback`](https://www.tensorflow.org/api_docs/python/tf/keras/callbacks/Callback) to generate some captions for the surfer image at the end of each epoch.
class GenerateText(tf.keras.callbacks.Callback):
def __init__(self):
image_url = 'https://tensorflow.org/images/surf.jpg'
image_path = tf.keras.utils.get_file('surf.jpg', origin=image_url)
self.image = load_image(image_path)
def on_epoch_end(self, epochs=None, logs=None):
print()
print()
for t in (0.0, 0.5, 1.0):
result = self.model.simple_gen(self.image, temperature=t)
print(result)
print()
It generates three output strings, like the earlier example, like before the first is "greedy", choosing the argmax of the logits at each step.
g = GenerateText()
g.model = model
g.on_epoch_end(0)
```
a
the
```
Also use [`callbacks.EarlyStopping`](https://www.tensorflow.org/api_docs/python/tf/keras/callbacks/EarlyStopping) to terminate training when the model starts to overfit.
callbacks = [
GenerateText(),
tf.keras.callbacks.EarlyStopping(
patience=5, restore_best_weights=True)]
### Train
Configure and execute the training.
model.compile(optimizer=tf.keras.optimizers.Adam(learning_rate=1e-4),
loss=masked_loss,
metrics=[masked_acc])
For more frequent reporting, use the [`Dataset.repeat()`](https://www.tensorflow.org/api_docs/python/tf/data/Dataset#repeat) method, and set the `steps_per_epoch` and `validation_steps` arguments to [`Model.fit`](https://www.tensorflow.org/api_docs/python/tf/keras/Model#fit).
With this setup on `Flickr8k` a full pass over the dataset is 900+ batches, but below the reporting-epochs are 100 steps.
history = model.fit(
train_ds.repeat(),
steps_per_epoch=100,
validation_data=test_ds.repeat(),
validation_steps=20,
epochs=100,
callbacks=callbacks)
```
Epoch 1/100
100/100 [==============================] - ETA: 0s - loss: 5.0222 - masked_acc: 0.1974
a man in a man in a man in a
a person in a are red of a yellow
the lay white walks boy and a trick
100/100 [==============================] - 25s 134ms/step - loss: 5.0222 - masked_acc: 0.1974 - val_loss: 4.6717 - val_masked_acc: 0.2347
Epoch 2/100
100/100 [==============================] - ETA: 0s - loss: 4.6489 - masked_acc: 0.2497
a man in a red in the water
a dog is in the is and water
a dog in the cross a life in a dog
100/100 [==============================] - 7s 72ms/step - loss: 4.6489 - masked_acc: 0.2497 - val_loss: 4.3606 - val_masked_acc: 0.2684
Epoch 3/100
100/100 [==============================] - ETA: 0s - loss: 4.4377 - masked_acc: 0.2770
a man in a red in the water
a man wearing a white dog with a jump of a another
a man in a slide
100/100 [==============================] - 6s 63ms/step - loss: 4.4377 - masked_acc: 0.2770 - val_loss: 4.1899 - val_masked_acc: 0.2960
Epoch 4/100
99/100 [============================>.] - ETA: 0s - loss: 4.2674 - masked_acc: 0.2927
a man in a red shirt is running in the water
a man in a red and red in the water
a fluffy bike up through to two
100/100 [==============================] - 7s 67ms/step - loss: 4.2643 - masked_acc: 0.2927 - val_loss: 4.0660 - val_masked_acc: 0.3007
Epoch 5/100
98/100 [============================>.] - ETA: 0s - loss: 4.1338 - masked_acc: 0.3060
a man in a red shirt is running in the water
a man is in the water
a boy wearing a yellow one is pulling with a green dog
100/100 [==============================] - 6s 60ms/step - loss: 4.1346 - masked_acc: 0.3061 - val_loss: 3.9963 - val_masked_acc: 0.3104
Epoch 6/100
100/100 [==============================] - ETA: 0s - loss: 4.0014 - masked_acc: 0.3210
a man in a red shirt is running in the water
a young boy in the water
a woman running on the edge of a guys
100/100 [==============================] - 6s 60ms/step - loss: 4.0014 - masked_acc: 0.3210 - val_loss: 3.8831 - val_masked_acc: 0.3261
Epoch 7/100
100/100 [==============================] - ETA: 0s - loss: 3.9546 - masked_acc: 0.3261
a man in a red shirt is running in the water
a woman in the water
a little boy is walking away from a road
100/100 [==============================] - 5s 54ms/step - loss: 3.9546 - masked_acc: 0.3261 - val_loss: 3.8884 - val_masked_acc: 0.3172
Epoch 8/100
100/100 [==============================] - ETA: 0s - loss: 3.8584 - masked_acc: 0.3323
a man in a red shirt is running in the water
a girl in a red shirt and white water
a person in his water
100/100 [==============================] - 6s 59ms/step - loss: 3.8584 - masked_acc: 0.3323 - val_loss: 3.7154 - val_masked_acc: 0.3220
Epoch 9/100
98/100 [============================>.] - ETA: 0s - loss: 3.7739 - masked_acc: 0.3384
a man in a red shirt is running through the water
a man is through a a water
a blonde small helmet on a store by
100/100 [==============================] - 6s 57ms/step - loss: 3.7777 - masked_acc: 0.3381 - val_loss: 3.6358 - val_masked_acc: 0.3454
Epoch 10/100
99/100 [============================>.] - ETA: 0s - loss: 3.6992 - masked_acc: 0.3439
a man in a blue shirt is riding a pool
a man in a blue jacket is riding a pool
a black walking along a into a pool at the legs
100/100 [==============================] - 6s 63ms/step - loss: 3.7007 - masked_acc: 0.3435 - val_loss: 3.5897 - val_masked_acc: 0.3457
Epoch 11/100
100/100 [==============================] - ETA: 0s - loss: 3.6470 - masked_acc: 0.3476
a man in a blue shirt is jumping in the water
a man wearing a blue jacket is playing in a white water
a person wearing another girl is wearing a bald couple a trunks
100/100 [==============================] - 6s 64ms/step - loss: 3.6470 - masked_acc: 0.3476 - val_loss: 3.5362 - val_masked_acc: 0.3482
Epoch 12/100
99/100 [============================>.] - ETA: 0s - loss: 3.5879 - masked_acc: 0.3524
a man in a blue shirt is jumping in the water
a young boy in the water
the child sitting in the pool
100/100 [==============================] - 5s 53ms/step - loss: 3.5879 - masked_acc: 0.3523 - val_loss: 3.5167 - val_masked_acc: 0.3579
Epoch 13/100
100/100 [==============================] - ETA: 0s - loss: 3.5963 - masked_acc: 0.3492
a man in a red shirt is riding a pool
a man with a red jacket has a pool
a child orange dog is in a pool
100/100 [==============================] - 6s 57ms/step - loss: 3.5963 - masked_acc: 0.3492 - val_loss: 3.4156 - val_masked_acc: 0.3587
Epoch 14/100
99/100 [============================>.] - ETA: 0s - loss: 3.5090 - masked_acc: 0.3545
a man in a blue shirt is jumping into the water
a man is jumping over the water
a person on the ocean is riding onlookers in the
100/100 [==============================] - 6s 59ms/step - loss: 3.5128 - masked_acc: 0.3541 - val_loss: 3.4031 - val_masked_acc: 0.3545
Epoch 15/100
98/100 [============================>.] - ETA: 0s - loss: 3.5136 - masked_acc: 0.3590
a man in a red shirt is riding a wave
a man wearing a red shirt is riding a wave
two people are in the water
100/100 [==============================] - 5s 55ms/step - loss: 3.5129 - masked_acc: 0.3592 - val_loss: 3.3937 - val_masked_acc: 0.3527
Epoch 16/100
100/100 [==============================] - ETA: 0s - loss: 3.4694 - masked_acc: 0.3599
a man in a red shirt is swimming pool
a man is riding a wave in the water
a boy is wearing a catcher pool
100/100 [==============================] - 6s 55ms/step - loss: 3.4694 - masked_acc: 0.3599 - val_loss: 3.3784 - val_masked_acc: 0.3603
Epoch 17/100
98/100 [============================>.] - ETA: 0s - loss: 3.4615 - masked_acc: 0.3604
a man in a red shirt is riding a wave
a man in a blue shirt is riding a wave
two girls in a bikini runs into a pool
100/100 [==============================] - 6s 58ms/step - loss: 3.4591 - masked_acc: 0.3601 - val_loss: 3.3278 - val_masked_acc: 0.3673
Epoch 18/100
99/100 [============================>.] - ETA: 0s - loss: 3.4235 - masked_acc: 0.3606
a man in a red shirt is riding a wave
a person in a red shirt is jumping into a pool
a boy wearing a yellow helmet wearing sunglasses
100/100 [==============================] - 6s 58ms/step - loss: 3.4214 - masked_acc: 0.3607 - val_loss: 3.2755 - val_masked_acc: 0.3629
Epoch 19/100
98/100 [============================>.] - ETA: 0s - loss: 3.3608 - masked_acc: 0.3670
a man in a blue shirt is swimming pool
a man is riding a large wave
a biker child wearing catch a wetsuit is looking at a pool
100/100 [==============================] - 6s 57ms/step - loss: 3.3605 - masked_acc: 0.3674 - val_loss: 3.3160 - val_masked_acc: 0.3630
Epoch 20/100
100/100 [==============================] - ETA: 0s - loss: 3.2835 - masked_acc: 0.3748
a man in a blue shirt is swimming in the water
a man is in a pool
a man and a dog skiing down over a scenery
100/100 [==============================] - 5s 54ms/step - loss: 3.2835 - masked_acc: 0.3748 - val_loss: 3.3300 - val_masked_acc: 0.3602
Epoch 21/100
99/100 [============================>.] - ETA: 0s - loss: 3.2688 - masked_acc: 0.3751
a man in a blue shirt is swimming pool
a man in a red shirt and blue pool
two people are like waves
100/100 [==============================] - 5s 53ms/step - loss: 3.2703 - masked_acc: 0.3750 - val_loss: 3.1825 - val_masked_acc: 0.3714
Epoch 22/100
99/100 [============================>.] - ETA: 0s - loss: 3.2350 - masked_acc: 0.3774
a man in a blue shirt is riding a wave
a surfer in a blue pool
a man and white girl jumping into a blue tennis toy his while a steep yellow trunks toy water
100/100 [==============================] - 6s 63ms/step - loss: 3.2361 - masked_acc: 0.3773 - val_loss: 3.1756 - val_masked_acc: 0.3806
Epoch 23/100
100/100 [==============================] - ETA: 0s - loss: 3.2588 - masked_acc: 0.3743
a man in a yellow shirt is riding a wave
a man in a blue wetsuit is doing a surfboard
a man and a jeans running for the wave
100/100 [==============================] - 6s 59ms/step - loss: 3.2588 - masked_acc: 0.3743 - val_loss: 3.1521 - val_masked_acc: 0.3734
Epoch 24/100
100/100 [==============================] - ETA: 0s - loss: 3.2335 - masked_acc: 0.3776
a man in a red shirt is swimming pool
a man in a red kayak is running in the ocean
man in white shorts catching an flip in a leash
100/100 [==============================] - 6s 58ms/step - loss: 3.2335 - masked_acc: 0.3776 - val_loss: 3.1751 - val_masked_acc: 0.3693
Epoch 25/100
98/100 [============================>.] - ETA: 0s - loss: 3.2204 - masked_acc: 0.3793
a man in a blue shirt is riding a wave
a man in a blue shirt is jumping up a wave
orange player in midair slides up on a pool
100/100 [==============================] - 6s 57ms/step - loss: 3.2215 - masked_acc: 0.3792 - val_loss: 3.2460 - val_masked_acc: 0.3682
Epoch 26/100
99/100 [============================>.] - ETA: 0s - loss: 3.1644 - masked_acc: 0.3815
a man in a blue shirt is riding a wave
a person is riding a wave
a child kayaking on a blue kayak wearing a black sweater is
100/100 [==============================] - 6s 57ms/step - loss: 3.1645 - masked_acc: 0.3814 - val_loss: 3.0814 - val_masked_acc: 0.3831
Epoch 27/100
100/100 [==============================] - ETA: 0s - loss: 3.1620 - masked_acc: 0.3826
a man in a red shirt is riding a wave
a man in a red shirt and a blue surfboard
a surfboard kicking a surfboard under a surfboard
100/100 [==============================] - 6s 56ms/step - loss: 3.1620 - masked_acc: 0.3826 - val_loss: 3.1092 - val_masked_acc: 0.3809
Epoch 28/100
99/100 [============================>.] - ETA: 0s - loss: 3.1255 - masked_acc: 0.3871
a man in a blue wetsuit is riding a wave
a man in a wetsuit is riding a wave
a surfer he on a wetsuit flies down
100/100 [==============================] - 6s 57ms/step - loss: 3.1237 - masked_acc: 0.3870 - val_loss: 3.1443 - val_masked_acc: 0.3739
Epoch 29/100
99/100 [============================>.] - ETA: 0s - loss: 3.0711 - masked_acc: 0.3899
a man in a yellow shirt is riding a wave
a person is surfing a wave
a person airborne on a beach
100/100 [==============================] - 5s 53ms/step - loss: 3.0718 - masked_acc: 0.3897 - val_loss: 3.1240 - val_masked_acc: 0.3840
Epoch 30/100
98/100 [============================>.] - ETA: 0s - loss: 3.0812 - masked_acc: 0.3911
a man in a yellow shirt is riding a wave
a man is riding a surfboard
an
100/100 [==============================] - 5s 50ms/step - loss: 3.0776 - masked_acc: 0.3915 - val_loss: 3.0589 - val_masked_acc: 0.3854
Epoch 31/100
99/100 [============================>.] - ETA: 0s - loss: 3.0443 - masked_acc: 0.3926
a surfer in a red shirt is riding a wave
a surfer in a wetsuit is surfing in the ocean
a man wearing red gear at a stick
100/100 [==============================] - 6s 59ms/step - loss: 3.0442 - masked_acc: 0.3925 - val_loss: 3.0509 - val_masked_acc: 0.3860
Epoch 32/100
98/100 [============================>.] - ETA: 0s - loss: 3.0160 - masked_acc: 0.3933
a man in a yellow kayak is in the ocean
a person in a yellow shirt is surfing in a pool
a man waterskiing
100/100 [==============================] - 5s 54ms/step - loss: 3.0184 - masked_acc: 0.3933 - val_loss: 3.0532 - val_masked_acc: 0.3897
Epoch 33/100
98/100 [============================>.] - ETA: 0s - loss: 3.0178 - masked_acc: 0.3953
a surfer in a red shirt is riding a wave
a surfer in a red and white surfer in a yellow wave
a person riding down a wave in a kayak
100/100 [==============================] - 6s 60ms/step - loss: 3.0153 - masked_acc: 0.3955 - val_loss: 2.9970 - val_masked_acc: 0.3928
Epoch 34/100
98/100 [============================>.] - ETA: 0s - loss: 3.0296 - masked_acc: 0.3937
a surfer in a wetsuit is riding a wave
a girl in a blue wetsuit on a surfboard
an on a large wave leaning on orange surfboard
100/100 [==============================] - 6s 56ms/step - loss: 3.0279 - masked_acc: 0.3940 - val_loss: 2.9971 - val_masked_acc: 0.3900
Epoch 35/100
98/100 [============================>.] - ETA: 0s - loss: 2.9867 - masked_acc: 0.3967
a man in a red shirt is riding a wave
a surfer rides a wave
a surfer wearing a sled is flying through the ocean
100/100 [==============================] - 6s 56ms/step - loss: 2.9850 - masked_acc: 0.3971 - val_loss: 3.0230 - val_masked_acc: 0.3842
Epoch 36/100
99/100 [============================>.] - ETA: 0s - loss: 2.9881 - masked_acc: 0.3948
a man in a red shirt is riding a wave
a person in a red vest and white surfboard sliding down a wave
a person in a bikini wetsuit gear is sitting in the ocean
100/100 [==============================] - 6s 62ms/step - loss: 2.9900 - masked_acc: 0.3945 - val_loss: 3.0418 - val_masked_acc: 0.3872
Epoch 37/100
99/100 [============================>.] - ETA: 0s - loss: 2.9784 - masked_acc: 0.3989
a man in a blue wetsuit is riding a wave
a man in a blue wetsuit is surfing
two men are racing goggles around a wave
100/100 [==============================] - 6s 59ms/step - loss: 2.9797 - masked_acc: 0.3987 - val_loss: 2.9875 - val_masked_acc: 0.3866
Epoch 38/100
100/100 [==============================] - ETA: 0s - loss: 2.9236 - masked_acc: 0.4020
a man in a yellow shirt is surfing
a man in a wetsuit is riding a wave
little child in water
100/100 [==============================] - 5s 53ms/step - loss: 2.9236 - masked_acc: 0.4020 - val_loss: 3.0202 - val_masked_acc: 0.3924
Epoch 39/100
99/100 [============================>.] - ETA: 0s - loss: 2.8908 - masked_acc: 0.4089
a man in a blue wetsuit is riding a wave
a man is riding the water
the man has ice crosses as something from the river is tossing a red paddling down
100/100 [==============================] - 6s 61ms/step - loss: 2.8921 - masked_acc: 0.4087 - val_loss: 2.9399 - val_masked_acc: 0.3967
Epoch 40/100
98/100 [============================>.] - ETA: 0s - loss: 2.8733 - masked_acc: 0.4074
a man in a red shirt is riding a wave
a man wearing a red hat is wearing a red and yellow kayak
a skier foot up the ocean
100/100 [==============================] - 6s 59ms/step - loss: 2.8742 - masked_acc: 0.4074 - val_loss: 2.9910 - val_masked_acc: 0.3861
Epoch 41/100
99/100 [============================>.] - ETA: 0s - loss: 2.8719 - masked_acc: 0.4092
a man in a red shirt is riding a wave
a man in a red jacket is swimming pool
a young girl coming out of a pool
100/100 [==============================] - 6s 55ms/step - loss: 2.8702 - masked_acc: 0.4096 - val_loss: 2.9517 - val_masked_acc: 0.3866
Epoch 42/100
98/100 [============================>.] - ETA: 0s - loss: 2.8321 - masked_acc: 0.4143
a man in a red shirt is surfing
a surfer is riding a wave
the white dog is wearing a black backpack over a surfboard
100/100 [==============================] - 5s 54ms/step - loss: 2.8329 - masked_acc: 0.4141 - val_loss: 2.9628 - val_masked_acc: 0.3983
Epoch 43/100
99/100 [============================>.] - ETA: 0s - loss: 2.8979 - masked_acc: 0.4040
a man in a red shirt is surfing
a man in a green kayak is being held by a wave
a child swims with the surfing her eyes and swimming through the blonde wave
100/100 [==============================] - 6s 63ms/step - loss: 2.8966 - masked_acc: 0.4043 - val_loss: 2.9127 - val_masked_acc: 0.4028
Epoch 44/100
99/100 [============================>.] - ETA: 0s - loss: 2.8550 - masked_acc: 0.4075
a man in a red shirt is surfing
a man in a yellow jacket is surfing on a wave
a man in the orange shirt is in the a wave
100/100 [==============================] - 6s 59ms/step - loss: 2.8571 - masked_acc: 0.4072 - val_loss: 2.8871 - val_masked_acc: 0.3977
Epoch 45/100
100/100 [==============================] - ETA: 0s - loss: 2.8514 - masked_acc: 0.4089
a man in a red shirt is surfing
a surfer in a blue wetsuit rides his surfboard
a surfer motorcyclist swimming in the wearing a red scarf in a wave
100/100 [==============================] - 6s 57ms/step - loss: 2.8514 - masked_acc: 0.4089 - val_loss: 2.9959 - val_masked_acc: 0.3842
Epoch 46/100
98/100 [============================>.] - ETA: 0s - loss: 2.8667 - masked_acc: 0.4052
a man in a red wetsuit is surfing
a man in a red wave on a surfboard
a man in a orange shirt hangs off by a wave
100/100 [==============================] - 6s 56ms/step - loss: 2.8627 - masked_acc: 0.4058 - val_loss: 2.8988 - val_masked_acc: 0.4000
Epoch 47/100
98/100 [============================>.] - ETA: 0s - loss: 2.8083 - masked_acc: 0.4139
a man in a red shirt is surfing
a man in a red shirt is riding a wave in the ocean
a surfer with a good in the surfer is falling the ocean
100/100 [==============================] - 6s 62ms/step - loss: 2.8040 - masked_acc: 0.4144 - val_loss: 2.9161 - val_masked_acc: 0.3982
Epoch 48/100
99/100 [============================>.] - ETA: 0s - loss: 2.7301 - masked_acc: 0.4216
a man in a yellow kayak is surfing
a man in a wetsuit is riding a wave
a man riding a surfboard on a surfboard
100/100 [==============================] - 5s 54ms/step - loss: 2.7277 - masked_acc: 0.4219 - val_loss: 2.9245 - val_masked_acc: 0.3871
Epoch 49/100
100/100 [==============================] - ETA: 0s - loss: 2.7509 - masked_acc: 0.4186
a surfer rides a wave
a surfer rides a wave on a surfboard
a girl kayaking through the green yellow water
100/100 [==============================] - 5s 53ms/step - loss: 2.7509 - masked_acc: 0.4186 - val_loss: 2.8690 - val_masked_acc: 0.4034
Epoch 50/100
98/100 [============================>.] - ETA: 0s - loss: 2.7516 - masked_acc: 0.4162
a man in a red shirt is surfing
a man wearing a red shirt is riding a wave
an man in a wetsuit wearing a red sweatshirt is waterskiing
100/100 [==============================] - 6s 57ms/step - loss: 2.7525 - masked_acc: 0.4162 - val_loss: 2.8848 - val_masked_acc: 0.3993
Epoch 51/100
100/100 [==============================] - ETA: 0s - loss: 2.7541 - masked_acc: 0.4177
a surfer in a red wetsuit is surfing
a surfer rides a wave
a surfer on a blue surfboard with a waterfall
100/100 [==============================] - 5s 52ms/step - loss: 2.7541 - masked_acc: 0.4177 - val_loss: 2.9027 - val_masked_acc: 0.3958
Epoch 52/100
98/100 [============================>.] - ETA: 0s - loss: 2.7264 - masked_acc: 0.4229
a man in a blue wetsuit is riding a wave
a surfer in a yellow surfboard and white uniform is surfing
a child is being splashed by some water
100/100 [==============================] - 6s 58ms/step - loss: 2.7242 - masked_acc: 0.4233 - val_loss: 2.9440 - val_masked_acc: 0.3978
Epoch 53/100
98/100 [============================>.] - ETA: 0s - loss: 2.7566 - masked_acc: 0.4163
a man in a red shirt and white surfboard
a man in a red shirt is riding a wave
a man in the swim trunks and surf
100/100 [==============================] - 6s 57ms/step - loss: 2.7552 - masked_acc: 0.4163 - val_loss: 2.8651 - val_masked_acc: 0.4078
Epoch 54/100
99/100 [============================>.] - ETA: 0s - loss: 2.7211 - masked_acc: 0.4200
a man in a red shirt is surfing
a man surfs on a wave
a board surfer in a wave
100/100 [==============================] - 5s 51ms/step - loss: 2.7197 - masked_acc: 0.4199 - val_loss: 2.8705 - val_masked_acc: 0.3978
Epoch 55/100
100/100 [==============================] - ETA: 0s - loss: 2.7130 - masked_acc: 0.4218
a man in a red shirt is riding a wave
a person in a red shirt is surfing
a rock with water in a yellow surfboard
100/100 [==============================] - 5s 54ms/step - loss: 2.7130 - masked_acc: 0.4218 - val_loss: 2.8755 - val_masked_acc: 0.4044
Epoch 56/100
99/100 [============================>.] - ETA: 0s - loss: 2.7235 - masked_acc: 0.4230
a man in a yellow kayak is surfing
a man in a yellow kayak is surfing
the surfer over a black cap is riding a backstroke in the background
100/100 [==============================] - 6s 56ms/step - loss: 2.7219 - masked_acc: 0.4230 - val_loss: 2.9409 - val_masked_acc: 0.3879
Epoch 57/100
99/100 [============================>.] - ETA: 0s - loss: 2.6688 - masked_acc: 0.4262
a surfer in a red wetsuit is surfing
a man wearing a red shirt in a yellow kayak on a surfboard
a yellow boat in the sun have up a jacked through the water team
100/100 [==============================] - 6s 63ms/step - loss: 2.6662 - masked_acc: 0.4264 - val_loss: 2.8804 - val_masked_acc: 0.3872
Epoch 58/100
98/100 [============================>.] - ETA: 0s - loss: 2.6351 - masked_acc: 0.4320
a man in a red shirt is surfing
a man in a blue white is surfing
a man rides a wave
100/100 [==============================] - 5s 50ms/step - loss: 2.6355 - masked_acc: 0.4321 - val_loss: 2.9116 - val_masked_acc: 0.3933
```
Plot the loss and accuracy over the training run:
plt.plot(history.history['loss'], label='loss')
plt.plot(history.history['val_loss'], label='val_loss')
plt.ylim([0, max(plt.ylim())])
plt.xlabel('Epoch #')
plt.ylabel('CE/token')
plt.legend()
```
```

plt.plot(history.history['masked_acc'], label='accuracy')
plt.plot(history.history['val_masked_acc'], label='val_accuracy')
plt.ylim([0, max(plt.ylim())])
plt.xlabel('Epoch #')
plt.ylabel('CE/token')
plt.legend()
```
```

## Attention plots
Now, using the trained model, run that `simple_gen` method on the image:
result = model.simple_gen(image, temperature=0.0)
result
```
'a man in a red shirt and white surfboard'
```
Split the output back into tokens:
str_tokens = result.split()
str_tokens.append('[END]')
The `DecoderLayers` each cache the attention scores for their `CrossAttention` layer. The shape of each attention map is `(batch=1, heads, sequence, image)`:
attn_maps = [layer.last_attention_scores for layer in model.decoder_layers]
[map.shape for map in attn_maps]
```
[TensorShape([1, 2, 10, 49]), TensorShape([1, 2, 10, 49])]
```
So stack the maps along the `batch` axis, then average over the `(batch, heads)` axes, while splitting the `image` axis back into `height, width`:
attention_maps = tf.concat(attn_maps, axis=0)
attention_maps = einops.reduce(
attention_maps,
'batch heads sequence (height width) -> sequence height width',
height=7, width=7,
reduction='mean')
Now you have a single attention map, for each sequence prediction. The values in each map should sum to `1.`
einops.reduce(attention_maps, 'sequence height width -> sequence', reduction='sum')
```
```
So here is where the model was focusing attention while generating each token of the output:
def plot_attention_maps(image, str_tokens, attention_map):
fig = plt.figure(figsize=(16, 9))
len_result = len(str_tokens)
titles = []
for i in range(len_result):
map = attention_map[i]
grid_size = max(int(np.ceil(len_result/2)), 2)
ax = fig.add_subplot(3, grid_size, i+1)
titles.append(ax.set_title(str_tokens[i]))
img = ax.imshow(image)
ax.imshow(map, cmap='gray', alpha=0.6, extent=img.get_extent(),
clim=[0.0, np.max(map)])
plt.tight_layout()
plot_attention_maps(image/255, str_tokens, attention_maps)

Now put that together into a more usable function:
@Captioner.add_method
def run_and_show_attention(self, image, temperature=0.0):
result_txt = self.simple_gen(image, temperature)
str_tokens = result_txt.split()
str_tokens.append('[END]')
attention_maps = [layer.last_attention_scores for layer in self.decoder_layers]
attention_maps = tf.concat(attention_maps, axis=0)
attention_maps = einops.reduce(
attention_maps,
'batch heads sequence (height width) -> sequence height width',
height=7, width=7,
reduction='mean')
plot_attention_maps(image/255, str_tokens, attention_maps)
t = plt.suptitle(result_txt)
t.set_y(1.05)
run_and_show_attention(model, image)

## Try it on your own images
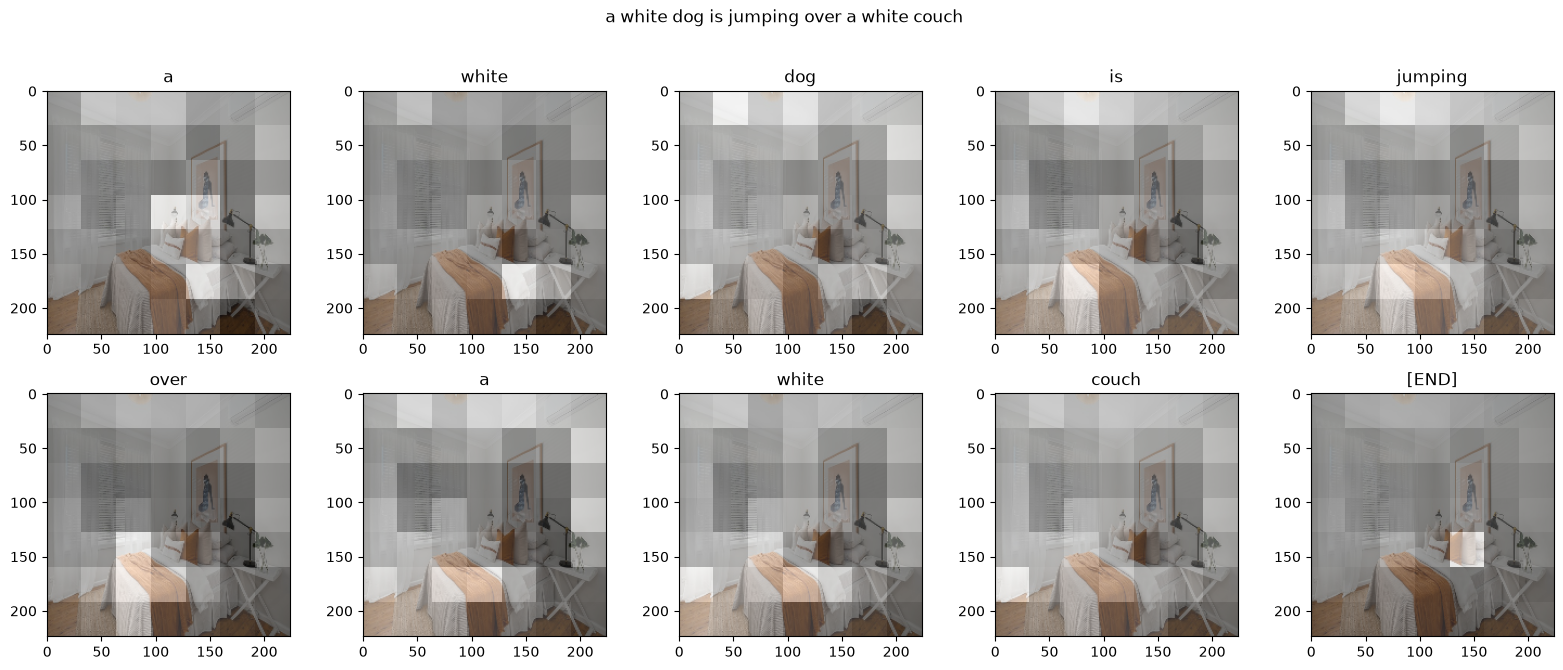
For fun, below you're provided a method you can use to caption your own images with the model you've just trained. Keep in mind, it was trained on a relatively small amount of data, and your images may be different from the training data (so be prepared for strange results!)
image_url = 'https://tensorflow.org/images/bedroom_hrnet_tutorial.jpg'
image_path = tf.keras.utils.get_file(origin=image_url)
image = load_image(image_path)
run_and_show_attention(model, image)
```
Downloading data from https://tensorflow.org/images/bedroom_hrnet_tutorial.jpg
67460/67460 [==============================] - 0s 0us/step
```